@@ -13,18 +13,25 @@
[](https://pypi.python.org/pypi/perspective-python)
[](https://crates.io/crates/perspective)
-Perspective is an interactive analytics and data visualization component for
-large, real-time and streaming datasets. Build user-configurable reports,
-dashboards, notebooks and applications, backed by a high-performance streaming
-query engine that runs in-browser via WebAssembly or server-side in Python,
-Node.js and Rust — or delegates to a database you already have.
+
+
+Perspective is an open-source data grid, pivot table and charting component for
+large, real-time and streaming datasets. Build user-configurable reports,
+dashboards, notebooks and embedded analytics applications, backed by a
+high-performance streaming query engine that runs in-browser via WebAssembly or
+server-side in Python, Node.js and Rust — or delegates to a database you
+already have.
+
+
-
+
+
+
## Features
- A data-reactive UI packaged as a
@@ -35,7 +42,8 @@ Node.js and Rust — or delegates to a database you already have.
- A fast, memory-efficient streaming query engine written in C++ and compiled
for [WebAssembly](https://webassembly.org/) (including a 64-bit `memory64`
- build for in-browser datasets larger than 4GB),
+ build for in-browser datasets larger than 4GB, and support for paging
+ columns to disk via OPFS in the browser or memory-mapped files natively),
[Python](https://www.python.org/) and [Rust](https://www.rust-lang.org/).
Tables update incrementally and views tick in real time, with reactive
joins across tables, a columnar expression language based on
@@ -90,25 +98,25 @@ Node.js and Rust — or delegates to a database you already have.
Superstore
Workspace
Webcam
-
-
-
+
+
+
Raycasting
Market
NYPD
-
-
-
+
+
+
Movies
Evictions
Fractal
-
-
-
+
+
+
@@ -122,9 +130,9 @@ Node.js and Rust — or delegates to a database you already have.
${projects.length} live, editable examples of Perspective data grids, pivot tables, WebGL charts, maps and real-time dashboards. Every example runs entirely in the browser on WebAssembly.
+ ${groups.join("\n")}
+ ${linksHtml()}`);
+}
+
+/**
+ * The Project corpus and per-source descriptions, bundled out of the app's
+ * TypeScript so the build and the app read one definition.
+ */
+export async function loadCorpus() {
+ const result = await esbuild.build({
+ stdin: {
+ contents:
+ 'export { PROJECTS } from "./corpus.ts";\n' +
+ 'export { SOURCE_DESCRIPTIONS } from "./descriptions.ts";\n' +
+ 'export { HOME_TITLE, pageTitle } from "./types.ts";',
+ resolveDir: PROJECTS_SRC,
+ loader: "ts",
+ },
+ bundle: true,
+ write: false,
+ format: "esm",
+ platform: "node",
+ logLevel: "silent",
+ });
+
+ const code = Buffer.from(result.outputFiles[0].contents).toString("base64");
+ return import(`data:text/javascript;base64,${code}`);
+}
+
+function fill(template, head, about) {
+ if (!template.includes(HEAD_SLOT) || !template.includes(ABOUT_SLOT)) {
+ throw new Error(`index.html is missing ${HEAD_SLOT} or ${ABOUT_SLOT}`);
+ }
+
+ return template.replace(HEAD_SLOT, head).replace(ABOUT_SLOT, about);
+}
+
+/**
+ * Write `index.html`, one `gallery/.html` per described Project and
+ * `gallery/index.html` — each the app's own HTML with its `` and
+ * About dialog filled in.
+ *
+ * @param template the contents of `src/index.html`.
+ * @param dist the output directory.
+ * @returns the site-relative URLs written.
+ */
+export async function writePages(template, dist) {
+ const { PROJECTS, SOURCE_DESCRIPTIONS, HOME_TITLE, pageTitle } =
+ await loadCorpus();
+ const summaries = new Map(
+ PROJECTS.map((p) => [p.id, describeWorkspace(p.workspace)]),
+ );
+
+ const home = fill(
+ template,
+ headTags({
+ title: HOME_TITLE,
+ description: SENTENCE,
+ url: "/",
+ image: "/projects/light/collage.png",
+ jsonld: homeJsonLd(),
+ }),
+ homeAbout(PROJECTS),
+ );
+
+ fs.writeFileSync(path.join(dist, "index.html"), home);
+ fs.mkdirSync(path.join(dist, "gallery"), { recursive: true });
+ const urls = ["/", "/gallery/index.html"];
+ const listed = [];
+ for (const project of PROJECTS) {
+ const sourceText = SOURCE_DESCRIPTIONS[project.source.name];
+ if (!sourceText) {
+ console.warn(
+ `No source description for "${project.source.name}"; ` +
+ `skipping gallery/${project.id}.html`,
+ );
+
+ continue;
+ }
+
+ const summary = summaries.get(project.id);
+ const page = fill(
+ template,
+ headTags({
+ title: pageTitle(project),
+ description: `${summary} ${sourceText}`,
+ url: galleryUrl(project),
+ image: `/projects/light/${project.id}.png`,
+ }),
+ projectAbout(project, summary, sourceText),
+ );
+
+ fs.writeFileSync(
+ path.join(dist, "gallery", `${project.id}.html`),
+ page,
+ );
+ urls.push(galleryUrl(project));
+ listed.push(project);
+ }
+
+ const gallery = fill(
+ template,
+ headTags({
+ title: `Example gallery — ${BRAND} data grids, pivot tables and charts`,
+ description: `${listed.length} live examples of Perspective data grids, pivot tables, WebGL charts, maps and real-time dashboards, running in the browser on WebAssembly.`,
+ url: "/gallery/index.html",
+ image: "/projects/light/collage.png",
+ }),
+ galleryAbout(listed, summaries),
+ );
+
+ fs.writeFileSync(path.join(dist, "gallery", "index.html"), gallery);
+ return urls;
+}
+
+function walk(dir, test, found = []) {
+ if (!fs.existsSync(dir)) {
+ return found;
+ }
+
+ for (const child of fs.readdirSync(dir, { withFileTypes: true })) {
+ const full = path.join(dir, child.name);
+ if (child.name === "node_modules") {
+ continue;
+ }
+
+ if (child.isDirectory()) {
+ walk(full, test, found);
+ } else if (test(full)) {
+ found.push(full);
+ }
+ }
+
+ return found;
+}
+
+function guideTitles() {
+ const summary = fs.readFileSync(path.join(GUIDE_SRC, "SUMMARY.md"), "utf8");
+ const entries = [];
+ let section = "Overview";
+ for (const line of summary.split("\n")) {
+ const heading = /^# (.+)$/.exec(line);
+ const link = /\[(.+?)\]\(\.\/(.+?)\.md\)/.exec(line);
+ if (heading && heading[1] !== "Summary") {
+ section = heading[1];
+ } else if (link) {
+ entries.push({
+ section,
+ title: link[1].replaceAll("`", ""),
+ file: link[2],
+ });
+ }
+ }
+
+ return entries;
+}
+
+const ENTITIES = {
+ "&": "&",
+ "<": "<",
+ ">": ">",
+ """: '"',
+ "'": "'",
+ "'": "'",
+};
+
+function plainText(html) {
+ return html
+ .replace(/<[^>]+>/g, "")
+ .replace(/&(?:amp|lt|gt|quot|#x27|#39);/g, (x) => ENTITIES[x])
+ .replace(/\s+/g, " ")
+ .trim();
+}
+
+function truncate(text, max = 300) {
+ return text.length > max
+ ? `${text.slice(0, max - 1).replace(/\s+\S*$/, "")}…`
+ : text;
+}
+
+function pageDescription(html) {
+ const authored = //.exec(html);
+ if (authored) {
+ return truncate(plainText(authored[1]));
+ }
+
+ const main = /([\s\S]*?)<\/main>/.exec(html)?.[1] ?? "";
+ for (const match of main.matchAll(/
([\s\S]*?)<\/p>/g)) {
+ const text = plainText(match[1]);
+ if (text.length >= 40) {
+ return truncate(text);
+ }
+ }
+
+ return SENTENCE;
+}
+
+function faqJsonLd(html) {
+ const main = /([\s\S]*?)<\/main>/.exec(html)?.[1] ?? "";
+ const pairs = main.matchAll(
+ /]*>([\s\S]*?)<\/h3>([\s\S]*?)(?=]|$)/g,
+ );
+
+ const questions = [...pairs]
+ .map(([, question, answer]) => ({
+ "@type": "Question",
+ name: plainText(question),
+ acceptedAnswer: { "@type": "Answer", text: plainText(answer) },
+ }))
+ .filter((x) => x.acceptedAnswer.text.length > 0);
+
+ return {
+ "@context": "https://schema.org",
+ "@type": "FAQPage",
+ mainEntity: questions,
+ };
+}
+
+const GUIDE_SUFFIX = "Perspective data grid, pivot table & charts";
+
+const GUIDE_LANGUAGES = new Set(["JavaScript", "Python", "Rust"]);
+
+const GUIDE_HEADINGS = new Map([
+ ["perspective", "What is Perspective"],
+ ["explanation/table", "Table: streaming, columnar data storage"],
+ ["explanation/view", "View: live pivots, aggregates, filters and sorts"],
+ ["explanation/join", "Join: reactive joins across streaming tables"],
+ ["explanation/view/config/expressions", "Expression columns"],
+ [
+ "explanation/virtual_servers",
+ "Virtual servers: Perspective over your database",
+ ],
+]);
+
+function guideHeading(entry) {
+ const heading = GUIDE_HEADINGS.get(entry.file) ?? entry.title;
+ return GUIDE_LANGUAGES.has(entry.section)
+ ? `${heading} (${entry.section})`
+ : heading;
+}
+
+const GUIDE_ALIASES = new Map([["perspective.html", "index.html"]]);
+
+/**
+ * Give every mdBook page a description, canonical URL, share tags,
+ * breadcrumbs and a Markdown alternate; `noindex` the print page; and
+ * publish each page's Markdown source beside it.
+ *
+ * @param dist the output directory holding `guide/`.
+ * @returns the site-relative URLs of the indexable guide pages.
+ */
+export function postprocessGuide(dist) {
+ const guide = path.join(dist, "guide");
+ const entries = new Map(guideTitles().map((x) => [`${x.file}.html`, x]));
+ const urls = [];
+ for (const file of walk(guide, (x) => x.endsWith(".html"))) {
+ const rel = path.relative(guide, file).split(path.sep).join("/");
+ let html = fs.readFileSync(file, "utf8");
+ if (rel === "print.html" || rel === "404.html" || rel === "toc.html") {
+ if (!html.includes('name="robots"')) {
+ html = html.replace(
+ "",
+ ` \n `,
+ );
+
+ fs.writeFileSync(file, html);
+ }
+
+ continue;
+ }
+
+ const canonical = `/guide/${GUIDE_ALIASES.get(rel) ?? rel}`;
+ if (!GUIDE_ALIASES.has(rel)) {
+ urls.push(canonical);
+ }
+
+ if (html.includes('rel="canonical"')) {
+ continue;
+ }
+
+ const entry = entries.get(
+ rel === "index.html" ? "perspective.html" : rel,
+ );
+ const heading = entry ? guideHeading(entry) : BRAND;
+ const title = `${heading} — ${GUIDE_SUFFIX}`;
+ const description = pageDescription(html);
+ const markdown = entry ? `/guide/${entry.file}.md` : null;
+ const crumbs = entry && {
+ "@context": "https://schema.org",
+ "@type": "BreadcrumbList",
+ itemListElement: [
+ { name: BRAND, item: `${SITE}/` },
+ { name: "Guide", item: `${SITE}/guide/index.html` },
+ { name: entry.section },
+ { name: entry.title, item: SITE + canonical },
+ ].map((x, i) => ({ "@type": "ListItem", position: i + 1, ...x })),
+ };
+
+ const tags = [
+ ``,
+ ``,
+ ``,
+ ``,
+ ``,
+ ``,
+ ``,
+ ``,
+ ``,
+ markdown &&
+ ``,
+ crumbs && jsonLd(crumbs),
+ rel === "FAQ.html" && jsonLd(faqJsonLd(html)),
+ ].filter(Boolean);
+
+ html = html
+ .replace(
+ /[\s\S]*?<\/title>/,
+ `<title>${escapeHtml(title)}`,
+ )
+ .replace(/\s*/, "")
+ .replace("", ` ${tags.join("\n ")}\n `);
+
+ fs.writeFileSync(file, html);
+ }
+
+ for (const file of walk(GUIDE_SRC, (x) => x.endsWith(".md"))) {
+ const rel = path.relative(GUIDE_SRC, file);
+ if (rel === "SUMMARY.md") {
+ continue;
+ }
+
+ const out = path.join(guide, rel);
+ fs.mkdirSync(path.dirname(out), { recursive: true });
+ fs.writeFileSync(out, expandIncludes(file));
+ }
+
+ return urls;
+}
+
+function expandIncludes(file) {
+ return fs
+ .readFileSync(file, "utf8")
+ .replace(/\{\{#include (.+?)\}\}/g, (_, target) =>
+ fs.readFileSync(path.resolve(path.dirname(file), target), "utf8"),
+ );
+}
+
+/**
+ * Write `llms.txt`, an annotated index of the guide, and `llms-full.txt`,
+ * the whole guide as one Markdown document.
+ *
+ * @param dist the output directory.
+ */
+export function writeLlms(dist) {
+ const entries = guideTitles();
+ const index = [`# ${BRAND}`, "", `> ${SENTENCE}`, ""];
+ index.push(
+ "Perspective is Apache-2.0 licensed and a member project of the OpenJS Foundation. " +
+ "npm packages are published under `@perspective-dev/*` (formerly `@finos/perspective*`); " +
+ "the Python package is `perspective-python`; the Rust crate is `perspective`.",
+ "",
+ );
+
+ let section = null;
+ for (const entry of entries) {
+ if (entry.section !== section) {
+ section = entry.section;
+ index.push("", `## ${section}`, "");
+ }
+
+ index.push(`- [${entry.title}](${SITE}/guide/${entry.file}.md)`);
+ }
+
+ index.push(
+ "",
+ "## Examples",
+ "",
+ `- [Example gallery](${SITE}/gallery/index.html): live examples, each with its full viewer configuration as JSON`,
+ "",
+ "## Optional",
+ "",
+ `- [Full guide as one document](${SITE}/llms-full.txt)`,
+ `- [Source code](${REPO})`,
+ `- [Changelog](${REPO}/blob/master/CHANGELOG.md)`,
+ "",
+ );
+
+ fs.writeFileSync(path.join(dist, "llms.txt"), index.join("\n"));
+ const full = entries.map((entry) => {
+ const file = path.join(GUIDE_SRC, `${entry.file}.md`);
+ return fs.existsSync(file) ? expandIncludes(file) : "";
+ });
+
+ fs.writeFileSync(
+ path.join(dist, "llms-full.txt"),
+ [`# ${BRAND}`, "", `> ${SENTENCE}`, "", ...full].join("\n\n"),
+ );
+}
+
+/**
+ * Write `robots.txt` and `sitemap.xml`.
+ *
+ * @param dist the output directory.
+ * @param urls the site-relative URLs to list.
+ */
+export function writeCrawlFiles(dist, urls) {
+ const agents = ["*", ...AI_CRAWLERS].map(
+ (agent) =>
+ `User-agent: ${agent}\nAllow: /\nDisallow: /guide/print.html\n`,
+ );
+
+ fs.writeFileSync(
+ path.join(dist, "robots.txt"),
+ `${agents.join("\n")}\nSitemap: ${SITE}/sitemap.xml\n`,
+ );
+
+ const today = new Date().toISOString().slice(0, 10);
+ const rows = [...new Set(urls)].map(
+ (url) =>
+ ` ${escapeHtml(SITE + url)}${today}`,
+ );
+
+ fs.writeFileSync(
+ path.join(dist, "sitemap.xml"),
+ `\n` +
+ `\n` +
+ `${rows.join("\n")}\n\n`,
+ );
+}
diff --git a/docs/md/FAQ.md b/docs/md/FAQ.md
index 55c08702f8..709a74449e 100644
--- a/docs/md/FAQ.md
+++ b/docs/md/FAQ.md
@@ -1,5 +1,7 @@
# FAQ
+
+
## Installation
### Python installation fails on Windows
@@ -270,8 +272,10 @@ depending on the number of columns and available memory. Performance also
significantly depends on column types (`"string"` being slower and larger than
other types due to dictionary interning).
-For larger datasets or out-of-memory virtualized datasets, see
-[Virtual Servers](./explanation/virtual_servers.md).
+For tables larger than the engine's memory, create the `Table` with
+[`page_to_disk`](./explanation/table/options.md#page_to_disk), which pages
+columns out to disk (OPFS in the browser). For datasets which should not be
+loaded at all, see [Virtual Servers](./explanation/virtual_servers.md).
+
+Perspective's performance is tracked by a benchmark suite which lives in the
+repository. CI runs it on every tagged release and attaches the raw results to
+that
+[GitHub release](https://github.com/perspective-dev/perspective/releases/latest)
+as Apache Arrow files — and the results are, naturally, explored in
+Perspective.
+
+## Results
+
+Open the published results for the latest release, live in your browser:
+
+| Build | Dashboard | By release | Raw data |
+| --- | --- | --- | --- |
+| JavaScript (WebAssembly engine under Node.js) | [Benchmarks — JavaScript](https://perspective-dev.github.io/gallery/benchmarks-js.html) | [History](https://perspective-dev.github.io/gallery/benchmarks-js-history.html) | [`benchmark-js.arrow`](https://github.com/perspective-dev/perspective/releases/latest/download/benchmark-js.arrow) |
+| Python (native engine, driven over WebSocket) | [Benchmarks — Python](https://perspective-dev.github.io/gallery/benchmarks-python.html) | [History](https://perspective-dev.github.io/gallery/benchmarks-python-history.html) | [`benchmark-python.arrow`](https://github.com/perspective-dev/perspective/releases/latest/download/benchmark-python.arrow) |
+
+Each file holds one row per timed iteration:
+
+| Column | Meaning |
+| --- | --- |
+| `benchmark` | The case, e.g. `.view({group_by})` |
+| `version` | The Perspective release the case ran against |
+| `version_idx` | Release order; `0` is the build being released |
+| `real_time`, `cpu_time`, `user_time`, `system_time` | Microseconds |
+| `outlier` | `true` when the iteration falls outside 1.5 × the interquartile range of its case |
+
+The dashboards are ordinary Perspective views over that file — mean
+`real_time` in milliseconds, excluding outliers, grouped by `benchmark` and
+`version` — so they can be re-pivoted, filtered to one case, or switched to
+another chart type in place.
+
+**Environment.** Results are produced by GitHub Actions on an `ubuntu-22.04`
+x86_64 hosted runner with Node.js 22 and Python 3.11, over the Superstore
+sample dataset. Hosted runners are shared, modest machines: read these numbers
+as a release-over-release trend on constant hardware, not as the ceiling for
+your own.
+
+## What is measured
+
+The cross-platform suite (`tools/bench/cross_platform_suite.mjs`) defines the
+cases, which are written against the `Client` API and so can be pointed at any
+build of the engine:
+
+| Area | Cases |
+| --- | --- |
+| Table construction | `table(arrow)`, `table(csv)`, `table(json)`, `table(columns)`, and `table(arrow, {limit})` |
+| Streaming | `table.update(arrow)`, and `table.update(arrow)` with window columns active |
+| Queries | `view()`, `view({group_by})`, `view({group_by, aggregates: "median"})`, `view({expressions})`, `view({windows})` |
+| Joins | `join()` |
+| Serialization | `to_arrow()`, `to_csv()`, `to_columns()`, `to_json()` |
+
+A separate suite (`charts_suite.mjs`) measures chart rendering in a real
+browser.
+
+Each case is run repeatedly against the current build _and_ against
+previously published releases, so every number can be read relative to the
+versions before it. Results are written as Apache Arrow files under
+`tools/bench/dist/`.
+
+## Running it
+
+From a built checkout of the
+[repository](https://github.com/perspective-dev/perspective):
+
+```bash
+cd tools/bench
+pnpm run bench_js
+pnpm run bench_python
+pnpm run bench_charts
+```
+
+## Reading results sensibly
+
+- **Arrow is the fast path.** Loading Arrow avoids parsing and type inference;
+ CSV and JSON construction times measure the parser as much as the engine.
+- **Column types matter more than row count.** Numeric and datetime columns
+ are fixed-width; string columns are dictionary-encoded and cost more to
+ build and to group.
+- **Updates scale with the delta.** The cost of `update()` on a table with
+ active views is driven by the size of the update and the number of groups it
+ touches, not by the size of the table.
+- **WebAssembly is single-threaded per worker; native is not.** The Python,
+ Node.js and Rust builds use a thread pool (`perspective.set_num_cpus()`), so
+ native numbers are typically better than in-browser numbers for the same
+ case.
+- **Rendering is separate from querying.** The data grid draws only the cells
+ in view, so a grid over ten million rows renders in the same time as one over
+ ten thousand; the query is what scales.
+
+For guidance on sizing, see
+[Visualizing millions of rows in the browser](./use_cases/large_datasets.md).
diff --git a/docs/md/explanation/table/options.md b/docs/md/explanation/table/options.md
index e18d50db46..f14259057f 100644
--- a/docs/md/explanation/table/options.md
+++ b/docs/md/explanation/table/options.md
@@ -57,3 +57,40 @@ limit_table = perspective.Table(data, limit=1000);
```
+
+## `page_to_disk`
+
+By default a `Table` keeps its columns in memory. Initializing a `Table` with
+`page_to_disk` backs its column data with on-disk storage instead, so the
+`Table` can be larger than the memory available to the engine. It is otherwise
+an ordinary `Table`: `index`, `update()`, views, aggregates, expressions and
+Arrow round-trips all behave as they do in memory, and produce identical
+results.
+
+
+
+Where the data goes depends on the runtime:
+
+| Runtime | Backing storage |
+| --- | --- |
+| Browser (WebAssembly, in a Web Worker) | The [Origin Private File System](https://developer.mozilla.org/en-US/docs/Web/API/File_System_API/Origin_private_file_system) (OPFS) |
+| Node.js (WebAssembly) | Files under the OS temp directory, via `node:fs` |
+| Python and Rust (native) | Memory-mapped files under the OS temp directory |
+
diff --git a/docs/md/glossary.md b/docs/md/glossary.md
new file mode 100644
index 0000000000..5df7bd8e4a
--- /dev/null
+++ b/docs/md/glossary.md
@@ -0,0 +1,143 @@
+# Glossary
+
+
+
+Short definitions of the terms used throughout this guide.
+
+## Data grid
+
+A scrollable, sortable table of rows and columns rendered in a user interface.
+Perspective's data grid, the
+[Datagrid plugin](https://www.npmjs.com/package/@perspective-dev/viewer-datagrid),
+is _virtualized_: it renders only the visible cells, so its cost is independent
+of the number of rows.
+
+## Pivot table
+
+A table which groups rows by one or more columns (row pivots), optionally
+splits them across the distinct values of other columns (column pivots), and
+shows an aggregate in each cell. In Perspective, row pivots are `group_by` and
+column pivots are `split_by`. See
+[Grouping and Pivots](./explanation/view/config/grouping_and_pivots.md).
+
+## Streaming pivot table
+
+A pivot table whose groups and aggregates are updated incrementally as rows
+are inserted, updated or removed, rather than recomputed. See
+[Streaming pivot tables](./use_cases/streaming_pivot_table.md).
+
+## `Table`
+
+Perspective's columnar, typed data store. A [`Table`](./explanation/table.md)
+is created from a schema or a dataset (Apache Arrow, CSV, JSON, or a DataFrame
+in Python), and modified with `update()`, `remove()`, `clear()` and
+`replace()`.
+
+## `View`
+
+A continuous query over a `Table`: a combination of `group_by`, `split_by`,
+`columns`, `aggregates`, `filter`, `sort` and `expressions`. A
+[`View`](./explanation/view.md) stays current as its `Table` changes and
+notifies `on_update` subscribers.
+
+## `group_by`
+
+The columns whose distinct values become the rows of a pivot. Multiple levels
+form an expandable tree with subtotals.
+
+## `split_by`
+
+The columns whose distinct values become the column headers of a pivot.
+
+## Aggregate
+
+The function which reduces a group's values to one cell — `sum`, `avg`,
+`count`, `distinct count`, `median`, `weighted mean`, `first`, `last` and
+others. Chosen per column.
+
+## Expression column
+
+A computed column defined in Perspective's
+[expression language](./explanation/view/config/expressions.md), based on
+ExprTK. Expressions are evaluated column-wise inside the engine and can be
+grouped, filtered, sorted and aggregated like stored columns.
+
+## Index
+
+A `Table` option naming a primary key column. Updates to an indexed table
+replace the row with the matching key (and may be partial); without an index,
+updates append. See [`index` and `limit`](./explanation/table/options.md).
+
+## Limit
+
+A `Table` option which keeps only the most recent _n_ rows, for rolling
+windows over unbounded streams.
+
+## `page_to_disk`
+
+A `Table` option which backs the table's columns with on-disk storage — the
+Origin Private File System in the browser, memory-mapped files natively — so
+a `Table` can exceed the engine's memory. See
+[`page_to_disk`](./explanation/table/options.md#page_to_disk).
+
+## ``
+
+The Web Component (Custom Element) providing Perspective's user interface:
+configuration panel, plugins, themes, multi-panel layout and save/restore.
+
+## Plugin
+
+A visualization hosted by `` — the Datagrid, or one of
+the WebGL charts (bar, line, area, scatter, heatmap, treemap, sunburst,
+candlestick, OHLC, maps).
+
+## Client, Server
+
+A `Server` owns tables and executes queries. A `Client` is a handle to a
+`Server`, whether that server is in the same process, in a Web Worker, or
+across a WebSocket. The API is the same in every case.
+
+## Client-only mode
+
+The engine runs in the browser as WebAssembly in a Web Worker; no server is
+involved. See [Client-only](./explanation/architecture/client_only.md).
+
+## Client/server replicated mode
+
+A server owns the authoritative `Table`; each browser keeps a synchronized
+copy and queries it locally. See
+[Client/Server replicated](./explanation/architecture/client_server.md).
+
+## Server-only mode
+
+Queries run on the server and the browser receives only the rows it is
+displaying. See [Server only](./explanation/architecture/server_only.md).
+
+## Virtual server
+
+An implementation of Perspective's protocol over an external query engine,
+such as DuckDB, ClickHouse, PostgreSQL or Polars, which translates view
+configurations into that engine's native queries. See
+[Virtual Servers](./explanation/virtual_servers.md).
+
+## Virtual scrolling
+
+Rendering only the rows and columns currently in the viewport, and fetching
+more as the user scrolls.
+
+## Apache Arrow
+
+A language-independent columnar memory format. It is Perspective's preferred
+interchange format: it loads without parsing and preserves types.
+
+## WebAssembly
+
+A portable binary instruction format which runs at near-native speed in
+browsers. Perspective's C++ query engine and Rust UI are both compiled to
+WebAssembly.
+
+## Memory64
+
+A WebAssembly extension for 64-bit memory addressing. Perspective ships an
+optional Memory64 engine build which raises the in-browser heap limit from
+4GB to 16GB.
diff --git a/docs/md/integrations/fastapi.md b/docs/md/integrations/fastapi.md
new file mode 100644
index 0000000000..2dca93fed0
--- /dev/null
+++ b/docs/md/integrations/fastapi.md
@@ -0,0 +1,69 @@
+# Perspective with FastAPI and Starlette
+
+
+
+`perspective-python` includes a WebSocket handler for
+[Starlette](https://www.starlette.io/), and therefore
+[FastAPI](https://fastapi.tiangolo.com/). Add one WebSocket route and every
+`Table` hosted by your `perspective.Server` is available to
+`` clients in the browser.
+
+```bash
+pip install "perspective-python[starlette]" fastapi uvicorn
+```
+
+```python
+import uvicorn
+from fastapi import FastAPI, WebSocket
+from perspective import Server
+from perspective.handlers.starlette import PerspectiveStarletteHandler
+
+server = Server()
+client = server.new_local_client()
+table = client.table(
+ {"symbol": "string", "price": "float", "time": "datetime"},
+ index="symbol",
+ name="prices",
+)
+
+app = FastAPI()
+
+async def websocket_handler(websocket: WebSocket):
+ handler = PerspectiveStarletteHandler(
+ perspective_server=server,
+ websocket=websocket,
+ )
+
+ await handler.run()
+
+app.add_api_websocket_route("/websocket", websocket_handler)
+
+if __name__ == "__main__":
+ uvicorn.run(app, host="0.0.0.0", port=8080)
+```
+
+Anything in your application can now write to the table — a REST endpoint, a
+background task, a queue consumer:
+
+```python
+@app.post("/ticks")
+async def ticks(rows: list[dict]):
+ table.update(rows)
+```
+
+In the browser:
+
+```javascript
+const websocket = await perspective.websocket("ws://localhost:8080/websocket");
+const table = await websocket.open_table("prices");
+await document.querySelector("perspective-viewer").load(table);
+```
+
+Every connected viewer updates as `table.update()` is called.
+
+- [Hosting a WebSocket server](../how_to/python/websocket.md) — replicated vs
+ server-only modes.
+- [Multithreading](../how_to/python/multithreading.md) — the `executor`
+ handler argument and `on_poll_request`.
+- [Real-time dashboards over WebSocket](../use_cases/real_time_dashboard.md)
+- [`python-starlette` example](https://github.com/perspective-dev/perspective/tree/master/examples/python-starlette)
diff --git a/docs/md/integrations/frameworks.md b/docs/md/integrations/frameworks.md
new file mode 100644
index 0000000000..d94fdc550f
--- /dev/null
+++ b/docs/md/integrations/frameworks.md
@@ -0,0 +1,104 @@
+# Perspective with Next.js, Vue, Svelte and Angular
+
+
+
+`` is a standard Web Component, so it works in any
+framework which can render a DOM element and call a method on it. React has a
+[dedicated wrapper](../how_to/javascript/react.md); elsewhere, use the element
+directly.
+
+Three rules apply everywhere:
+
+1. **Initialize WebAssembly once**, before first use, as described in
+ [Importing with or without a bundler](../how_to/javascript/importing.md).
+2. **Client-side only.** Perspective needs Web Workers and WebAssembly, so it
+ cannot be server-rendered.
+3. **`load()` is a method, not an attribute.** Get a reference to the element
+ and call `viewer.load(table)`; use `viewer.restore(config)` for
+ configuration.
+
+## Next.js
+
+Load the component with `next/dynamic` and `ssr: false`, so Perspective is
+only imported in the browser:
+
+```tsx
+import dynamic from "next/dynamic";
+
+const Report = dynamic(() => import("../components/Report"), { ssr: false });
+```
+
+`components/Report.tsx` then uses
+[`@perspective-dev/react`](../how_to/javascript/react.md) as normal.
+
+## Vue
+
+Tell the template compiler that `perspective-viewer` is a custom element:
+
+```javascript
+// vite.config.js
+vue({
+ template: {
+ compilerOptions: {
+ isCustomElement: (tag) => tag.startsWith("perspective-"),
+ },
+ },
+});
+```
+
+```html
+
+
+
+
+
+```
+
+## Svelte
+
+```html
+
+
+
+```
+
+## Angular
+
+Add `CUSTOM_ELEMENTS_SCHEMA` to the component or module, and reach the element
+with `@ViewChild`:
+
+```typescript
+@Component({
+ selector: "app-report",
+ template: ``,
+ schemas: [CUSTOM_ELEMENTS_SCHEMA],
+})
+export class ReportComponent implements AfterViewInit {
+ @ViewChild("viewer") viewer!: ElementRef;
+
+ async ngAfterViewInit() {
+ await this.viewer.nativeElement.load(table);
+ }
+}
+```
+
+## Cleaning up
+
+When the component unmounts, call `viewer.delete()`, and `delete()` any
+`View` and `Table` you created, in that order. See
+[Cleaning up resources](../how_to/javascript/deleting.md).
diff --git a/docs/md/integrations/kafka.md b/docs/md/integrations/kafka.md
new file mode 100644
index 0000000000..aad3783844
--- /dev/null
+++ b/docs/md/integrations/kafka.md
@@ -0,0 +1,70 @@
+# Perspective with Kafka and other message queues
+
+
+
+Perspective has no queue-specific connector because it does not need one: a
+[`Table`](../explanation/table.md) is updated by calling `update()`, so any
+consumer loop is an integration. The pattern is the same for Kafka, Redpanda,
+NATS, RabbitMQ, Redis streams or a WebSocket feed.
+
+1. Create a `Table` from a schema, on a `perspective.Server`.
+2. Consume messages, batch them, and call `table.update(batch)`.
+3. Host the server on a WebSocket so browsers can open the table.
+
+## Python
+
+```python
+import json
+import threading
+
+import tornado.ioloop
+import tornado.web
+from confluent_kafka import Consumer
+from perspective import Server
+from perspective.handlers.tornado import PerspectiveTornadoHandler
+
+server = Server()
+client = server.new_local_client()
+table = client.table(
+ {"order_id": "string", "symbol": "string", "qty": "integer", "price": "float", "ts": "datetime"},
+ index="order_id",
+ name="orders",
+)
+
+def consume():
+ consumer = Consumer({"bootstrap.servers": "localhost:9092", "group.id": "perspective"})
+ consumer.subscribe(["orders"])
+ while True:
+ messages = consumer.consume(num_messages=500, timeout=0.1)
+ rows = [json.loads(m.value()) for m in messages if m.error() is None]
+ if rows:
+ table.update(rows)
+
+threading.Thread(target=consume, daemon=True).start()
+
+app = tornado.web.Application([
+ (r"/websocket", PerspectiveTornadoHandler, {"perspective_server": server}),
+])
+
+app.listen(8080)
+tornado.ioloop.IOLoop.current().start()
+```
+
+`confluent_kafka` is used here for illustration; nothing in Perspective depends
+on it.
+
+## Design notes
+
+- **Batch.** One `update()` of 500 rows is much cheaper than 500 updates of
+ one row. Consume in small time windows, as above.
+- **Pick `index` or `limit`.** A topic is unbounded; a browser is not. Use
+ [`index`](../explanation/table/options.md) when messages are upserts to
+ entities (orders, positions, devices), and `limit` when they are events and
+ you want the most recent _n_.
+- **Threads are fine.** Perspective's Python API is thread-safe and releases
+ the GIL. See [Multithreading](../how_to/python/multithreading.md).
+- **Arrow if you have it.** If your messages are already Arrow record batches,
+ pass the bytes straight to `update()`.
+
+The browser side is identical to any other server-hosted table; see
+[Real-time dashboards over WebSocket](../use_cases/real_time_dashboard.md).
diff --git a/docs/md/use_cases/agent.md b/docs/md/use_cases/agent.md
new file mode 100644
index 0000000000..14f8187690
--- /dev/null
+++ b/docs/md/use_cases/agent.md
@@ -0,0 +1,63 @@
+# LLM and agent-driven analytics
+
+
+
+`` ships with an embedded LLM agent. A user types "show me
+monthly revenue by region as a stacked bar, top five only", and the agent
+reads the table's schema, writes the view configuration, authors any computed
+columns it needs, picks the chart, and applies it — through the same public
+API your own code would use.
+
+It is **opt-in**. The Chat tab stays hidden and no network request is made
+until you configure a model:
+
+```javascript
+import { providers } from "@perspective-dev/viewer";
+
+const viewer = document.querySelector("perspective-viewer");
+viewer.agentConfig({
+ ...providers.anthropic,
+ apiKey: "sk-ant-...",
+});
+```
+
+## Why an agent fits Perspective
+
+An LLM is good at translating intent into a small, structured configuration,
+and unreliable at arithmetic over data it has to read. Perspective's
+configuration is exactly that kind of target: a complete analysis — grouping,
+column splits, aggregates, filters, sorts, expressions, chart type — is a few
+lines of JSON, and the numbers are computed by the engine, not the model.
+
+- The agent's tools read the table's schema and the viewer's configuration —
+ none of them read rows, so your data is not sent to the model.
+- Every answer is an ordinary, inspectable viewer configuration. The user can
+ see exactly what was grouped and filtered, adjust it by hand, and save it.
+- Because the engine is incremental, an agent-built view over streaming data
+ keeps updating after the conversation ends.
+
+## Any model, including local ones
+
+The agent speaks the OpenAI chat-completions convention, so it works with
+Anthropic, OpenAI, Gemini and OpenRouter endpoints, with local servers such as
+[Ollama](https://ollama.com/), [LM Studio](https://lmstudio.ai/), llama.cpp and
+vLLM, and with in-page engines such as
+[WebLLM](https://github.com/mlc-ai/web-llm) — in which case the data, the
+query engine and the model all run inside the browser tab.
+
+## Keys and production use
+
+A key passed to `agentConfig` is a key in the browser. That is fine for local
+development and internal tools; for anything shared, point `url` at a proxy
+you control and keep the credential on the server. See
+[Configuring the LLM agent](../how_to/javascript/agent.md) for the full
+connection options.
+
+## Driving Perspective from your own agent
+
+The agent uses no private hooks. `restore()`, `save()`, `Table.schema()` and
+`View` are the complete surface, and a view configuration is plain JSON — so
+an external agent, a notebook assistant or an MCP tool can produce the same
+results by emitting a `ViewerConfig`. The guide is published for that purpose
+as Markdown at [`/llms.txt`](https://perspective-dev.github.io/llms.txt) and
+[`/llms-full.txt`](https://perspective-dev.github.io/llms-full.txt).
diff --git a/docs/md/use_cases/database_ui.md b/docs/md/use_cases/database_ui.md
new file mode 100644
index 0000000000..948ff496f6
--- /dev/null
+++ b/docs/md/use_cases/database_ui.md
@@ -0,0 +1,79 @@
+# A pivot and charting UI for DuckDB, ClickHouse and PostgreSQL
+
+
+
+If your data already lives in an analytical database, you do not need to load
+it into Perspective's engine to explore it. A
+[virtual server](../explanation/virtual_servers.md) implements Perspective's
+protocol on top of an external engine: when a user drags a column to _Group
+By_, adds a filter or scrolls the grid, the resulting `View` configuration is
+translated into a native query, executed by the database, and only the visible
+window of the result is returned.
+
+The user sees the same `` — data grid, pivot table, WebGL
+charts, maps, saved layouts — and the database does the work.
+
+| Engine | Where it runs | Guide |
+| --- | --- | --- |
+| DuckDB-WASM | In the browser, no server | [JavaScript](../how_to/javascript/virtual_server/duckdb.md) |
+| DuckDB | Python server | [Python](../how_to/python/virtual_server/duckdb.md) |
+| ClickHouse | Browser or Python server | [JavaScript](../how_to/javascript/virtual_server/clickhouse.md), [Python](../how_to/python/virtual_server/clickhouse.md) |
+| PostgreSQL | Python server | [Python](../how_to/python/virtual_server/postgres.md) |
+| Polars | Python server | [Python](../how_to/python/virtual_server/polars.md) |
+| Anything else | Your code | [Custom virtual servers](../how_to/javascript/virtual_server/custom.md) |
+
+## DuckDB in Python
+
+```python
+import duckdb
+import tornado.ioloop
+import tornado.web
+from perspective.handlers.tornado import PerspectiveTornadoHandler
+from perspective.virtual_servers.duckdb import DuckDBVirtualServer
+
+conn = duckdb.connect()
+conn.execute("CREATE TABLE trips AS SELECT * FROM 'trips/*.parquet'")
+
+app = tornado.web.Application([
+ (r"/websocket", PerspectiveTornadoHandler, {
+ "perspective_server": DuckDBVirtualServer(conn),
+ }),
+])
+
+app.listen(8080)
+tornado.ioloop.IOLoop.current().start()
+```
+
+```javascript
+const websocket = await perspective.websocket("ws://localhost:8080/websocket");
+const table = await websocket.open_table("trips");
+document.querySelector("perspective-viewer").load(table);
+```
+
+## DuckDB-WASM, entirely in the browser
+
+With DuckDB-WASM the whole stack — database, query translation and UI — runs
+in the browser tab. Because Perspective does not intercept your SQL, DuckDB's
+own Parquet, S3 and HTTP readers are available for loading data. See the
+[DuckDB-WASM guide](../how_to/javascript/virtual_server/duckdb.md).
+
+DuckDB-WASM can also attach a whole
+[DuckLake](https://ducklake.select/) lakehouse over HTTPS; see the
+[DuckLake case study](./ducklake.md).
+
+## When to use a virtual server, and when not to
+
+Use a virtual server when the data is larger than memory, already lives in
+the database, or must not leave it. Use Perspective's own engine when the data
+is _streaming_: its `Table` applies `update()` calls incrementally and pushes
+changes to every view, which a request/response SQL engine does not do.
+The two can be mixed — one `` workspace can hold panels
+backed by different engines.
+
+## Examples
+
+- [`python-duckdb-virtual`](https://github.com/perspective-dev/perspective/tree/master/examples/python-duckdb-virtual)
+- [`esbuild-duckdb-virtual`](https://github.com/perspective-dev/perspective/tree/master/examples/esbuild-duckdb-virtual)
+- [`python-clickhouse-virtual`](https://github.com/perspective-dev/perspective/tree/master/examples/python-clickhouse-virtual)
+- [`python-postgres-virtual`](https://github.com/perspective-dev/perspective/tree/master/examples/python-postgres-virtual)
+- [`python-polars-virtual`](https://github.com/perspective-dev/perspective/tree/master/examples/python-polars-virtual)
diff --git a/docs/md/use_cases/ducklake.md b/docs/md/use_cases/ducklake.md
new file mode 100644
index 0000000000..93750906c5
--- /dev/null
+++ b/docs/md/use_cases/ducklake.md
@@ -0,0 +1,291 @@
+# Case study: a multi-billion row tick history in a browser tab with DuckLake and DuckDB-WASM
+
+
+
+[DuckLake](https://ducklake.select/) is an open lakehouse format which keeps
+table data in Parquet files and _all_ metadata — schemas, snapshots, file
+lists, statistics — in an ordinary SQL database. With a DuckDB file as that
+database, an entire lakehouse catalog is one static file.
+
+This case study puts a self-service analytics UI on a market data lake — a
+tick-by-tick trade and price history, partitioned by symbol and trade date —
+with **no backend at all**. The figures below are rounded from measurements
+against a real _frozen_ (read-only) DuckLake of comparable size and layout:
+
+| | |
+| --- | --- |
+| Rows | ~3 billion |
+| Parquet files | Hundreds of thousands, partitioned by symbol and trade date |
+| Data size | Tens of gigabytes, in object storage |
+| Catalog | One `.ducklake` file of tens of megabytes, on a static host |
+| Servers operated | None |
+
+The browser runs three things:
+
+1. [DuckDB-WASM](https://duckdb.org/docs/current/clients/wasm/overview), with
+ the `ducklake` extension, as the query engine.
+2. Perspective's [DuckDB virtual server](../how_to/javascript/virtual_server/duckdb.md),
+ which translates `` configurations into DuckDB SQL.
+3. ``, as the data grid, pivot table and charts.
+
+```text
+ static hosting / object storage browser tab
+┌─────────────────────────────────┐ ┌──────────────────────────────────┐
+│ ticks.ducklake (catalog) │◄──────┤ DuckDB-WASM + ducklake extension │
+│ trades/symbol=…/date=…/*.parquet│ HTTPS │ ▲ SQL │
+└─────────────────────────────────┘ range │ Perspective DuckDB virtual server│
+ │ ▲ view config │
+ │ │
+ └──────────────────────────────────┘
+```
+
+## 1. Attach the lake
+
+```javascript
+import perspective from "@perspective-dev/client";
+import "@perspective-dev/viewer";
+import "@perspective-dev/viewer-datagrid";
+import "@perspective-dev/viewer-charts";
+import * as duckdb from "@duckdb/duckdb-wasm";
+import { DuckDBHandler } from "@perspective-dev/client/dist/esm/virtual_servers/duckdb.js";
+
+const bundle = await duckdb.selectBundle(duckdb.getJsDelivrBundles());
+const worker_url = URL.createObjectURL(
+ new Blob([`importScripts("${bundle.mainWorker}");`], {
+ type: "text/javascript",
+ }),
+);
+
+const db = new duckdb.AsyncDuckDB(new duckdb.VoidLogger(), new Worker(worker_url));
+await db.instantiate(bundle.mainModule, bundle.pthreadWorker);
+URL.revokeObjectURL(worker_url);
+
+const conn = await db.connect();
+await conn.query(`SET default_null_order=NULLS_FIRST_ON_ASC_LAST_ON_DESC;`);
+await conn.query(`
+ ATTACH 'ducklake:https://data.example.com/ticks.ducklake' AS lake;
+`);
+```
+
+That is the whole connection. The `ducklake` extension is fetched and loaded
+automatically by the `ATTACH`, and the attach takes one to three seconds:
+DuckDB reads the catalog by HTTP range request rather than downloading the
+whole file. A lake which records absolute `s3://` or `https://` paths for its data
+files needs nothing else; one written with relative paths also needs
+`DATA_PATH 'https://…/data/'` to say where they now live.
+
+## 2. Pull a slice, then explore it
+
+Every query against the lake is a set of HTTP range requests, so its cost is
+set by how much of the table the `WHERE` clause lets DuckDB _skip_. The catalog
+holds each file's partition values and column statistics, so pruning
+hundreds of thousands of files to the relevant handful happens before any Parquet is touched:
+
+| Query against the lake, in the browser | Rows | Time |
+| --- | --- | --- |
+| `ATTACH` the lake | — | ~1 s |
+| Aggregate one symbol, one day | ~10 thousand | ~1 s |
+| `CREATE TABLE … AS SELECT` one symbol, one month | ~300 thousand | ~5 s |
+| Count one symbol, two years | ~6 million | ~1.5 min |
+| `GROUP BY` over the materialized month | ~300 thousand | ~10 ms |
+
+_Headless Chrome, DuckDB-WASM 1.4.3, one machine on one network, measured
+once and rounded; treat these as orders of magnitude._
+
+The last two rows are the design lesson. Interactive pivoting wants
+millisecond queries, and a remote scan of millions of rows in hundreds of
+small files is not that. So do what an analyst would do: materialize the
+slice of interest into the local DuckDB once, and point Perspective at _that_.
+
+```javascript
+await conn.query(`
+ CREATE TABLE trades_slice AS (
+ SELECT * FROM lake.trades
+ WHERE symbol IN ('AAPL', 'MSFT')
+ AND trade_date BETWEEN DATE '2024-01-01' AND DATE '2024-03-31'
+ );
+`);
+
+const handler = new DuckDBHandler(conn);
+const client = await perspective.worker(
+ await perspective.createMessageHandler(handler),
+);
+
+const viewer = document.querySelector("perspective-viewer");
+await viewer.load(client);
+await viewer.restore({
+ table: "memory.trades_slice",
+ plugin: "Candlestick",
+ group_by: ["bucket(\"ts\", 'm')"],
+ split_by: ["symbol"],
+ columns: ["open", "close", "high", "low"],
+ expressions: {
+ "bucket(\"ts\", 'm')": "bucket(\"ts\", 'm')",
+ open: '"price"',
+ close: '"price"',
+ high: '"price"',
+ low: '"price"',
+ },
+ aggregates: { open: "first", close: "last", high: "high", low: "low" },
+});
+```
+
+Perspective's DuckDB virtual server discovers tables with `SHOW ALL TABLES`
+and names them `.
`, so the slice appears as
+`memory.trades_slice` with no registration step. From here the user has the
+complete Perspective UI — group, split, filter, sort, expression columns,
+every chart type — and each interaction is one local SQL query.
+
+The slice selector — which symbols, which dates — is ordinary application UI
+around that one `CREATE TABLE` statement. Several slices can be open as
+panels of one `` workspace at once.
+
+### How big can a slice be?
+
+Bigger than "slice" suggests. DuckDB is a columnar, vectorized engine, and
+that is still true under WebAssembly. Synthetic tick data — timestamp, symbol,
+price, size, side, venue — in DuckDB-WASM, single-threaded, in one browser
+tab:
+
+| Local table | Storage | Build | Pivot by symbol × side | 1-minute OHLC for one symbol |
+| --- | --- | --- | --- | --- |
+| 10 million rows | In memory, 599 MB | 1.7 s | 0.34 s | 0.11 s |
+| 50 million rows | OPFS, 408 MiB on disk | 23 s | 0.78 s | 0.25 s |
+| 100 million rows | OPFS, ~0.7 GiB on disk | 46 s | 1.5 s | 0.44 s |
+
+_Build time is generating the rows, not fetching them. Synthetic data
+compresses better than real ticks; expect real files to be larger._
+
+Two regimes are visible:
+
+- **In memory, plan on tens of millions of rows.** An in-memory DuckDB stores
+ tables uncompressed — about 60 bytes per tick here — inside 32-bit
+ WebAssembly's 4 GB address space, of which DuckDB budgets 3.1 GiB. Ten
+ million rows is comfortable; fifty million of this shape did not fit.
+- **On OPFS, plan on a hundred million and up.** Open the database at an
+ `opfs://` path and tables live in a compressed, persistent file in the
+ browser's
+ [Origin Private File System](https://duckdb.org/2026/09/18/opfs-wasm), with
+ DuckDB paging blocks in and out as needed. The same 50 million rows which
+ failed in memory took 408 MiB on disk, and 100 million still pivoted in a
+ second and a half. The slice also survives a reload, so a returning user
+ does not pay for the fetch twice.
+
+```javascript
+await db.open({
+ path: "opfs://ticks.duckdb",
+ accessMode: duckdb.DuckDBAccessMode.READ_WRITE,
+});
+```
+
+OPFS support in DuckDB-WASM is recent; check the
+[release notes](https://duckdb.org/2026/09/18/opfs-wasm) for the version to
+pin, and `CHECKPOINT` after building a slice you want to keep.
+
+So the practical limit on a slice is not the engine. It is how long the user
+will wait for the fetch, which is a property of how well the lake is
+partitioned for the question.
+
+## Guard against full scans
+
+DuckDB has no "maximum bytes scanned" setting, and a lakehouse table is only
+cheap to query when a filter lets most of it be skipped. In a SQL console an
+unfiltered query is something a user has to type. In a pivot UI it is one
+drag: `SHOW ALL TABLES` lists `lake.trades` next to the slice, and opening it
+and dropping a column on _Group By_ asks the browser to aggregate billions of
+rows — tens of gigabytes of downloads, paid for by the reader's connection and
+memory and by whoever hosts the bucket.
+
+Design so that cannot happen:
+
+- **Expose slices, never the lake.** Attach the lake on a DuckDB instance the
+ viewer is not bound to, or do not offer its tables in your table picker;
+ hand Perspective only the materialized tables.
+- **Make the filter mandatory.** Build the `CREATE TABLE … AS SELECT` from
+ validated inputs (a symbol list, a bounded date range), estimate its size
+ from the catalog first — `ducklake_data_file` has `record_count` and
+ `file_size_bytes` per file — and refuse slices over a budget.
+- **Bound the damage.** Set DuckDB's `memory_limit` so a runaway query fails
+ instead of taking the tab down.
+- **Mind whose bucket it is.** If the Parquet is someone else's public data,
+ your application's traffic is their request bill. Do not publish a link
+ which lets copy-pasted code scan it.
+
+## 3. Time travel as a user feature
+
+Every DuckLake snapshot is queryable, and the catalog says what they are:
+
+```javascript
+const snapshots = await conn.query(
+ `SELECT snapshot_id, snapshot_time, changes FROM lake.snapshots()`,
+);
+```
+
+Because the virtual server sees DuckDB views as tables, exposing a point in
+time to the UI is one statement:
+
+```javascript
+await conn.query(`
+ CREATE OR REPLACE VIEW trades_as_of AS
+ SELECT * FROM lake.trades AT (VERSION => ${snapshot_id})
+ WHERE symbol = 'AAPL' AND trade_date = DATE '2024-03-15';
+`);
+
+await viewer.restore({ table: "memory.trades_as_of" });
+```
+
+For market data this is the correction workflow: put the current slice and an
+`AT (VERSION => …)` slice in two panels with the same configuration, and the
+user sees a day before and after a vendor's restatement, pivoted however they
+like. Alternatively, attach the lake a second time with `SNAPSHOT_VERSION` or
+`SNAPSHOT_TIME` to pin a whole catalog.
+
+## Publishing your own
+
+A frozen DuckLake is written by native DuckDB — a nightly job, a notebook,
+CI — using a DuckDB file as the catalog:
+
+```sql
+INSTALL ducklake;
+ATTACH 'ducklake:ticks.ducklake' AS lake (DATA_PATH 's3://my-bucket/ticks/');
+
+CREATE TABLE lake.trades AS
+ SELECT * FROM read_parquet('raw/trades_*.parquet');
+```
+
+Existing Parquet can also be registered in place, without rewriting it.
+Upload the catalog file to any static host.
+
+- **CORS and `Range`.** Both the catalog's host and the data's must allow
+ your origin and honor `Range` requests. This is the most common reason an
+ attach fails.
+- **Partition for the questions users ask.** Pruning is what makes this
+ interactive; a symbol/date layout is why a one-day query takes a second.
+- **Fewer, larger files.** The two-year query above spans hundreds of small
+ daily files, each costing its own round trips. Compact before publishing.
+- **Match versions.** A lake written by a newer DuckLake than the browser's
+ extension understands will not attach. Pin `@duckdb/duckdb-wasm` and the
+ writer's DuckDB to compatible releases.
+- **The browser is a reader.** Under WebAssembly, `ATTACH`, queries,
+ `snapshots()`, time travel and even catalog DDL work; data writes to the
+ lake did not in our testing, and PostgreSQL or MySQL catalogs are out of
+ reach because browsers have no raw sockets. Write from native DuckDB.
+- **Hide the plumbing.** `SHOW ALL TABLES` also lists DuckLake's own metadata
+ tables (`__ducklake_metadata_.*`), so they appear in the viewer's
+ table list alongside your data.
+- **Private lakes.** DuckDB's `CREATE SECRET (TYPE s3, …)` works in the
+ browser, but a key in a page is a key in the browser; front a private
+ bucket with short-lived signed URLs or a proxy.
+- **Today's ticks do not belong here.** A lakehouse is request/response. For
+ the live session use Perspective's own engine, whose `Table` pushes
+ incremental updates to every view — see
+ [Trading blotters, order books and market data](./market_data.md). History
+ from the lake and live panels can share one workspace.
+
+## Related
+
+- [A UI for DuckDB, ClickHouse and PostgreSQL](./database_ui.md)
+- [Trading blotters, order books and market data](./market_data.md)
+- [DuckDB virtual server (JavaScript)](../how_to/javascript/virtual_server/duckdb.md)
+- [Visualizing millions of rows in the browser](./large_datasets.md)
+- [`esbuild-duckdb-virtual` example](https://github.com/perspective-dev/perspective/tree/master/examples/esbuild-duckdb-virtual)
diff --git a/docs/md/use_cases/embedded_analytics.md b/docs/md/use_cases/embedded_analytics.md
new file mode 100644
index 0000000000..92118bff4a
--- /dev/null
+++ b/docs/md/use_cases/embedded_analytics.md
@@ -0,0 +1,81 @@
+# Embedded analytics in a web application
+
+
+
+Embedded analytics means giving your application's users a way to explore
+_their_ data inside _your_ product — not a static chart you designed, and not a
+link out to a separate BI tool. `` is a component built for
+that job.
+
+- **A Web Component, not a platform.** It is one Custom Element with no
+ framework dependency. It works in plain HTML and in React (via
+ [`@perspective-dev/react`](../how_to/javascript/react.md)), Vue, Svelte and
+ Angular through standard DOM APIs. There is no server to deploy unless you
+ want one, and no iframe.
+- **Self-service by default.** Users group, pivot, filter, sort, write
+ computed columns and switch between data grid, charts and maps themselves.
+- **State is JSON.** [`save()` and `restore()`](../how_to/javascript/save_restore.md)
+ round-trip the entire configuration, so "saved views", shareable links and
+ per-user defaults are a database column, not a feature to build.
+- **Multi-panel dashboards.** One element can hold a tabbed, split layout of
+ many panels with cross-panel global filters, saved and restored with
+ `saveWorkspace()` and `restoreWorkspace()`.
+- **Your brand.** [Themes](../how_to/javascript/theming.md) are CSS custom
+ properties; several light and dark themes are included.
+- **Your data path.** Load data in the browser, replicate it from your server,
+ virtualize it server-side, or [point it at your database](./database_ui.md).
+- **Apache-2.0.** No per-seat or per-deployment licensing, and no feature
+ tier: pivoting, charts and server-side virtualization are all open source.
+
+## React
+
+```tsx
+import * as React from "react";
+import perspective from "@perspective-dev/client";
+import { PerspectiveViewer } from "@perspective-dev/react";
+
+const worker = await perspective.worker();
+const table = worker.table(
+ fetch("/api/orders.arrow").then((resp) => resp.arrayBuffer()),
+);
+
+export function OrdersReport({ saved, onChange }) {
+ return (
+
+ );
+}
+```
+
+WebAssembly initialization for your bundler is covered in
+[Importing with or without a bundler](../how_to/javascript/importing.md); with
+Next.js, load the component client-side only (`ssr: false`).
+
+## Plain JavaScript
+
+```javascript
+const viewer = document.querySelector("perspective-viewer");
+await viewer.load(table);
+await viewer.restore(await loadSavedViewFor(user));
+
+viewer.addEventListener("perspective-config-update", async () => {
+ await persistSavedViewFor(user, await viewer.save());
+});
+```
+
+## Constraining what users can do
+
+`restore()` sets the starting point; users can change anything from there. To
+lock an embedded report down, hide the configuration UI with the `settings`
+config field and drive the element only from your own controls. Row-level
+security belongs on the server: host a filtered `View`, or a
+[virtual server](../explanation/virtual_servers.md) bound to a restricted
+database role, rather than relying on a client-side filter.
+
+## An assistant in the box
+
+`` includes an opt-in [LLM agent](./agent.md) which lets
+users ask for a view in plain language.
diff --git a/docs/md/use_cases/jupyter.md b/docs/md/use_cases/jupyter.md
new file mode 100644
index 0000000000..ea692e1e96
--- /dev/null
+++ b/docs/md/use_cases/jupyter.md
@@ -0,0 +1,88 @@
+# Interactive pivot tables and charts in Jupyter
+
+
+
+`PerspectiveWidget` puts the full `` UI in a notebook
+cell. Pass it a DataFrame and you get a sortable, filterable data grid; drag a
+column to _Group By_ and it becomes a pivot table; pick a chart type and it
+becomes a bar, line, scatter, heatmap, treemap or map — all without writing
+plotting code or re-running the cell.
+
+```bash
+pip install "perspective-python[jupyter]"
+```
+
+```python
+import pandas as pd
+from perspective.widget import PerspectiveWidget
+
+df = pd.read_parquet("trips.parquet")
+PerspectiveWidget(df)
+```
+
+It is built on [anywidget](https://anywidget.dev/), so the same wheel works in
+JupyterLab, classic Jupyter Notebook, VS Code notebooks, Google Colab and
+marimo, with no separate lab extension to install or version-match.
+
+## Why use it instead of `df.head()` or a plotting library
+
+- **The whole DataFrame, not a preview.** The grid virtual-scrolls, so a
+ multi-million row frame is browsable, sortable and filterable in place.
+- **Exploration without code.** Grouping, pivoting, aggregating, filtering and
+ charting are drag-and-drop. Computed columns use a built-in
+ [expression language](../explanation/view/config/expressions.md).
+- **Reproducible.** Every choice made in the UI is a keyword argument, so an
+ exploration can be frozen back into the cell:
+
+```python
+PerspectiveWidget(
+ df,
+ plugin="Heatmap",
+ group_by=["pickup_hour"],
+ split_by=["weekday"],
+ columns=["fare"],
+ aggregates={"fare": "avg"},
+)
+```
+
+- **Live.** Pass a `perspective.Table` instead of a DataFrame and call
+ `table.update()` from another cell or thread; the widget ticks in real time.
+
+## pandas, polars and pyarrow
+
+`pandas.DataFrame`, `polars.DataFrame`, `pyarrow.Table`, Arrow IPC bytes, CSV
+strings, and lists or dicts of Python values are all accepted directly; see
+[DataFrame and Arrow compatibility](../how_to/python/table_data.md).
+
+## Where the data lives
+
+By default (`binding_mode="server"`) the data stays in the Python kernel and
+the browser is streamed only the window of rows it is displaying, so very
+large frames open quickly. For the most fluid interaction on small and medium
+data, `binding_mode="client-server"` additionally replicates the table into
+the browser's WebAssembly engine:
+
+```python
+PerspectiveWidget(df, binding_mode="client-server")
+```
+
+For frames which strain the kernel's memory, build the table with
+[`page_to_disk`](../explanation/table/options.md#page_to_disk) so its columns
+are memory-mapped from disk, and pass the table to the widget:
+
+```python
+import perspective
+
+table = perspective.table(df, page_to_disk=True)
+PerspectiveWidget(table)
+```
+
+See [`PerspectiveWidget` for notebooks](../how_to/python/jupyterlab.md) for the
+full widget API.
+
+## From notebook to application
+
+The engine and UI in the notebook are the same ones used in production web
+applications. A configuration explored in Jupyter can be saved as JSON and
+restored in a `` served from
+[Tornado, FastAPI or aiohttp](../how_to/python/websocket.md).
diff --git a/docs/md/use_cases/large_datasets.md b/docs/md/use_cases/large_datasets.md
new file mode 100644
index 0000000000..a003989374
--- /dev/null
+++ b/docs/md/use_cases/large_datasets.md
@@ -0,0 +1,107 @@
+# Visualizing millions of rows in the browser
+
+
+
+Most JavaScript data grids and charting libraries hold rows as JavaScript
+objects and lay out one DOM or SVG node per datum, which stalls somewhere
+between ten thousand and a few hundred thousand rows. Perspective takes a
+different approach at each layer:
+
+- **Columnar engine in WebAssembly.** Data is stored in typed, columnar
+ buffers inside a C++ query engine compiled to WebAssembly and run in a Web
+ Worker, off the main thread. Strings are dictionary-encoded. Nothing is
+ materialized as JavaScript objects unless you ask for it.
+- **Apache Arrow in, Apache Arrow out.** A [`Table`](../explanation/table.md)
+ loads [Arrow](../explanation/table/loading_data.md) directly into those
+ buffers without per-row parsing, and `View.to_arrow()` exports the same way.
+ CSV and JSON are also supported.
+- **Queries, not rows, cross the boundary.** Grouping, pivoting, filtering and
+ sorting happen inside the engine. The UI requests only the window of the
+ result it is about to draw.
+- **Virtual-scrolling data grid.** The
+ [Datagrid](https://www.npmjs.com/package/@perspective-dev/viewer-datagrid)
+ renders only visible cells, so scrolling a 10 million row grid costs the same
+ as scrolling a 100 row grid.
+- **WebGL charts.** Scatter, heatmap, line and map plugins draw on the GPU,
+ staying interactive at point counts where SVG and 2D canvas charts do not.
+
+## Loading a large file
+
+```javascript
+const worker = await perspective.worker();
+const response = await fetch("/data/trips.arrow");
+const table = await worker.table(await response.arrayBuffer());
+await document.querySelector("perspective-viewer").load(table);
+```
+
+Prefer Arrow (optionally LZ4 or ZSTD compressed) over CSV or JSON for large
+datasets: it is smaller on the wire, carries its own schema, and skips type
+inference.
+
+## More than 4GB: Memory64
+
+32-bit WebAssembly caps the engine's heap at 4GB.
+`@perspective-dev/server` also ships a
+[Memory64 build](../how_to/javascript/importing.md) which raises the ceiling
+to 16GB in browsers which support it. Register both binaries and only the one
+the browser selects is downloaded:
+
+```javascript
+perspective.init_server({
+ wasm32: () => fetch(SERVER_WASM),
+ wasm64: () => fetch(SERVER_WASM64),
+});
+```
+
+## More than memory: `page_to_disk`
+
+A `Table` normally lives in the engine's memory. Created with
+[`page_to_disk`](../explanation/table/options.md#page_to_disk), its columns
+are backed by on-disk storage instead — the browser's Origin Private File
+System under WebAssembly, memory-mapped files in Python and Rust — and the
+engine evicts the coldest columns to it when it is over its
+resident memory budget (1 GiB by default in the browser), reading them back
+when a query needs them.
+
+```javascript
+const table = await worker.table(await response.arrayBuffer(), {
+ page_to_disk: true,
+});
+```
+
+Everything else about the `Table` is unchanged, including streaming updates
+and the viewer on top of it. Use it for wide tables where users touch a few
+columns at a time, or to hold several large tables in one tab; leave it off
+for data which fits, since a query over evicted columns pays to read them
+back.
+
+## How many rows?
+
+It depends on column count and types more than row count — numeric and
+datetime columns are compact, high-cardinality strings are not. Millions of
+rows is routine; tens of millions is practical for narrow numeric tables. Free
+memory by calling [`delete()`](../how_to/javascript/deleting.md) on views and
+tables you no longer need, and consider `page_to_disk` for tables which are
+large but only partly in use at any moment.
+
+## When the data does not fit in the browser
+
+Keep it on a server and send the browser only what is visible:
+
+- **[Server-only mode](../explanation/architecture/server_only.md)** — the
+ same engine, running natively in Python, Node.js or Rust, with the browser
+ connected over WebSocket.
+- **[Virtual servers](../explanation/virtual_servers.md)** — no Perspective
+ engine at all. View configurations are translated to SQL and run by DuckDB,
+ ClickHouse, PostgreSQL or Polars, which can be as large as those systems
+ allow.
+
+In both modes the viewer, its configuration and its saved layouts are
+identical to the in-browser case.
+
+## Examples
+
+- [Olympics](https://perspective-dev.github.io/gallery/olympics.html) — 120
+ years of athlete records loaded from Arrow and pivoted in-browser.
+- [NYPD CCRB](https://perspective-dev.github.io/gallery/nypd.html) —
+ complaint records cross-filtered across grid and heatmaps.
diff --git a/docs/md/use_cases/market_data.md b/docs/md/use_cases/market_data.md
new file mode 100644
index 0000000000..32a6c306e6
--- /dev/null
+++ b/docs/md/use_cases/market_data.md
@@ -0,0 +1,85 @@
+# Trading blotters, order books and market data
+
+
+
+Perspective was originally developed to handle Financial market data: wide
+tables, high update rates, keyed replacement of rows, and users who need to
+re-slice the data themselves while it is moving.
+
+## The building blocks
+
+**A blotter** is an indexed table in a data grid. With
+[`index`](../explanation/table/options.md) set to the order or trade id, each
+`update()` replaces that row in place; partial updates (only the changed
+fields) are supported, and `remove()` deletes by key.
+
+```javascript
+const table = await worker.table(
+ { id: "string", symbol: "string", side: "string", price: "float", qty: "integer", status: "string", time: "datetime" },
+ { index: "id" },
+);
+
+table.update([{ id: "o-1841", status: "filled" }]);
+```
+
+**An order book** is a pivot of that same table: `group_by` price,
+`split_by` side, `sum` of quantity, filtered to open orders.
+
+```javascript
+await viewer.restore({
+ plugin: "X Bar",
+ group_by: ["price"],
+ split_by: ["side"],
+ columns: ["qty"],
+ filter: [["status", "==", "open"]],
+});
+```
+
+**Candlesticks** are a pivot too: `group_by` a time bucket expression, with
+`first`, `last`, `high` and `low` aggregates over aliases of the price column,
+drawn by the Candlestick or OHLC plugin.
+
+```javascript
+await viewer.restore({
+ plugin: "Candlestick",
+ group_by: ["bucket(\"time\", 'm')"],
+ columns: ["open", "close", "high", "low"],
+ expressions: {
+ "bucket(\"time\", 'm')": "bucket(\"time\", 'm')",
+ open: '"price"',
+ close: '"price"',
+ high: '"price"',
+ low: '"price"',
+ },
+ aggregates: { open: "first", close: "last", high: "high", low: "low" },
+});
+```
+
+Because every one of these is a `View` over one streaming `Table`, they stay
+mutually consistent tick by tick, and users can change any of them — regroup
+by sector, filter to a book, switch the blotter to a heatmap — without code.
+
+## Conditional formatting
+
+The data grid supports per-column number formatting, positive/negative
+foreground and background colors, gradients and in-cell bars, all set from the
+column settings panel and captured in the saved configuration.
+
+## Deployment shapes
+
+- **Desktop containers and internal web apps** — `` is a
+ standard Web Component with no framework dependency, and ships
+ [React bindings](../how_to/javascript/react.md).
+- **Python services** — host tables from
+ [Tornado, FastAPI/Starlette or aiohttp](../how_to/python/websocket.md);
+ ingest `pandas`, `polars` or `pyarrow` directly.
+- **ClickHouse, DuckDB, PostgreSQL, Polars** — put the UI directly over the
+ tick store with a [virtual server](../explanation/virtual_servers.md).
+- **Research notebooks** — the same widget in
+ [Jupyter](../how_to/python/jupyterlab.md).
+
+## Examples
+
+- [Market](https://perspective-dev.github.io/gallery/market-trading-desk.html)
+ — blotter, order book chart and candlesticks over one simulated feed.
+- [Market — Orders](https://perspective-dev.github.io/gallery/market-order-flow.html)
diff --git a/docs/md/use_cases/real_time_dashboard.md b/docs/md/use_cases/real_time_dashboard.md
new file mode 100644
index 0000000000..a2629430da
--- /dev/null
+++ b/docs/md/use_cases/real_time_dashboard.md
@@ -0,0 +1,122 @@
+# Real-time dashboards over WebSocket
+
+
+
+A real-time dashboard is a set of tables and charts which stay current as the
+data behind them changes, without the user reloading. Perspective is built for
+this: a [`Table`](../explanation/table.md) accepts streaming
+[`update()`](../explanation/table/update_and_remove.md) calls, every
+[`View`](../explanation/view.md) over it — grouped, pivoted, filtered or
+sorted — is maintained incrementally, and `` repaints only
+what changed.
+
+There is no polling and no query re-execution. An update of 50 rows to a 10
+million row table costs work proportional to the 50 rows.
+
+## Architecture
+
+1. A server process owns the `Table` and writes to it as new data arrives —
+ from a message queue, a market data feed, a database change stream, or a
+ timer.
+2. The server exposes that `Table` by name on a WebSocket endpoint.
+3. Each browser opens the `Table` by name and loads it into a
+ ``. The user configures their own grouping, filters and
+ chart type; each browser gets its own `View`.
+
+Perspective offers two ways to split this work between server and browser,
+covered in [Data Architecture](../explanation/architecture.md):
+
+- **[Client/server replicated](../explanation/architecture/client_server.md)**
+ — the browser keeps a synchronized copy of the table in WebAssembly. Queries
+ run locally, so interaction is instant and the server only ships deltas. Best
+ when the dataset fits in browser memory.
+- **[Server only](../explanation/architecture/server_only.md)** — queries run
+ on the server and the browser receives only the visible window of rows. Best
+ for very large tables or thin clients.
+
+## A Python server
+
+```python
+import threading
+import time
+
+import tornado.ioloop
+import tornado.web
+from perspective import Server
+from perspective.handlers.tornado import PerspectiveTornadoHandler
+
+server = Server()
+client = server.new_local_client()
+table = client.table(
+ {"symbol": "string", "price": "float", "time": "datetime"},
+ name="prices",
+)
+
+def feed():
+ while True:
+ table.update(next_batch())
+ time.sleep(0.05)
+
+threading.Thread(target=feed, daemon=True).start()
+
+app = tornado.web.Application([
+ (r"/websocket", PerspectiveTornadoHandler, {"perspective_server": server}),
+])
+
+app.listen(8080)
+tornado.ioloop.IOLoop.current().start()
+```
+
+Perspective's Python API is thread-safe and releases the GIL, so the feed can
+run on its own thread; see [Multithreading](../how_to/python/multithreading.md).
+Handlers are also provided for
+[Starlette/FastAPI and aiohttp](../how_to/python/websocket.md).
+
+## The browser
+
+```html
+
+
+
+```
+
+This is server-only mode. For replicated mode, create a `View` on the server
+table and build a local table from it — `worker.table(server_view)` — as shown
+in [Hosting a WebSocket server](../how_to/python/websocket.md).
+
+## Keeping a rolling window
+
+For feeds which never end, bound the table. An
+[`index`](../explanation/table/options.md) makes updates replace rows by key
+(latest price per symbol); a `limit` keeps only the most recent _n_ rows
+(a rolling tick history).
+
+## A Node.js server
+
+The same server can be written in Node.js with
+[`WebSocketServer`](../how_to/javascript/nodejs_server.md), or in Rust — see the
+[`rust-axum` example](https://github.com/perspective-dev/perspective/tree/master/examples/rust-axum).
+
+## See it running
+
+- [Market](https://perspective-dev.github.io/gallery/market-trading-desk.html)
+ — a simulated order book streaming into a blotter, depth chart and
+ candlestick chart.
+- [`python-tornado-streaming`](https://github.com/perspective-dev/perspective/tree/master/examples/python-tornado-streaming)
+ — the complete version of the server above.
diff --git a/docs/md/use_cases/streaming_pivot_table.md b/docs/md/use_cases/streaming_pivot_table.md
new file mode 100644
index 0000000000..05d66edf77
--- /dev/null
+++ b/docs/md/use_cases/streaming_pivot_table.md
@@ -0,0 +1,82 @@
+# Streaming pivot tables
+
+
+
+A pivot table groups rows by one set of columns, splits them across another,
+and aggregates the cells. A _streaming_ pivot table keeps that result correct
+as the underlying rows are inserted, updated and removed — without recomputing
+the whole pivot.
+
+In Perspective a pivot is a [`View`](../explanation/view.md) with `group_by`
+and `split_by`:
+
+```javascript
+const view = await table.view({
+ group_by: ["Region", "State"],
+ split_by: ["Category"],
+ columns: ["Sales", "Profit"],
+ aggregates: { Sales: "sum", Profit: "avg" },
+ sort: [["Sales", "desc"]],
+});
+```
+
+When [`table.update()`](../explanation/table/update_and_remove.md) is called,
+the engine applies the delta to only the affected groups and notifies
+subscribers:
+
+```javascript
+view.on_update(async (updated) => {
+ const rows = await view.to_json();
+}, { mode: "row" });
+```
+
+Loaded into ``, the same configuration is an interactive
+pivot grid: users drag columns between _Group By_, _Split By_, _Order By_ and
+_Where_, expand and collapse row groups, and switch to a chart of the same
+pivot.
+
+```javascript
+await viewer.load(table);
+await viewer.restore({
+ plugin: "Datagrid",
+ group_by: ["Region", "State"],
+ split_by: ["Category"],
+ columns: ["Sales", "Profit"],
+});
+```
+
+## What can be pivoted
+
+- **Row pivots** — any number of [`group_by`](../explanation/view/config/grouping_and_pivots.md)
+ levels, rendered as an expandable tree with subtotals at each level.
+- **Column pivots** — any number of `split_by` levels, rendered as grouped
+ column headers.
+- **Aggregates** — sum, count, distinct count, average, weighted mean, median,
+ min/max, first/last, standard deviation, variance and more, chosen per
+ column.
+- **Computed columns** — [`expressions`](../explanation/view/config/expressions.md)
+ can be grouped, split, aggregated and filtered like any other column, so
+ bucketing a datetime by month or binning a number is one expression.
+- **Window columns** — [running totals, ranks, lags and rates](../explanation/view/config/windows.md).
+- **Joins** — pivot over a [reactive join](../explanation/join.md) of two
+ streaming tables.
+
+## Where the pivot runs
+
+The same pivot API runs in the browser (WebAssembly), in Node.js, in Python
+and in Rust. It can also be delegated to a database: with a
+[virtual server](../explanation/virtual_servers.md), a `group_by`/`split_by`
+configuration is translated to SQL and executed by DuckDB, ClickHouse or
+PostgreSQL.
+
+## Licensing
+
+Row and column pivoting, aggregation, charting of pivots and server-side
+virtualization are all part of Perspective's Apache-2.0 open source
+distribution. There is no commercial tier.
+
+## Examples
+
+- [Pivot by 2 row levels and 2 column levels](https://perspective-dev.github.io/gallery/feature-05-both-2.html)
+- [Superstore workspace](https://perspective-dev.github.io/gallery/superstore-overview.html)
+- [All examples](https://perspective-dev.github.io/gallery/index.html)
diff --git a/docs/src/components/about_dialog.ts b/docs/src/components/about_dialog.ts
new file mode 100644
index 0000000000..824bebebc1
--- /dev/null
+++ b/docs/src/components/about_dialog.ts
@@ -0,0 +1,47 @@
+// ┏━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
+// ┃ ██████ ██████ ██████ █ █ █ █ █ █▄ ▀███ █ ┃
+// ┃ ▄▄▄▄▄█ █▄▄▄▄▄ ▄▄▄▄▄█ ▀▀▀▀▀█▀▀▀▀▀ █ ▀▀▀▀▀█ ████████▌▐███ ███▄ ▀█ █ ▀▀▀▀▀ ┃
+// ┃ █▀▀▀▀▀ █▀▀▀▀▀ █▀██▀▀ ▄▄▄▄▄ █ ▄▄▄▄▄█ ▄▄▄▄▄█ ████████▌▐███ █████▄ █ ▄▄▄▄▄ ┃
+// ┃ █ ██████ █ ▀█▄ █ ██████ █ ███▌▐███ ███████▄ █ ┃
+// ┣━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┫
+// ┃ Copyright (c) 2017, the Perspective Authors. ┃
+// ┃ ╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌╌ ┃
+// ┃ This file is part of the Perspective library, distributed under the terms ┃
+// ┃ of the [Apache License 2.0](https://www.apache.org/licenses/LICENSE-2.0). ┃
+// ┗━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┛
+
+const HASH = "#about";
+
+/**
+ * Open the statically-rendered About dialog from the `#about` route, and
+ * clear that route when it closes.
+ */
+export function initAboutDialog(): void {
+ const dialog = document.getElementById("about") as HTMLDialogElement | null;
+ if (!dialog) {
+ return;
+ }
+
+ const sync = () => {
+ if (location.hash === HASH && !dialog.open) {
+ dialog.showModal();
+ dialog.scrollTop = 0;
+ }
+ };
+
+ dialog.addEventListener("click", (event) => {
+ const target = event.target as HTMLElement;
+ if (target === dialog || target.closest("[data-role=close]")) {
+ dialog.close();
+ }
+ });
+
+ dialog.addEventListener("close", () => {
+ if (location.hash === HASH) {
+ history.replaceState(null, "", location.pathname + location.search);
+ }
+ });
+
+ window.addEventListener("hashchange", sync);
+ sync();
+}
diff --git a/docs/src/components/project_gallery.ts b/docs/src/components/project_gallery.ts
index d3b2422732..fad8613f7c 100644
--- a/docs/src/components/project_gallery.ts
+++ b/docs/src/components/project_gallery.ts
@@ -12,7 +12,12 @@
import { createSource } from "../data/create_source.js";
import { PROJECTS, projectById } from "../data/projects/corpus.js";
-import { type Project, thumbnailUrl } from "../data/projects/types.js";
+import {
+ HOME_TITLE,
+ type Project,
+ pageTitle,
+ thumbnailUrl,
+} from "../data/projects/types.js";
import {
addSource,
listSources,
@@ -23,7 +28,6 @@ import { currentTheme, subscribeTheme } from "../data/theme.js";
import { errorText, escape, html, query } from "./dom.js";
const PROJECT_PARAM = "project";
-const BASE_TITLE = document.title;
const TEMPLATE = `
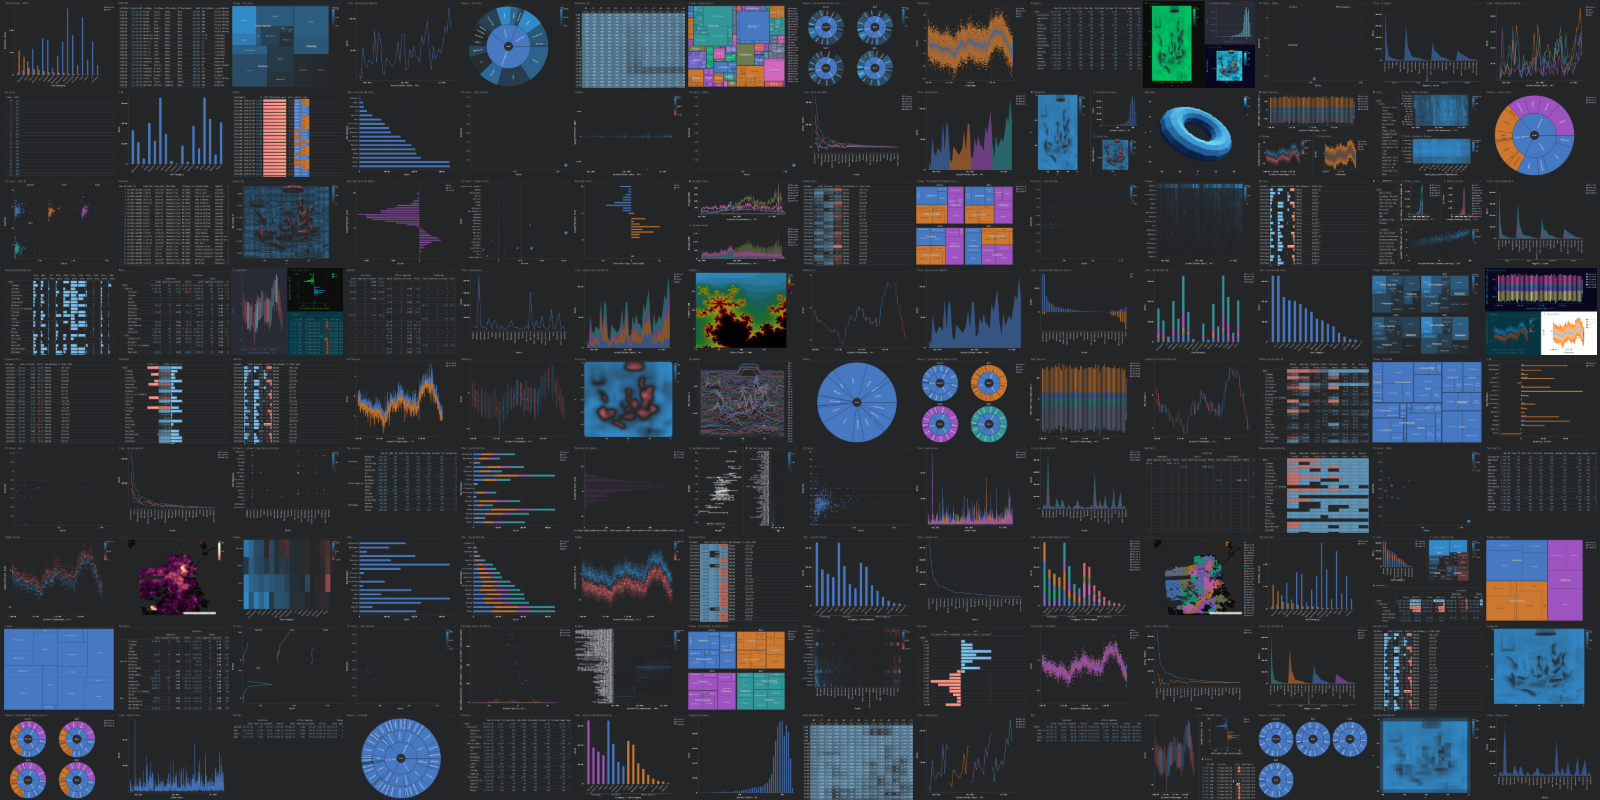 +
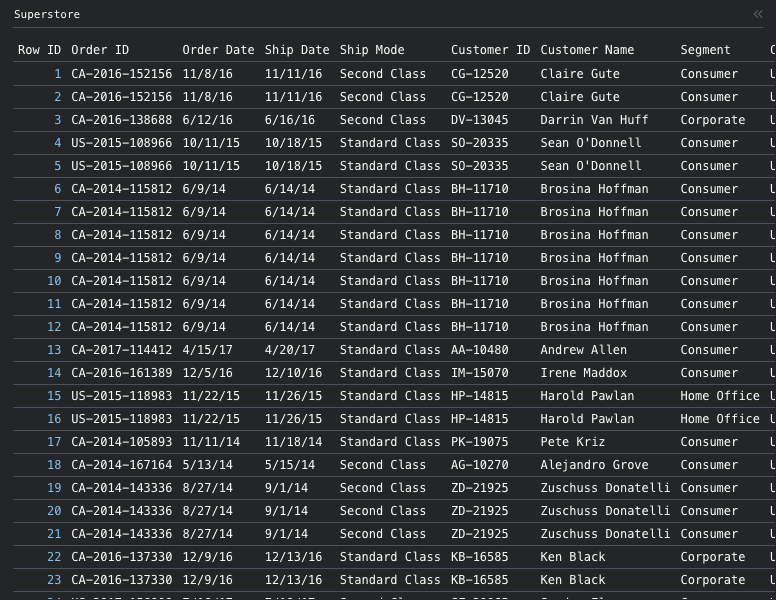
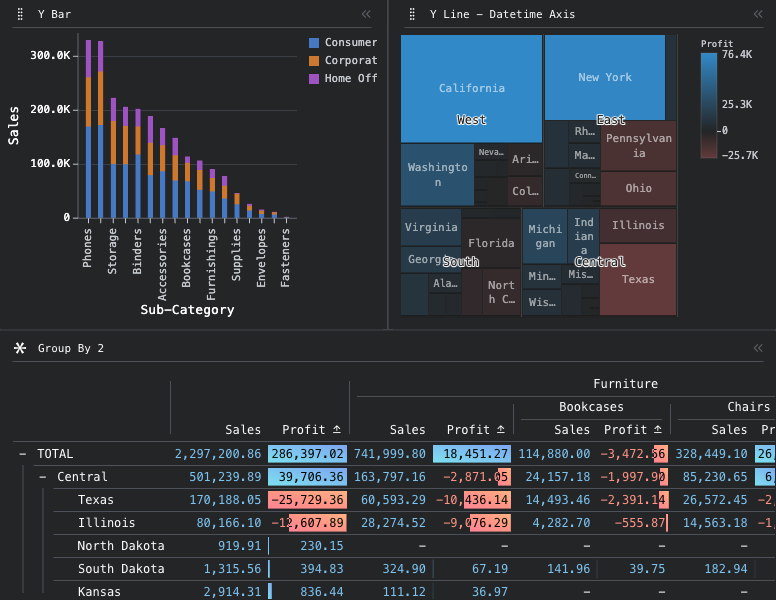
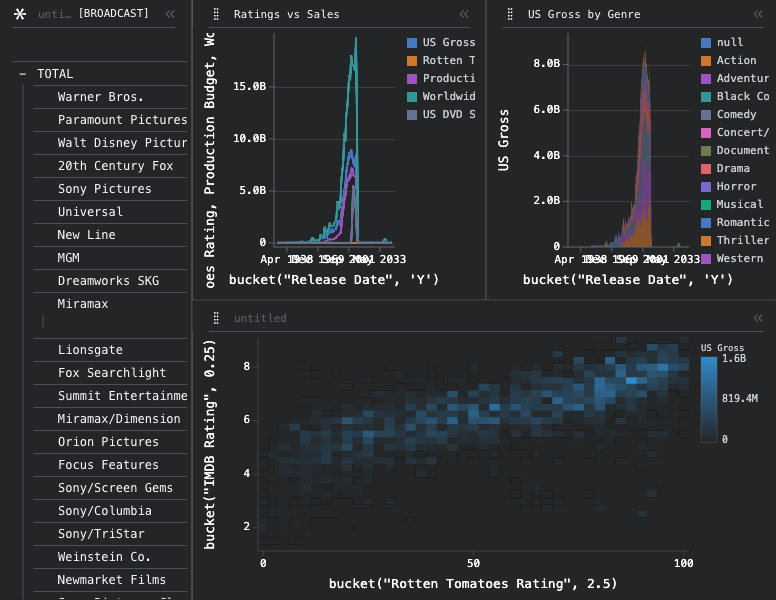
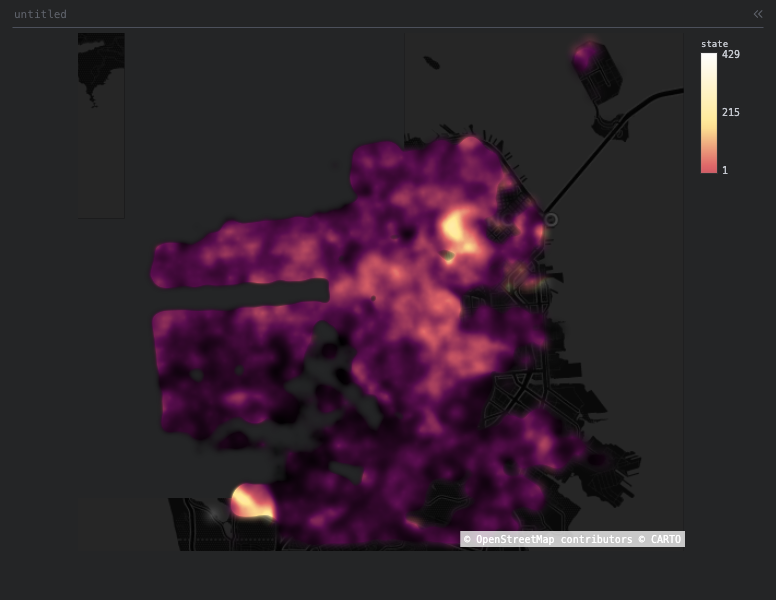
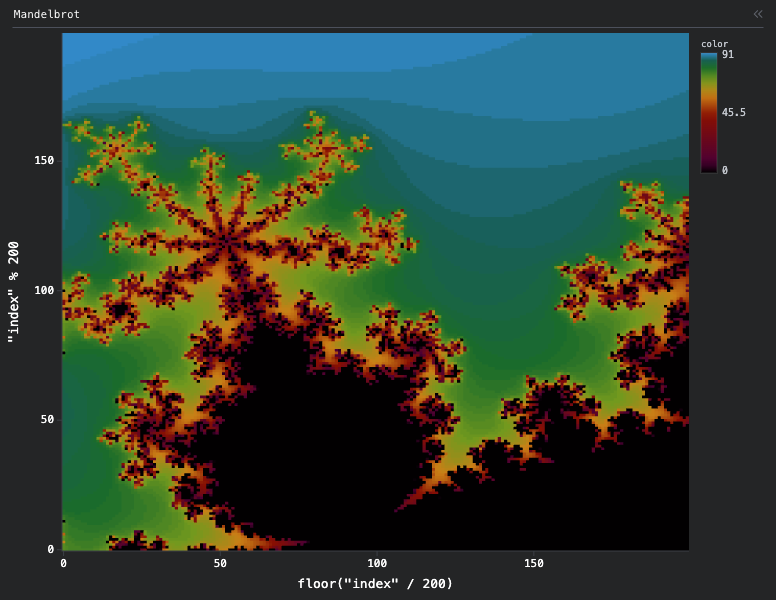




 +

}.png)
 +