You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
{{ message }}
Repository navigation
perf(server): active thread reads filter on the archived_at column - #28992
Several active-thread reads decide "is this thread archived" by parsing each row's payload JSON (json_extract(payload_json, '$.archivedAt') IS NULL). On a large database that means parsing thousands of payloads on every shell snapshot and sweep, even though orchestration_v2_projection_threads already stores archived_at as a column that is kept in sync on every upsert.
Change
These reads now filter on archived_at IS NULL instead of the payload JSON:
ProjectionStore.tsgetThreadWorktreePaths (when includeArchived is false)
ProjectionStore.tslistActiveSubagentThreadIds
ProjectionStore.tslistActiveShellIndex
ProjectionStore.tslistOlderSettledThreads
ThreadSearch.tsolderSettledTitleCandidates
ThreadSearch.tsolderSettledIds
Notes:
No migration, no schema change, no behaviour change.
The column is written from the payload on every upsert, and pullRequest/linkedThreads.ts already reads it.
'$.archivedAt' IS NOT NULL checks are left as they are.
Scope and approval
Small, focused performance fix for an obvious inefficiency, with no behaviour change. I think it fits the small-fix exception in CONTRIBUTING.
It leaves the three reads changed by open PR perf(server): index active thread sweep expressions #21777 untouched (the active shell read, settlement candidates, getThreadsWithPullRequests). The two PRs do not conflict and can be merged in either order.
Verification
Tests (cd apps/server):
vp test run src/orchestration-v2/ProjectionStore.test.ts src/orchestration-v2/ThreadSearch.test.ts: 2 files, 73/73 pass.
The same two files plus runtimeLayer, UsageLimitRecoveryWorker, storageCleanup, ws and serverRuntimeStartup tests: 7 files, 359/359 pass.
The usage-limit sweep test used to archive a thread with a raw json_set on payload_json, which never sets the column, so it failed after the change. It now archives and unarchives through real thread.archived / thread.unarchived events via store.apply, the same path production uses. It checks the thread is left out while archived and returned once unarchived.
The searchOlderSettled test had no archived case. It now has two archived settled threads: one title match (covers olderSettledTitleCandidates) and one passed in messageThreadIds (covers olderSettledIds). The expected results already leave them out.
The other four reads were already covered by existing tests.
Mutation check: for each of the 7 sites I replaced the archived condition with 1 = 1 and ran the covering test. Every mutation made a test fail. Source was restored afterwards.
Benchmark on a real database:
About 13 GB, ~9.6k threads, ~6.5k unarchived.
Opened read-only while the server was running. 3 warm-up pairs, then 15 alternating runs per variant.
The column and the payload disagree on 0 rows. Results were identical before and after for every query, and the query plans did not change.
Query
Before median
After median
getLimitRecoveryCandidates
0.077 ms
0.053 ms
getThreadWorktreePaths
52.416 ms
41.242 ms
listActiveSubagentThreadIds
50.762 ms
41.013 ms
listActiveShellIndex
114.87 ms
103.947 ms
listOlderSettledThreads (page)
45.03 ms
34.297 ms
listOlderSettledThreads (count)
49.058 ms
38.151 ms
olderSettledTitleCandidates
49.694 ms
39.085 ms
olderSettledIds (300 ids)
2.287 ms
1.944 ms
Filter only (deleted_at IS NULL AND <archive filter>)
44.534 ms
18.258 ms
Reads that scan the whole thread table get about 10-11 ms faster per call.
The usage-limit sweep narrows to 7 threads before the archive filter on this database, so the change there is for consistency, not speed.
Not checked:
Timings come from Python's sqlite3 (SQLite 3.46.1), not the server's node:sqlite driver, on Linux only. The before/after deltas matter more than the absolute numbers.
The upsert writes orchestration_v2_projection_threads.archived_at from the
payload, so these reads use the column instead of json_extract on payload_json:

- ProjectionStore getLimitRecoveryCandidates (usage-limit sweep)
- ProjectionStore getThreadWorktreePaths
- ProjectionStore listActiveSubagentThreadIds
- ProjectionStore listActiveShellIndex
- ProjectionStore listOlderSettledThreads
- ThreadSearch olderSettledTitleCandidates
- ThreadSearch olderSettledIds

Tests archive through the projector in the limit-recovery case and add
archived threads to the searchOlderSettled case.
Macroscope's review found this PR approvable — Active-thread queries now filter on the existing archived_at column instead of extracting the value from JSON. Projection writes already maintain that column alongside the payload, limiting this change to read-query performance with no intended product behavior change.
You can add or adjust custom eligibility rules. Learn more.
No actionable comments were generated in the recent review.
Walkthrough
Projection and thread-search queries now use archived_at to exclude archived threads. The worktree-path query retains its includeArchived option. Tests cover archived-thread exclusion and recovery-candidate filtering.
Changes: Archived thread filtering
Layer / File(s)
Summary
Use archived_at in thread queries apps/server/src/orchestration-v2/ProjectionStore.ts, apps/server/src/orchestration-v2/ThreadSearch.ts, apps/server/src/orchestration-v2/ProjectionStore.test.ts, apps/server/src/orchestration-v2/ThreadSearch.test.ts
Projection and thread-search queries use archived_at instead of reading archive state from the payload. Tests cover archive and settled-state filtering. The worktree-path query still includes archived threads when includeArchived is true.
pingdotgg/t3code#24660 — Replacing payload-based archive checks may reduce reader occupancy for the affected reads. The change does not add reader concurrency or transcript caching.
pingdotgg/t3code#24895 — The change replaces JSON archive predicates with archived_at IS NULL in affected queries. Other causes described in the issue are unchanged.
pingdotgg/t3code#22026 — The usage-limit recovery candidate query now filters archived threads with t.archived_at IS NULL. Retry-after-refusal behavior is unchanged.
Suggested reviewers:t3dotgg
Merge Risk: Minimal · up to fe938
The indexed archive filtering is consistent with the existing V2 projection state and is ready to merge.
Pre-merge checks: 4
Check name
Status
Explanation
Title check
The title clearly and concisely identifies the main performance change: active thread reads now filter on the archived_at column.
Description check
The description includes complete Problem, Change, Scope and approval, and Verification sections. It explains the behavior, affected queries, approval rationale, test results, benchmarks, mutation che…
Linked Issues check
Check skipped because no linked issues were found for this pull request.
Out of Scope Changes check
Check skipped because no linked issues were found for this pull request.
Full details: Description check
Explanation
The description includes complete Problem, Change, Scope and approval, and Verification sections. It explains the behavior, affected queries, approval rationale, test results, benchmarks, mutation checks, and known limitations.
Finishing Touches
Generate unit tests (beta)
Create a new PR
Autofix · Keep fixing CodeRabbit findings and required CI, and resolving merge conflicts
Tip
🎯 Customize your risk assessments
Guide how CodeRabbit assesses merge risk and security architecture risk. Highlight sensitive changes and explain your security boundaries using Merge Risk Instructions and Security Risk Instructions in your review settings. Security architecture risk assessments require the Advanced plan or above.
✅ Automatic approvals, with your rules
Let CodeRabbit approve pull requests once required threads are resolved, pre-merge checks pass, and your risk limits are met. Enable Automatic approvals in review settings, with overrides for teams or file paths.
Included review availability: This review used your included allowance. Your plan provides up to 10 included reviews per hour; 9 remain after this review.
Data from a real database for this PR. Our orchestration_v2_projection_threads has 7,524 threads with 34 MB of payload JSON; statev2.sqlite is 49 GB. On a copy:
Both filters select the same 3,454 non-deleted, unarchived threads. No row matches one filter and not the other, so the column is in sync with the payload here.
A full scan with json_extract(payload_json, '$.archivedAt') IS NULL takes 1.5–1.6 s, and one with archived_at IS NULL takes 1.0–1.1 s. That is the sqlite3 CLI with NOT INDEXED, two runs each.
On main at a044f0c0b3, three more reads still filter on the payload and are not in this PR: selectShellThreadRows, getSettlementCandidates and getOpenRemoteDelegatedTasks. The first is the shell snapshot's thread-row read.
We run the same change as a local patch, for the shell and settlement reads as well, and have seen no problems with it.
Measured and written by Claude (Opus 5.5) in T3 Code; posted with the owner's approval.
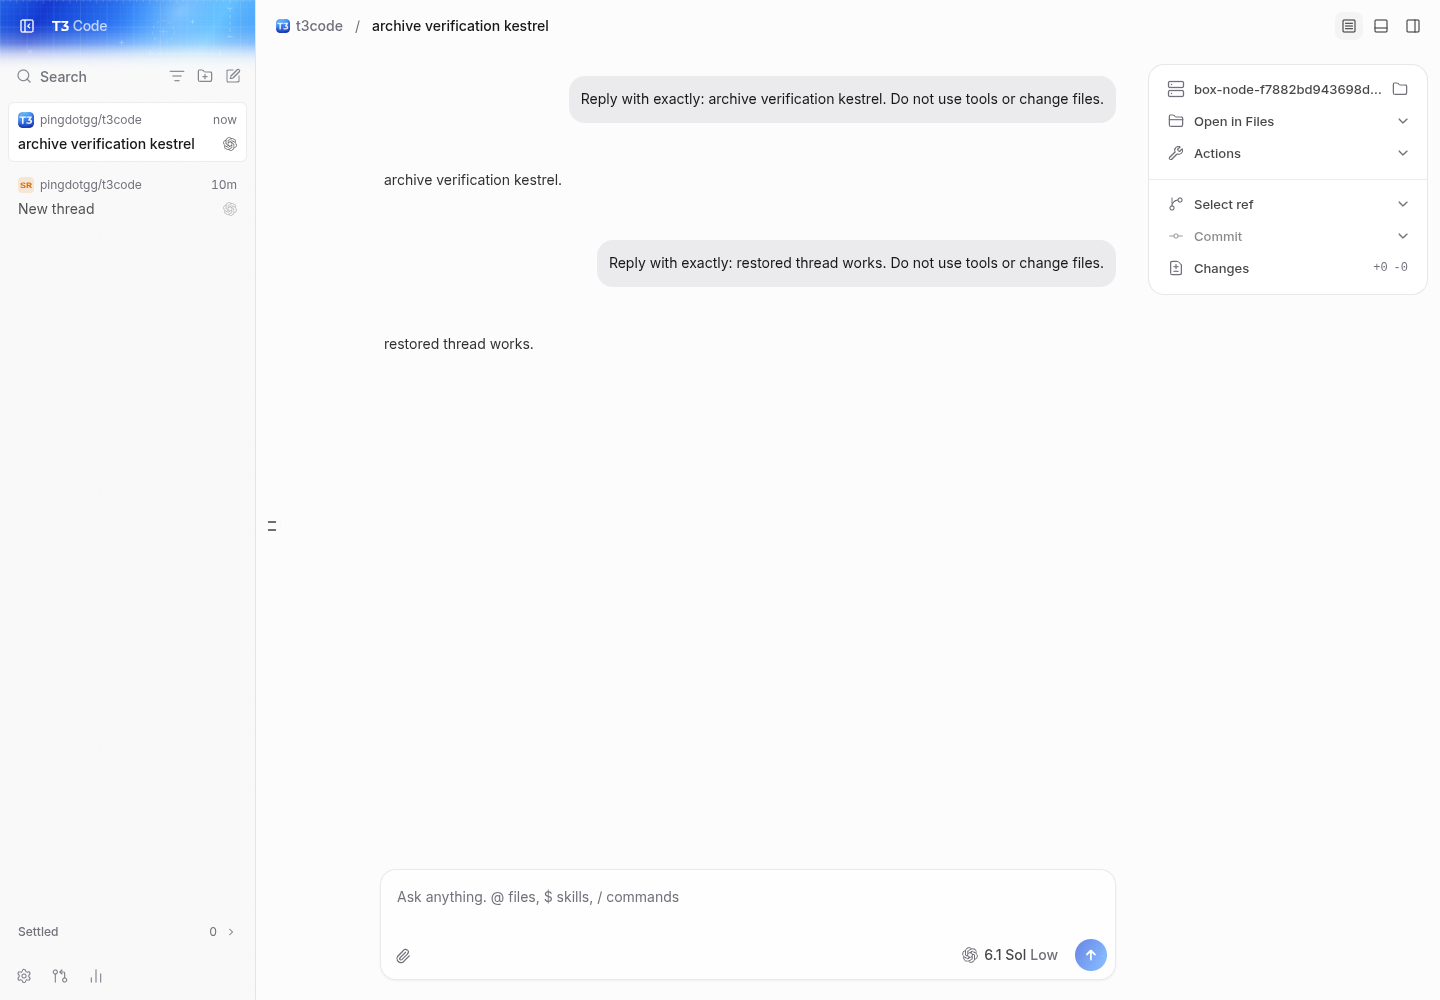
Verified head fe938684abe51b5c61d4c6f48aa3e47e9158e996 on Linux using the real dev web app, repository Playwright, /usr/bin/google-chrome, and real Codex gpt-6.1-sol turns. No mocks, fixtures, demo data, or direct database edits. No code changes.
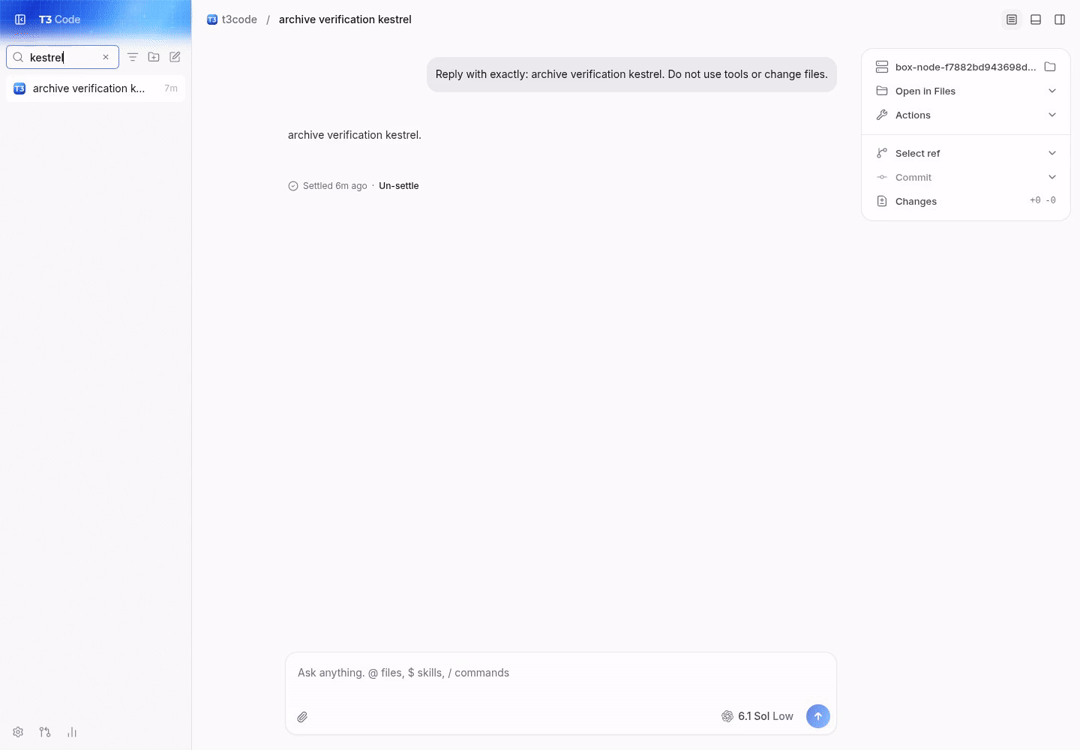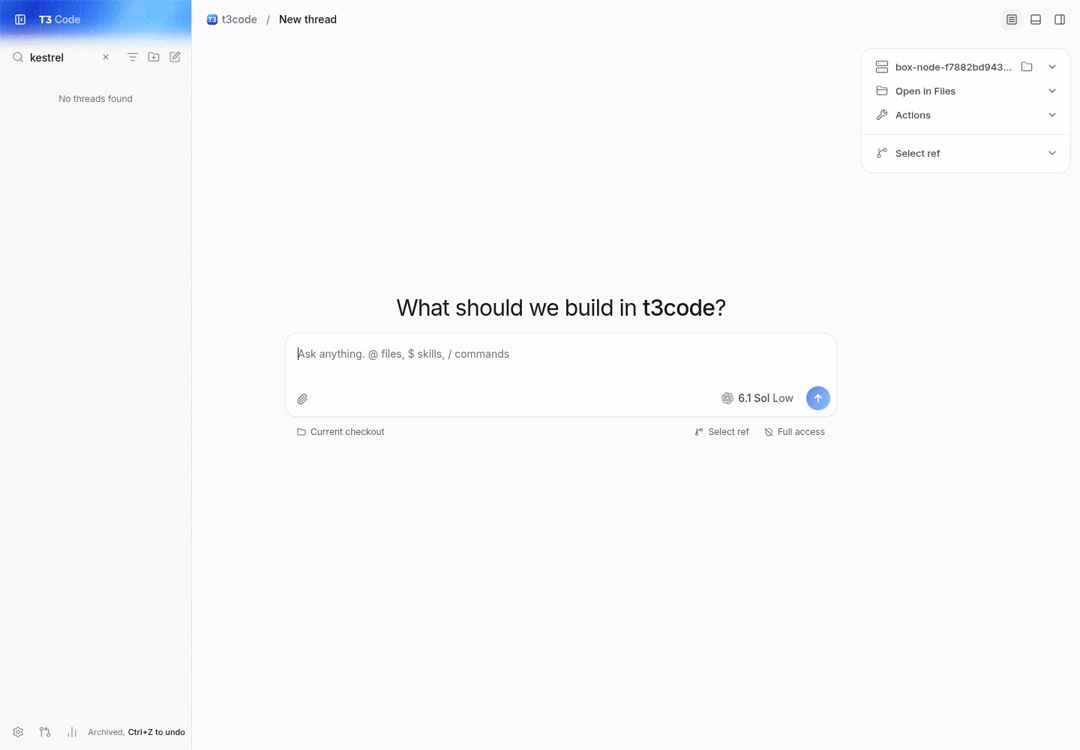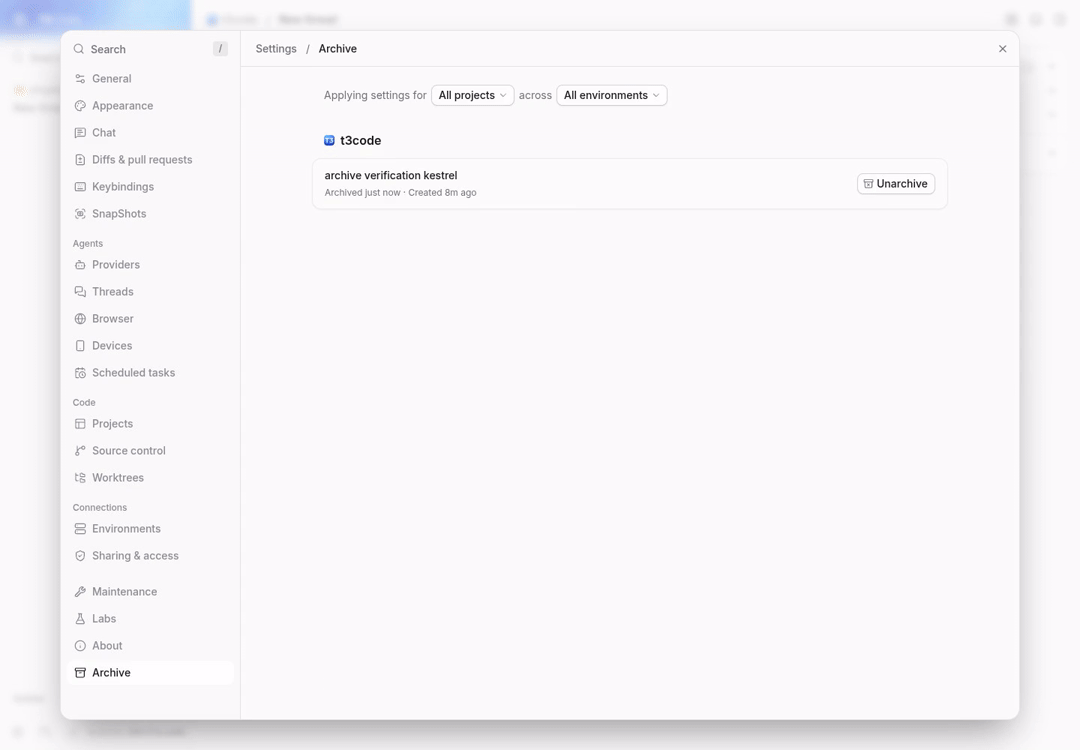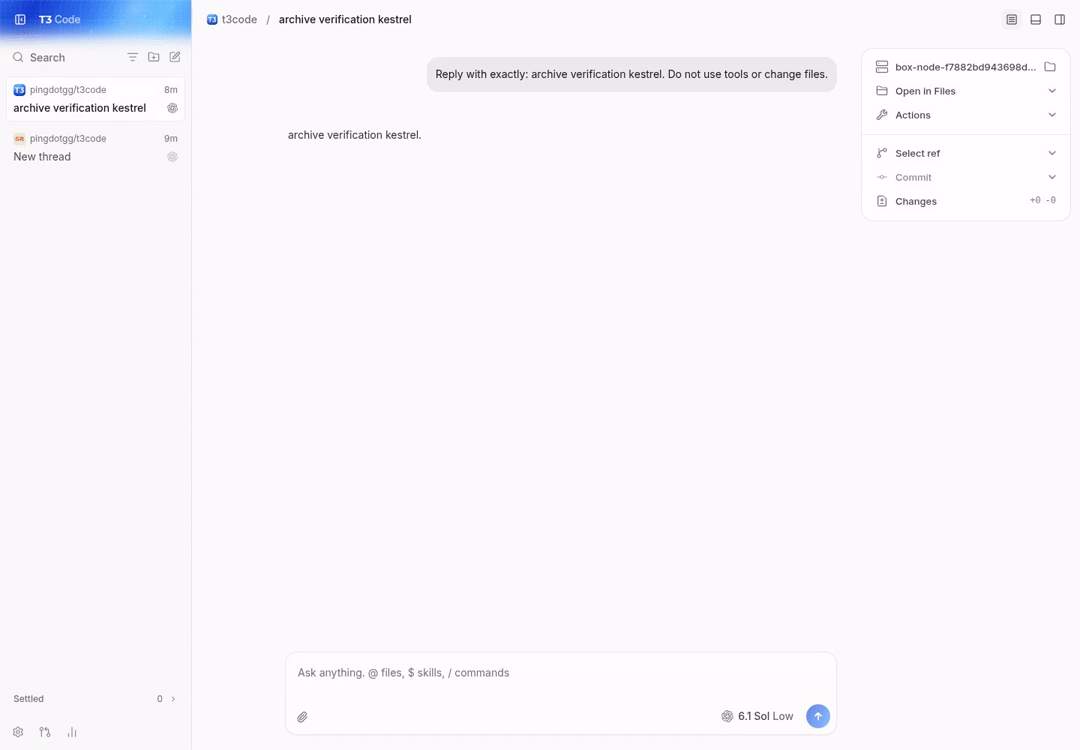
Started github/main at 35b88636d4 in a separate worktree first. Created a project through the app, completed a real provider turn, settled it, searched for it, archived it, and found it in Settings > Archive. Main already has correct visible archive behavior; this PR is a query optimization. Stopped main before starting the exact PR head with isolated empty state and vp i.
On the PR, created a project pointing at the real checkout and completed a Codex turn. Through the app UI and its authenticated WebSocket connection:
Settled thread: older-settled listing and count both returned 1. Title-only search and message-content search returned the thread.
Archived through the UI: listing and count became 0, both older-settled searches excluded it, and the archived snapshot included it.
Restored through Settings > Archive: listing and count returned to 1 and both searches returned it again. Un-settled it and completed a second real Codex turn in the same thread. Both persisted runs report completed.
Existing ProjectionStore.test.ts and ThreadSearch.test.ts passed on Blacksmith: 78 tests across 2 files. Current forge checks: 29 successful, 0 pending, 0 failing.
The older-settled API checks used a cursor after the actual settle time to reach those reads immediately, without changing stored timestamps.
before archive: page=1, count=1, title hit=true, message hit=true, archived=false
archived:       page=0, count=0, title hit=false, message hit=false, archived=true
restored:       page=1, count=1, title hit=true, message hit=true, archived=false
provider runs: ordinal 1 completed; ordinal 2 completed; model gpt-6.1-sol
Not verified
The original large-database slowdown and performance gain were not reproduced or measured through the real user path. This small, app-created dataset proves filtering correctness, not speed.
Actual provider usage-limit recovery, subagent lifecycle, and worktree cleanup were not induced in the running app. The focused existing suites cover the changed queries, but that is not live integration proof for these paths.
Native mobile, Electron desktop, macOS/Windows, and relay/tunnel connections were not exercised on this Linux VM.
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
size:S10-29 changed lines (additions + deletions).vouch:unvouchedAuthor is not yet trusted in the VOUCHED list.
3 participants
Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.


 github-actions
Bot
added
vouch:unvouched







Problem
Several active-thread reads decide "is this thread archived" by parsing each row's payload JSON (
json_extract(payload_json, '$.archivedAt') IS NULL). On a large database that means parsing thousands of payloads on every shell snapshot and sweep, even thoughorchestration_v2_projection_threadsalready storesarchived_atas a column that is kept in sync on every upsert.Change
These reads now filter on
archived_at IS NULLinstead of the payload JSON:ProjectionStore.tsgetLimitRecoveryCandidates(usage-limit sweep)ProjectionStore.tsgetThreadWorktreePaths(whenincludeArchivedis false)ProjectionStore.tslistActiveSubagentThreadIdsProjectionStore.tslistActiveShellIndexProjectionStore.tslistOlderSettledThreadsThreadSearch.tsolderSettledTitleCandidatesThreadSearch.tsolderSettledIdsNotes:
pullRequest/linkedThreads.tsalready reads it.'$.archivedAt' IS NOT NULLchecks are left as they are.Scope and approval
getThreadsWithPullRequests). The two PRs do not conflict and can be merged in either order.Verification
Tests (
cd apps/server):vp test run src/orchestration-v2/ProjectionStore.test.ts src/orchestration-v2/ThreadSearch.test.ts: 2 files, 73/73 pass.runtimeLayer,UsageLimitRecoveryWorker,storageCleanup,wsandserverRuntimeStartuptests: 7 files, 359/359 pass.vp run check:changed: pass (format, lint, knip, graphql, typecheck, 74/74 tests).Test changes:
json_setonpayload_json, which never sets the column, so it failed after the change. It now archives and unarchives through realthread.archived/thread.unarchivedevents viastore.apply, the same path production uses. It checks the thread is left out while archived and returned once unarchived.searchOlderSettledtest had no archived case. It now has two archived settled threads: one title match (coversolderSettledTitleCandidates) and one passed inmessageThreadIds(coversolderSettledIds). The expected results already leave them out.1 = 1and ran the covering test. Every mutation made a test fail. Source was restored afterwards.Benchmark on a real database:
getLimitRecoveryCandidatesgetThreadWorktreePathslistActiveSubagentThreadIdslistActiveShellIndexlistOlderSettledThreads(page)listOlderSettledThreads(count)olderSettledTitleCandidatesolderSettledIds(300 ids)deleted_at IS NULL AND <archive filter>)Not checked:
node:sqlitedriver, on Linux only. The before/after deltas matter more than the absolute numbers.Written by Claude Opus 5.5 in Claude Code (T3 Code).