You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
{{ message }}
Repository navigation
fix(shared): the SQLite reader pool comes back after a failed start - #30818
When one SQLite reader worker fails to start (an open error, a database not in WAL mode, or the 10 s start timeout), nodeSqliteClient turns the whole reader pool off for the rest of the process. Every read then runs on the writer until the server restarts, queued behind writes. A transient failure is enough: on main, after one failed start no reader starts again (in a test, none in 10 virtual minutes and 5 later reads).
Change
A failed reader start turns the pool off with one warning; reads use the writer meanwhile, as today.
One background retry brings the pool back: 1 s, doubling to 60 s, silent while it keeps failing, and one log line when readers are back. The retry belongs to the client and stops when it closes.
A database that is not in WAL mode keeps readers off for good, with one warning and no retries. The reader's refusal now carries a code, ERR_SQLITE_NOT_WAL, so the retry can tell it apart.
A gauge, t3_sqlite_reader_pool_available (0 or 1), shows the state.
The change is in makeReader, the reader pool's wrapper around the shared worker connection; the writer is unchanged. The backoff is fixed in code; there is no setting. One file: packages/shared/src/nodeSqliteClient.ts. Server only; no client or contract change.
Scope and approval
This is submitted under the contributing guide's exception for a very small, focused fix to an obvious bug: the defect is shown by tests that fail on main (below), the product change is +65/−5 lines in one file (the rest is tests), and apart from the availability gauge it adds no behaviour, default or setting.
A focused reliability fix for an obvious defect: today a transient start failure leaves readers off for the life of the process. It changes no product default, setting or contract. The only addition beyond the fix is the availability gauge, so the state can be seen. A separate follow-up PR edits the same file; it will be opened after this one.
Background and measurements: #31002 (context, not an approval request).
Verification
Failing first (test clock and queues only; the tests assert events and counts, never elapsed time). The tests were committed alone first and fail on main @ 9db3cb109 by assertion:
vp test run packages/shared/src/nodeSqliteClient.test.ts -t "until a retry starts the reader again": two cases, a reader that crashes at start and one that times out at start. Reads go to the writer, a retry starts the reader again, reads route back to the readers and the gauge goes 1 → 0 → 1. Both fail on main.
-t "backs off a reader that never starts without logging each retry": 12 retries in 10 virtual minutes (1 s doubling to a 60 s cap) and exactly one log line. Fails on main.
-t "keeps readers off without further retries when": not in WAL mode, found at start or by a retry; one warning and no further retries. main also leaves readers off in both cases; there they fail only on what this change adds (the gauge, and the retry).
-t "stops retrying the reader when the client closes": closing the client while the retry waits, or while a retried reader is starting, leaves no reader starting in the 10 virtual minutes after. On main, which never retries, only the second fails; both fail when the retry is made to outlive the client.
On main @ 9db3cb109, six of the seven cases above fail and the file's other 28 tests pass; with this change, 35/35 pass. Removing any of the three gauge updates, the not-WAL code, the backoff growth, the one-line logging, the retry's context isolation or the retry's tie to the client's scope each fails a test (mutation checks).
vp run check:changed: passes (format, lint, knip, typecheck of 35 packages, and 37 tests in the 2 affected test files), on macOS with Node 26.12.1. The server integration suites (vp test run apps/server/integration) also pass, 364 tests in 26 files, and so do the provider replay fixture suites (vp test run apps/server/src/orchestration-v2/testkit), 252 tests in 17 files, and the other tests that start reader workers (apps/server/src/persistence and the opencode usage reader), 89 passed and 1 skipped.
No benchmark: the problem appears only when a reader start fails, which a load benchmark does not exercise.
Not checked
A real start failure under load on a running server; the evidence is tests on a virtual clock.
Windows.
Unchanged model: the whole pool still turns off when any one reader fails to start, and reads use the writer until the retry succeeds.
Made with Claude Opus 5.5 via Claude Code. Reviewed by GPT-6.1 Sol via Codex.
When a reader worker failed to start, the client turned the reader pool
off for the rest of the process, so every read ran on the writer
connection until a restart. A failed start now turns the pool off with
one warning, and a background retry (1 s, doubling to 60 s) brings it
back. A database that is not in WAL mode keeps readers off without
retrying. A gauge, t3_sqlite_reader_pool_available, shows the state.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Macroscope's review found this PR approvable — SQLite reader workers now recover automatically after transient startup failures, with capped backoff and availability metrics. Existing read-only safeguards and main-connection fallback remain in place, limiting the change to reader availability.
You can add or adjust custom eligibility rules. Learn more.
verified as-is at e667d990c0bf4177ea30ed18fc6bf8196fe01f09 on linux. ran vp i and background dev servers, one at a time. used repository playwright with /usr/bin/google-chrome, created a real git project and threads through the web app, and sent real codex gpt-6.1-sol turns through the local proxy. no mocks or seeded data.
reproduced on github/main (9e85538535) in a separate worktree, then repeated on this exact head. the fault retired a real reader through the node debugger and briefly denied access to the task's userdata directory, so its replacement failed its actual sqlite open. restored permissions without restarting the server. this also temporarily denied trace/provider-log writes; the gauge collector stayed outside the affected directory.
main: open failure logged at 14:20:26 UTC
      after access restored: 165 writer-routed operations, 0 reader-routed
      over 86 seconds; another codex turn and history reload succeeded

pr:   14:31:27.068 reader unavailable: unable to open database file
      14:31:31.038 filesystem access restored
      14:31:33.393 successful SELECT on writer fallback
      14:31:34.161 reader available again, without server restart
      actual OTLP availability gauge: 1 -> 0 -> 1
      following window: 155 reader-routed operations, 14 writer-routed
follow-up send, a fresh thread with another real codex response, and history reload passed after recovery. the counts above include only spans with an explicit connection annotation. these are recovery observations, not a performance benchmark.
blacksmith passed the 24 sqlite tests and vp run check:changed 8b44f42b14c8e273156474a924ccf29680dd7857: format, lint, knip, 34 affected package typechecks, and 25 tests. the explicit base supplies the pr ancestry missing from the remote snapshot's initial history. existing github checks: 29 successful, none failing or pending.
native ios/android, the electron shell, windows/macos, and remote relay/tunnel connections were not exercised on this linux vm. the running-app fault covered a transient open failure; startup timeout, the 60-second retry cap, permanent non-wal disablement, and closing during retry were not exercised in the app. the existing focused sqlite tests passed. no code changes were needed.
Closing the client while the reader retry waits, or while a retried
reader is starting, leaves no reader starting afterwards.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Written by Claude Opus 5.5 (Claude Code) on behalf of Navid
Thanks for checking it in a running app, and for the gauge trace. On the paths you didn't exercise: the start timeout, the 60 s cap and the permanent non-WAL stop each have a focused test (the timeout case of "until a retry starts the reader again", "backs off a reader that never starts without logging each retry", and "keeps readers off without further retries when …"). Closing during a retry had no dedicated test, so I've added one in db37135e0: the client closes while a retry is waiting, or while a retried reader is starting, and no reader starts in the 10 virtual minutes after. It fails if the retry outlives the client.
It looks like this branch is under active development. To avoid overwhelming you with review comments due to an influx of new commits, CodeRabbit has automatically paused this review. You can configure this behavior by changing the reviews.auto_review.auto_pause_after_reviewed_commits setting.
No actionable comments were generated in the recent review.
Walkthrough
The SQLite client now classifies reader-worker startup failures, retries transient failures with exponential backoff, and stops retries for non-WAL failures. Reads use the writer while readers are unavailable. Tests cover recovery, retry timing, client closure, and non-WAL cases.
A failed SQLite reader start now recovers in the background with capped backoff, and reads fall back to the writer in the meantime. No merge-blocking risk was found.
Pre-merge checks: 4
Check name
Status
Explanation
Title check
The title names the main change: the SQLite reader pool recovers after a failed start. The changeset adds background retries with backoff, reader-pool recovery, and a non-WAL error code in nodeSqliteC…
Description check
The description follows the repository template. It has Problem, Change, Scope, and Verification sections, and each has specific content. The Problem section explains the failure and expected behavior…
Linked Issues check
Check skipped because no linked issues were found for this pull request.
Out of Scope Changes check
Check skipped because no linked issues were found for this pull request.
Full details: Title check
Explanation
The title names the main change: the SQLite reader pool recovers after a failed start. The changeset adds background retries with backoff, reader-pool recovery, and a non-WAL error code in nodeSqliteClient, which the title describes accurately. The title follows the conventional commit format.
Full details: Description check
Explanation
The description follows the repository template. It has Problem, Change, Scope, and Verification sections, and each has specific content. The Problem section explains the failure and expected behavior. The Change section lists the fix and the affected file. The Scope section links background material and explains why the change fits the small bug-fix exception. The Verification section gives focused failing-first tests, mutation checks, the commands run, and a list of items not checked. The description also cites an agent model, as the template asks. The Scope section links a discussion, not an issue that shows the bug, so the reviewer may need that link. The description also says a separate follow-up PR edits the same file, which is context only.
Finishing Touches
Generate unit tests (beta)
Create a new PR
Autofix · Keep fixing CodeRabbit findings and required CI, and resolving merge conflicts
Reviewing files that changed from the base of the PR and between 9269085 and c9dcd47.
Files selected for processing: 2
packages/shared/src/nodeSqliteClient.test.ts
packages/shared/src/nodeSqliteClient.ts
Included review availability: This review used your included allowance. Your plan provides up to 10 included reviews per hour; 9 remain after this review.
…l-recovery

Resolve nodeSqliteClient.ts against the move to Effect.undefined: the
reader pool's two early returns use it in place of
Effect.succeed(undefined) and its diagnostics override.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…l-recovery

Resolve nodeSqliteClient.test.ts against the damaged-database test:
keep both sets of imports and both test blocks.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…l-recovery

Main rewrote nodeSqliteClient.ts around a shared worker connection for
readers and the writer, so the reader pool fix no longer applies as
written: take main's version of both files. The following commits
re-apply the fix on the new structure.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…start

A reader that fails to start turns the pool off for the rest of the
process. These tests expect a background retry with backoff to bring it
back, a gauge that shows the pool's state, no retries for a database
that is not in WAL mode, and no retries after the client closes. They
fail on main.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
When a reader worker failed to start, the reader pool turned off for the
rest of the process, so every read ran on the writer until a restart. A
failed start now turns the pool off with one warning, and one
background retry (1 s, doubling to 60 s) brings it back, with one log
line. A database that is not in WAL mode keeps readers off without
retrying. The retry belongs to the client and stops when it closes. A
gauge, t3_sqlite_reader_pool_available, shows the state. The writer is
unchanged.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Every reader-pool client shares one unlabelled gauge, so the OpenCode usage
reader overwrites the state database's value. The warn and info log lines
already report when the pool goes down and comes back.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
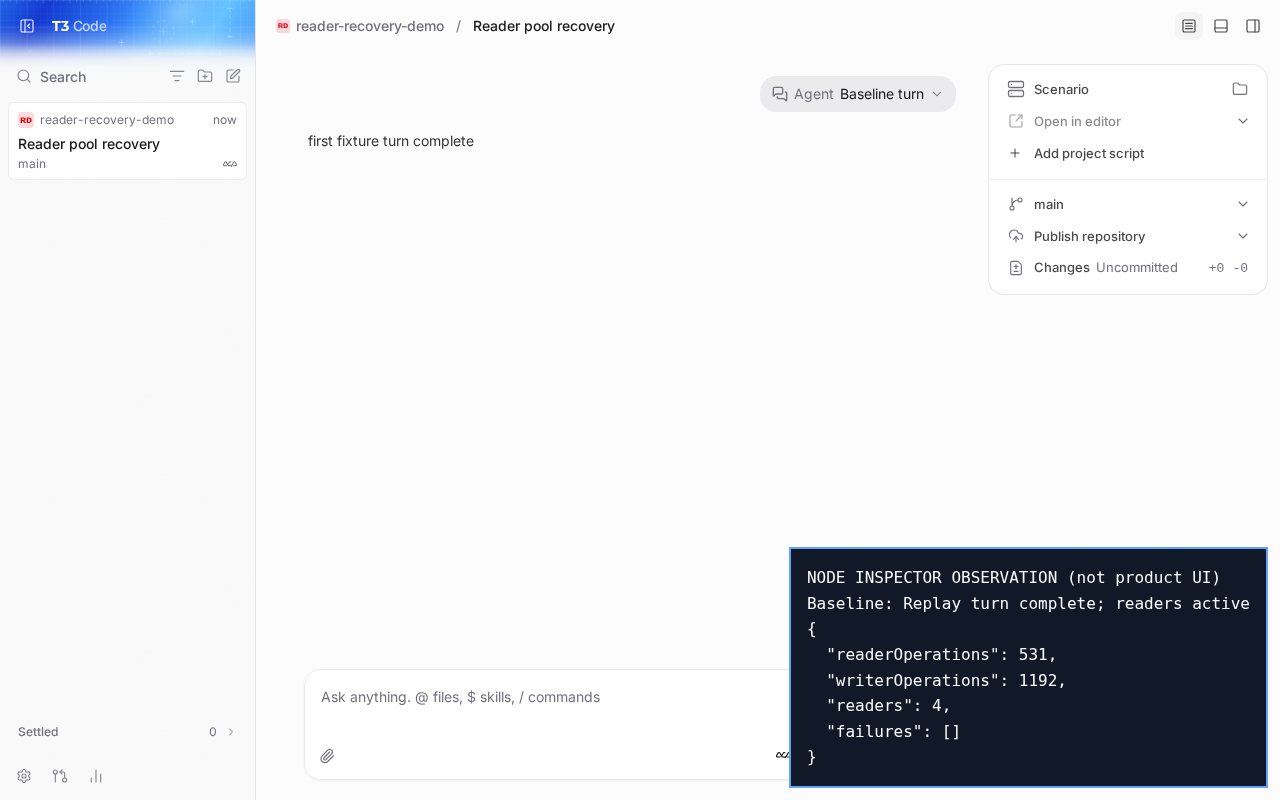
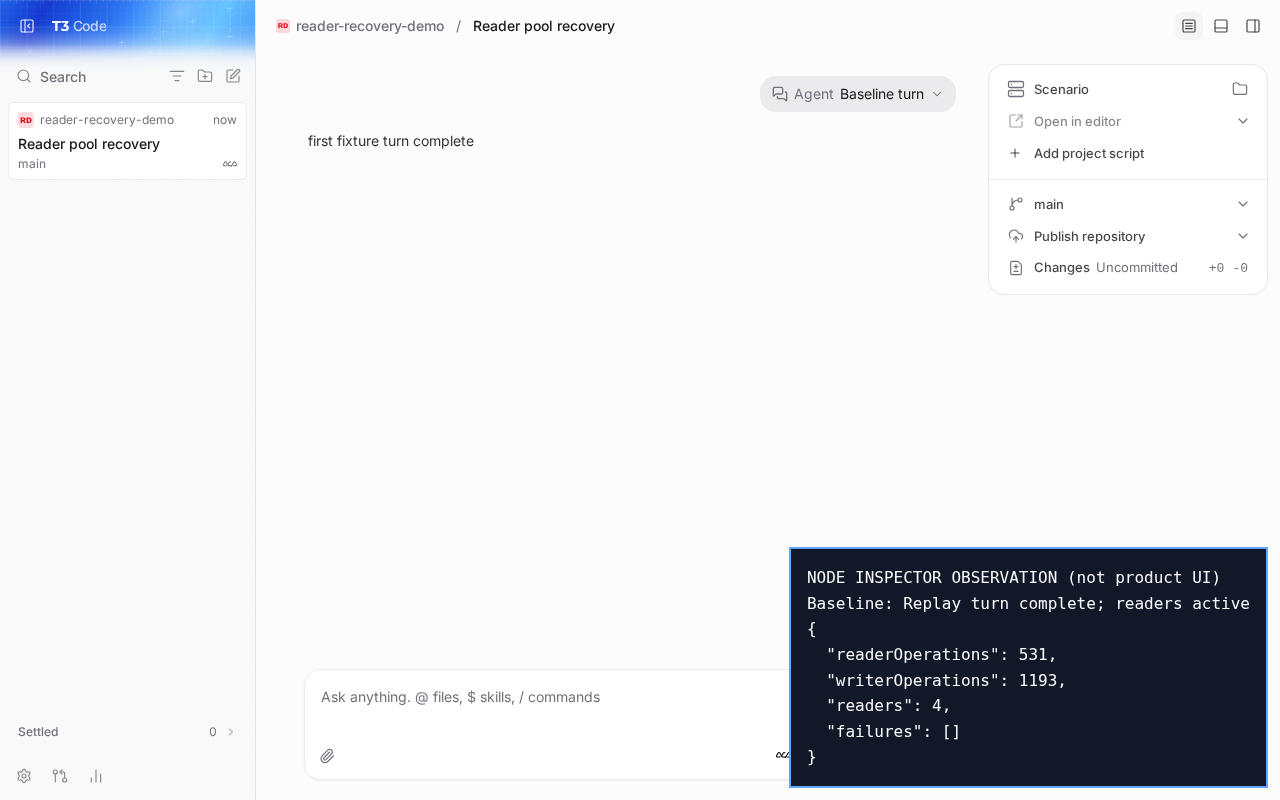
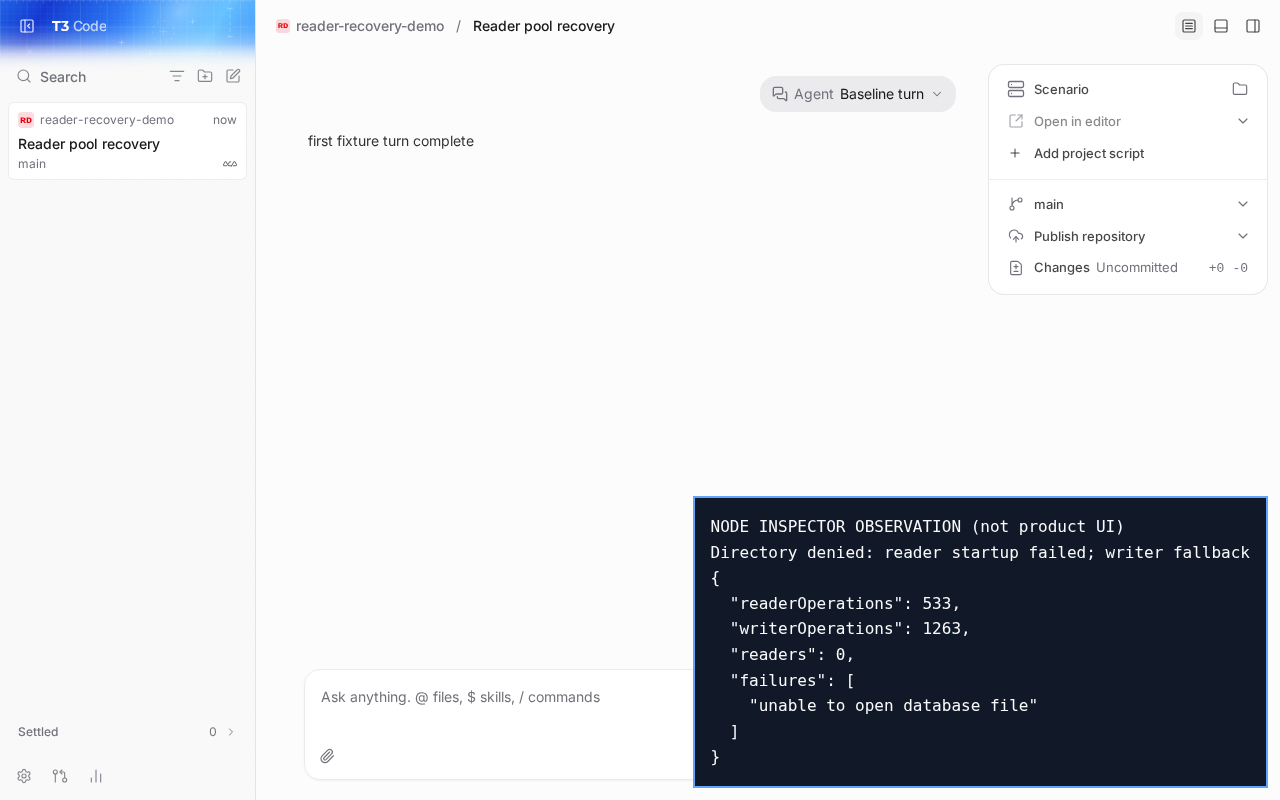
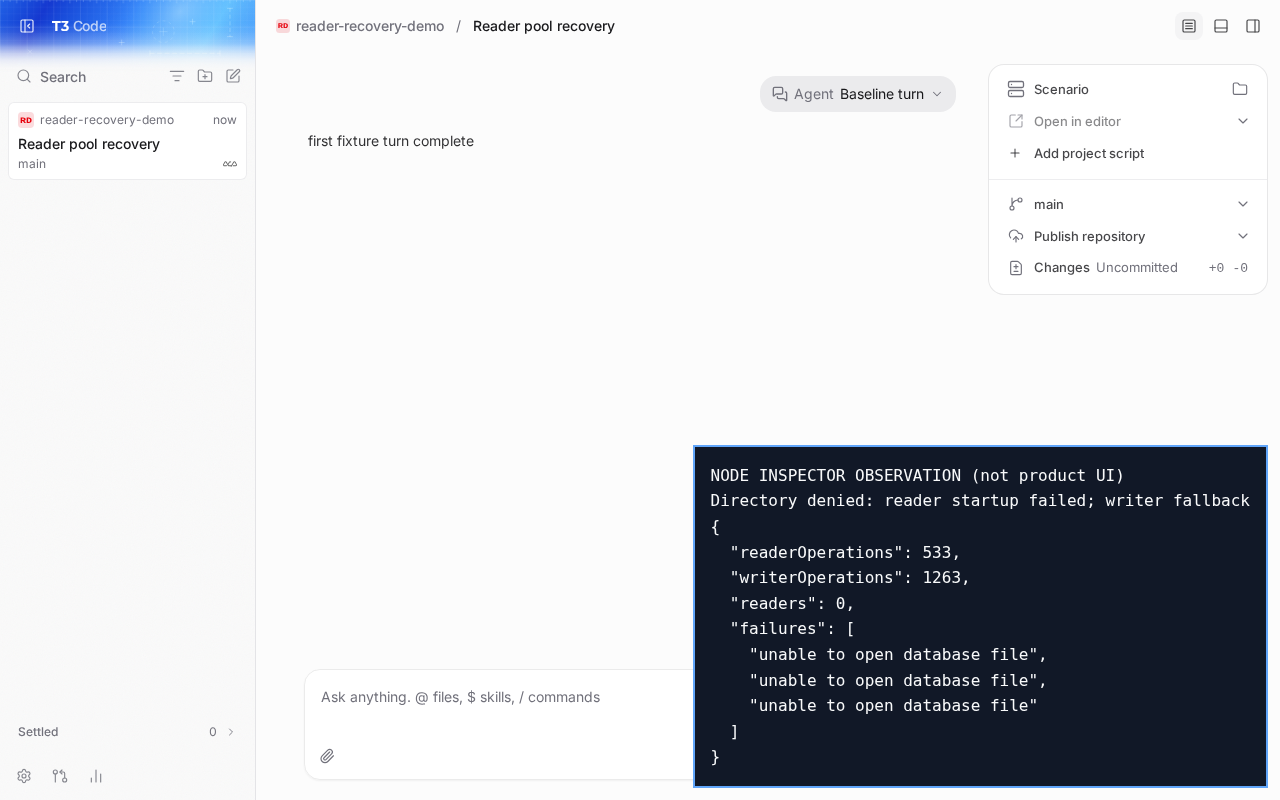
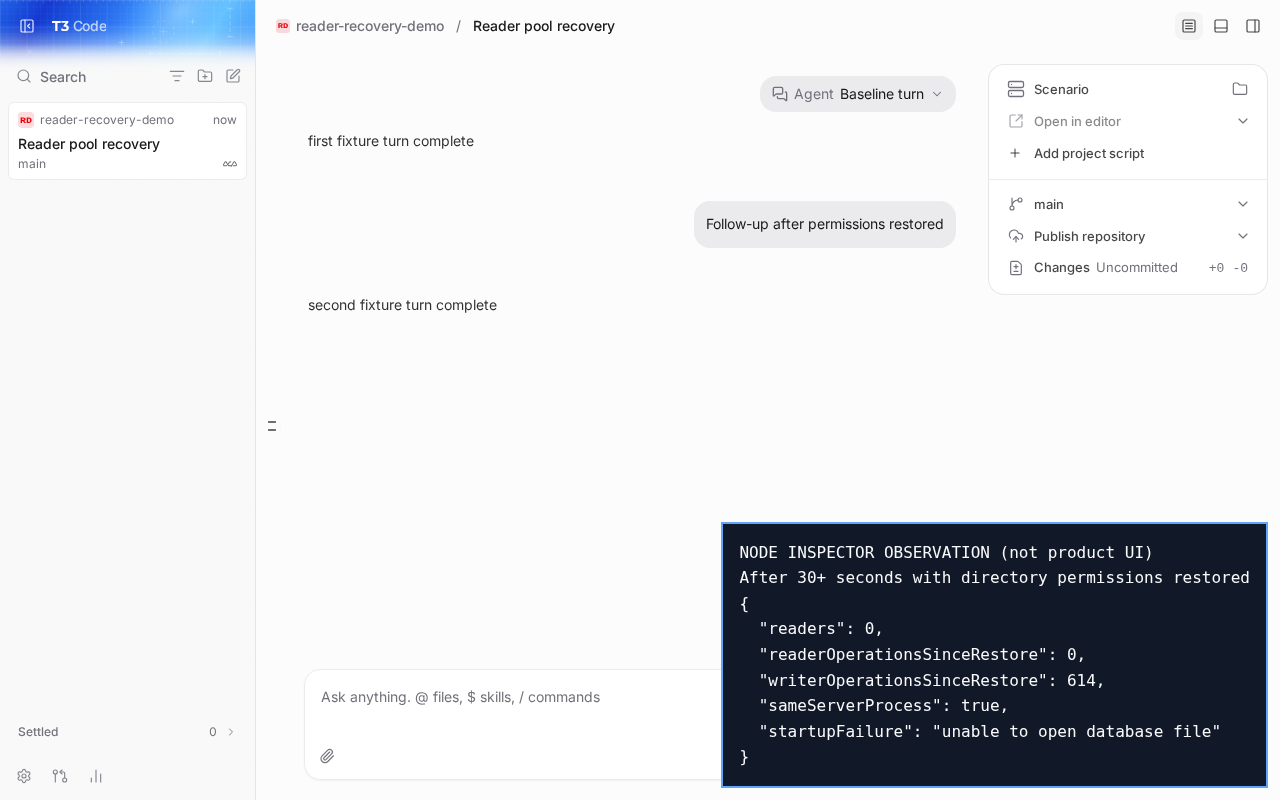
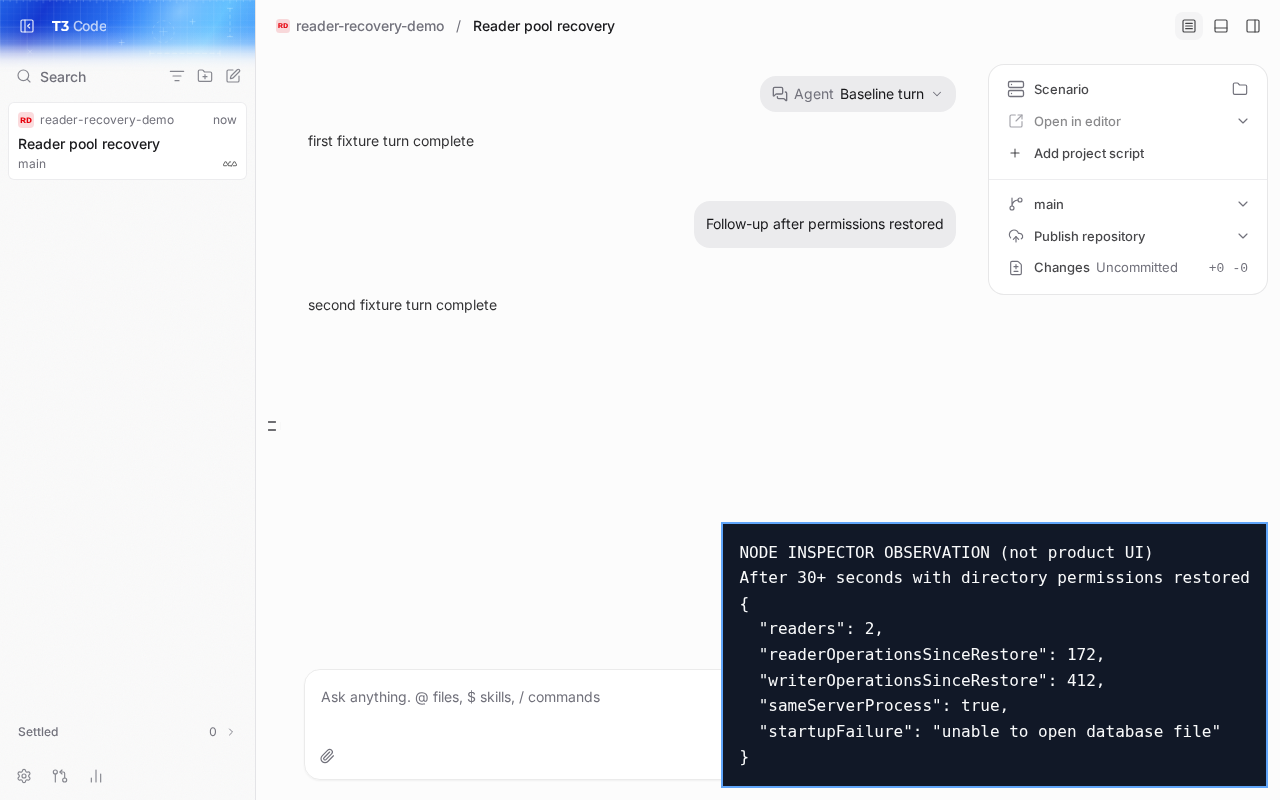
Identical reproduction on fresh databases: complete a baseline Replay turn; deny the userdata directory and retire readers; confirm reader startup failure and working writer fallback; restore permissions without restarting; send a follow-up turn and reload history three times over 30+ seconds. Linux, Chromium 156, 1280×800, light theme. Panels are explicitly labeled inspector observations, not product UI.
Base served 614 writer operations and zero reader operations after restoration. Head served 172 reader operations and 412 writer operations. Server PID remained unchanged on each side; both follow-up turns completed and survived history reloads.
The comparison parent received SIGTERM before summarizing; the proof summary was rebuilt with the runner's exported helpers from both completed reports.
Not shown:
The 10-second reader startup-timeout path was not exercised; the reproduced failure was an immediate directory-permission error.
Non-WAL failures stopping retries were not exercised; both app databases used WAL.
Closing the client cancelling pending recovery was not exercised.
Verification covered Linux web; desktop, mobile, and other operating systems were not separately exercised.
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
size:M30-99 changed lines (additions + deletions).vouch:unvouchedAuthor is not yet trusted in the VOUCHED list.
3 participants
Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.


 github-actions
Bot
added
vouch:unvouched







 juliusmarminge
added
the
takeover:in-progress




Problem
When one SQLite reader worker fails to start (an open error, a database not in WAL mode, or the 10 s start timeout),
nodeSqliteClientturns the whole reader pool off for the rest of the process. Every read then runs on the writer until the server restarts, queued behind writes. A transient failure is enough: onmain, after one failed start no reader starts again (in a test, none in 10 virtual minutes and 5 later reads).Change
ERR_SQLITE_NOT_WAL, so the retry can tell it apart.t3_sqlite_reader_pool_available(0 or 1), shows the state.The change is in
makeReader, the reader pool's wrapper around the shared worker connection; the writer is unchanged. The backoff is fixed in code; there is no setting. One file:packages/shared/src/nodeSqliteClient.ts. Server only; no client or contract change.Scope and approval
This is submitted under the contributing guide's exception for a very small, focused fix to an obvious bug: the defect is shown by tests that fail on
main(below), the product change is +65/−5 lines in one file (the rest is tests), and apart from the availability gauge it adds no behaviour, default or setting.A focused reliability fix for an obvious defect: today a transient start failure leaves readers off for the life of the process. It changes no product default, setting or contract. The only addition beyond the fix is the availability gauge, so the state can be seen. A separate follow-up PR edits the same file; it will be opened after this one.
Background and measurements: #31002 (context, not an approval request).
Verification
Failing first (test clock and queues only; the tests assert events and counts, never elapsed time). The tests were committed alone first and fail on
main@9db3cb109by assertion:vp test run packages/shared/src/nodeSqliteClient.test.ts -t "until a retry starts the reader again": two cases, a reader that crashes at start and one that times out at start. Reads go to the writer, a retry starts the reader again, reads route back to the readers and the gauge goes 1 → 0 → 1. Both fail onmain.-t "backs off a reader that never starts without logging each retry": 12 retries in 10 virtual minutes (1 s doubling to a 60 s cap) and exactly one log line. Fails onmain.-t "keeps readers off without further retries when": not in WAL mode, found at start or by a retry; one warning and no further retries.mainalso leaves readers off in both cases; there they fail only on what this change adds (the gauge, and the retry).-t "stops retrying the reader when the client closes": closing the client while the retry waits, or while a retried reader is starting, leaves no reader starting in the 10 virtual minutes after. Onmain, which never retries, only the second fails; both fail when the retry is made to outlive the client.On
main@9db3cb109, six of the seven cases above fail and the file's other 28 tests pass; with this change, 35/35 pass. Removing any of the three gauge updates, the not-WAL code, the backoff growth, the one-line logging, the retry's context isolation or the retry's tie to the client's scope each fails a test (mutation checks).vp run check:changed: passes (format, lint, knip, typecheck of 35 packages, and 37 tests in the 2 affected test files), on macOS with Node 26.12.1. The server integration suites (vp test run apps/server/integration) also pass, 364 tests in 26 files, and so do the provider replay fixture suites (vp test run apps/server/src/orchestration-v2/testkit), 252 tests in 17 files, and the other tests that start reader workers (apps/server/src/persistenceand the opencode usage reader), 89 passed and 1 skipped.No benchmark: the problem appears only when a reader start fails, which a load benchmark does not exercise.
Not checked
Made with Claude Opus 5.5 via Claude Code. Reviewed by GPT-6.1 Sol via Codex.
🤖 Generated with Claude Code