You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
{{ message }}
Repository navigation
fix(server): content search recovers after a slow first index - #33138
On a project whose first content index takes more than 15 seconds, content search fails and never recovers. At the timeout the index build fails, which destroys the finder and stops the scan, and the failed lookup stays cached. A refresh (after an agent run or a new file) drops that entry, and the next search starts a new scan from zero, which times out the same way. File-name search already tolerates this timeout; only content search does not.
To reproduce, open content search on a folder whose indexing outlasts 15 seconds. I used a real folder of 1.7 million files, which takes about 50 seconds.
Expected: an error while the first scan runs, then normal results once it finishes, with the same scan carried through.
Change
WorkspaceSearchIndex.make keeps the finder on a scan timeout for both variants, as the paths index already did, so the scan runs to completion.
While that first index is unfinished, searchContents returns the existing WorkspaceSearchIndexScanTimedOut instead of partial results, for the reason given in fix(server): return partial workspace index on timeout #11500: an unscanned file would read as "No results found". The check is getScanProgress().isWarmupComplete and not isScanning(), because isScanning() goes false before the content index exists, and also when the file walk dies, which would turn a dead scan into an empty result.
WorkspaceEntries.refresh loses its handler for that timeout, which can no longer happen.
useProjectContentSearch asks again 30 seconds after a scan-timeout failure has come back. Without this, a word that failed during the scan keeps its cached error for as long as it stays in use. The retry runs only after that failure has settled, so it cannot restart a search in flight, and a running grep cannot be cancelled on the server. Any other failure is left alone.
The client change is part of the same fix: the failure was cached in two places, and both have to let go of it.
Scope and approval
Submitted under the exception for a very small, focused fix of an obvious bug. Content search on a large project fails permanently, with no way to recover from the UI. The change extends timeout handling the paths index already has. It adds no setting and no workflow.
Verification
Built on 4013183. The six changed files are identical at 3fa57b9, where the real-app and Linux checks ran. Windows 11 and Ubuntu 24.04 (WSL2), Node 26.12.1.
Tests. Six new tests. On unmodified source five fail: content search still returns WorkspaceSearchIndexScanTimedOut after the scan ends, a refresh during the scan builds a second finder (finders: 2, expected 1), and the client never asks again after a scan timeout. The sixth guards that a real scan error still fails index creation, and passes both ways. With the fix, all three test files pass (36 of 36). The cases cover recovery with no refresh, concurrent searches, a refresh during the scan, a scan that ends with no content index, unreadable scan progress, and the client retry: none while a search is pending, one after the failure settles, cleared when the query changes or answers, none for other failures.
vp run check:changed passes: format, lint, knip, graphql, typecheck, tests beside the changes, React Compiler coverage.
Real search service, real folder.WorkspaceEntries under Node 26 with no mocks, on 1,692,328 files:
Unmodified: every search failed through 87 seconds, and the finder was destroyed at the timeout. With a refresh after the first failure, a second finder was built and it timed out too.
Fixed: the timeout is reported while indexing, then the expected file is found from 51 seconds on, with one finder throughout, with and without a refresh.
Real app, web UI and server from source, same folder:
Unmodified: 9 of 9 searches failed through 287 seconds.
Fixed, this patch on 3fa57b9, one word typed once during the scan and never retyped: the timeout error at 15 seconds, the retry at 45, the expected file at 53, and the screen stayed on results while I watched for another 87 seconds.
Retry count, from a temporary log line at the top of searchContents: two searches on the server, 30.0 seconds apart.
A search slowed to 45 seconds by a temporary sleep in searchContents starts once on the server and answers at 45.4 seconds, so a slow search is not restarted.
Closing the dialog 5 seconds after the timeout: no further search on the server in the next 72 seconds. Opening it again and searching found the file in 7.5 seconds.
apps/server suite on Windows. 38 files fail with or without this change, with the same 193 failing test names and none new (199 failed, 1016 passed, 30 skipped, in both runs of those files). They look Windows-related, such as symlinks and systemd. None is under src/workspace. The full 479-file run was done before a last two-line server edit that removes an unreachable handler; after that edit, the 38 files, the two search test files and check:changed were rerun.
CI steps on Ubuntu 24.04 (WSL2), this patch on 3fa57b9. knip, generated GraphQL checks, vp check, typecheck, build:desktop, the preload and built web boot checks all pass. Server suite: 479 files, 6,901 passed, 5 skipped. Web suite with Chromium: 531 files, 5,660 passed. The other 34 package tasks pass. No test failed.
Not checked: macOS and the packaged desktop app. No screenshots, since nothing changes visually.
Behaviour to know about:
While the first scan runs, the dialog still shows the generic "Failed to search workspace contents" text.
refresh on a timed-out content index now waits up to 15 seconds, as the paths index already does.
The finder stays alive up to the 15 minute idle limit (1.85 GB peak on 1.7 million files).
After the first scan ends, a word that timed out shows its results at its next retry, so up to 30 seconds later.
A rare term on that folder takes about 10 seconds. That is fff's own grep, measured without any T3 Code code: its time budget stays off until something matches. This change does not affect it.
Written by Claude Opus 5.5 in Claude Code. Reviewed by GPT-6.1 Sol.
Keep the finder alive when the first scan outlasts the 15 second wait,
and report the existing scan timeout until the content index is ready.
The web client asks again 30 seconds after that failure has come back.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
You have reached your Codex usage limits for code reviews. You can see your limits in the Codex usage dashboard.
To continue using code reviews, add credits to your account and enable them for code reviews in your settings.
Macroscope's review found this PR requires human approval — The change lets content search recover after a slow initial index and retries timed-out searches every 30 seconds. It also adds a line-level lint suppression, which requires human review under the configured policy.
You can add or adjust custom eligibility rules. Learn more.
Reviewing files that changed from the base of the PR and between eb4b2b7 and 83df3e4.
You can disable this status message by setting the reviews.review_status to false in the CodeRabbit configuration file.
Use the checkbox below for a quick retry:
Trigger review
No actionable comments were generated in the recent review.
Walkthrough
Content searches now report an initial scan timeout while scanning continues. Workspace refresh no longer recovers from that timeout. The web query schedules a refresh 30 seconds after a settled timeout.
Content searches check scan progress after an initial timeout and return WorkspaceSearchIndexScanTimedOut if warmup is incomplete. A test covers concurrent timeouts and a successful search after scanning finishes.
Workspace refresh during scan apps/server/src/workspace/WorkspaceEntries.ts
Workspace refresh no longer handles scan timeouts through its recovery path. The path still handles index creation and refresh failures.
Content search now recovers after a slow first index, retrying automatically about 30 seconds after a timeout. No concrete merge-blocking defect was identified; the error message still shows while indexing, which the PR describes as expected.
Pre-merge checks: 4
Check name
Status
Explanation
Title check
The title "fix(server): content search recovers after a slow first index" follows the conventional commit format and names the main change. The changeset keeps the finder alive on a scan timeout, retu…
Description check
The description follows the repository template. It has Problem, Change, Scope, and Verification sections, and each is filled in with specific detail. The Problem section gives reproduction steps and …
Linked Issues check
Check skipped because no linked issues were found for this pull request.
Out of Scope Changes check
Check skipped because no linked issues were found for this pull request.
Full details: Title check
Explanation
The title "fix(server): content search recovers after a slow first index" follows the conventional commit format and names the main change. The changeset keeps the finder alive on a scan timeout, returns WorkspaceSearchIndexScanTimedOut until warmup completes, removes the refresh timeout handler, and adds a client retry. The title matches these changes. It is 61 characters, which is concise.
Full details: Description check
Explanation
The description follows the repository template. It has Problem, Change, Scope, and Verification sections, and each is filled in with specific detail. The Problem section gives reproduction steps and the environment. The Change section explains each code path and why the choice was made. The Scope section links PR #11500 and states the bug-fix exception. The Verification section lists focused tests, manual checks on a 1.7 million file folder, real-app recording of timings, and environments that were not checked (macOS, packaged desktop app). It also includes the required agent attribution line. Minor gap: the template asks for a link to the issue that shows the bug, and the description does not link one. It instead cites a maintainer-approved exception, which the template allows when no issue is needed for an obvious bug, but that justification is not a formal maintainer request link.
Finishing Touches
Generate unit tests (beta)
Create a new PR
Autofix · Keep fixing CodeRabbit findings and required CI, and resolving merge conflicts
Included review availability: This review used your included allowance. Your plan provides up to 10 included reviews per hour; 9 remain after this review.
merged current github/main (dd3d4a4e4a20) without rebasing and pushed e295519b2af6e2c750774bda4365a622bda34bc3 to the existing contributor branch without force. resolved both conflicts, preserving main's async finder calls and query-length limit alongside this pr's timeout recovery and retry. adapted the existing scan hooks and service setup to main's async api; no new test files or feature changes.
blacksmith vp run check:changed github/main passed format, lint, knip, graphql, four affected package typechecks, 60 tests, and react compiler coverage. the three missing-service failures were reproduced first and passed after the setup adjustment. two independent reviewers approved this exact head with no remaining findings. the real development server started and completed orchestration recovery; browser recovery was not rerun on this merged head. the earlier browser evidence below applies to the original head only.
final head: github reports MERGEABLE and CLEAN; all checks completed without failures (conditional jobs skipped normally). the initial workflow approval gate cleared and CI passed, including build/typecheck, lint, all eight server shards, both web shards, and the remaining test jobs. no review-bot code findings required a change. both independent reviewers approve the final head. no merge was performed.
Verified in a real dev environment
verified unchanged head 40a4cce705d1ee0d4457b34a96b55ccef64489bb against github/main at fa2f4ff2a2bac5ac92e07749f6b83b0003d642a0 on this linux vm. ran one background dev server at a time, with separate app state, and drove the web client using repository playwright and /usr/bin/google-chrome.
created the project and threads through the app against a real linux source checkout with 97,362 tracked files. real codex gpt-6.1-sol turns read README on both revisions; a follow-up turn read COPYING on the pr. no mocks or demo data. the checkout indexed too quickly at unrestricted cpu, so both initial scans used the same server-only cgroup limit of 20% of one core (cpu.max=20000 100000), with the real 15-second timeout unchanged.
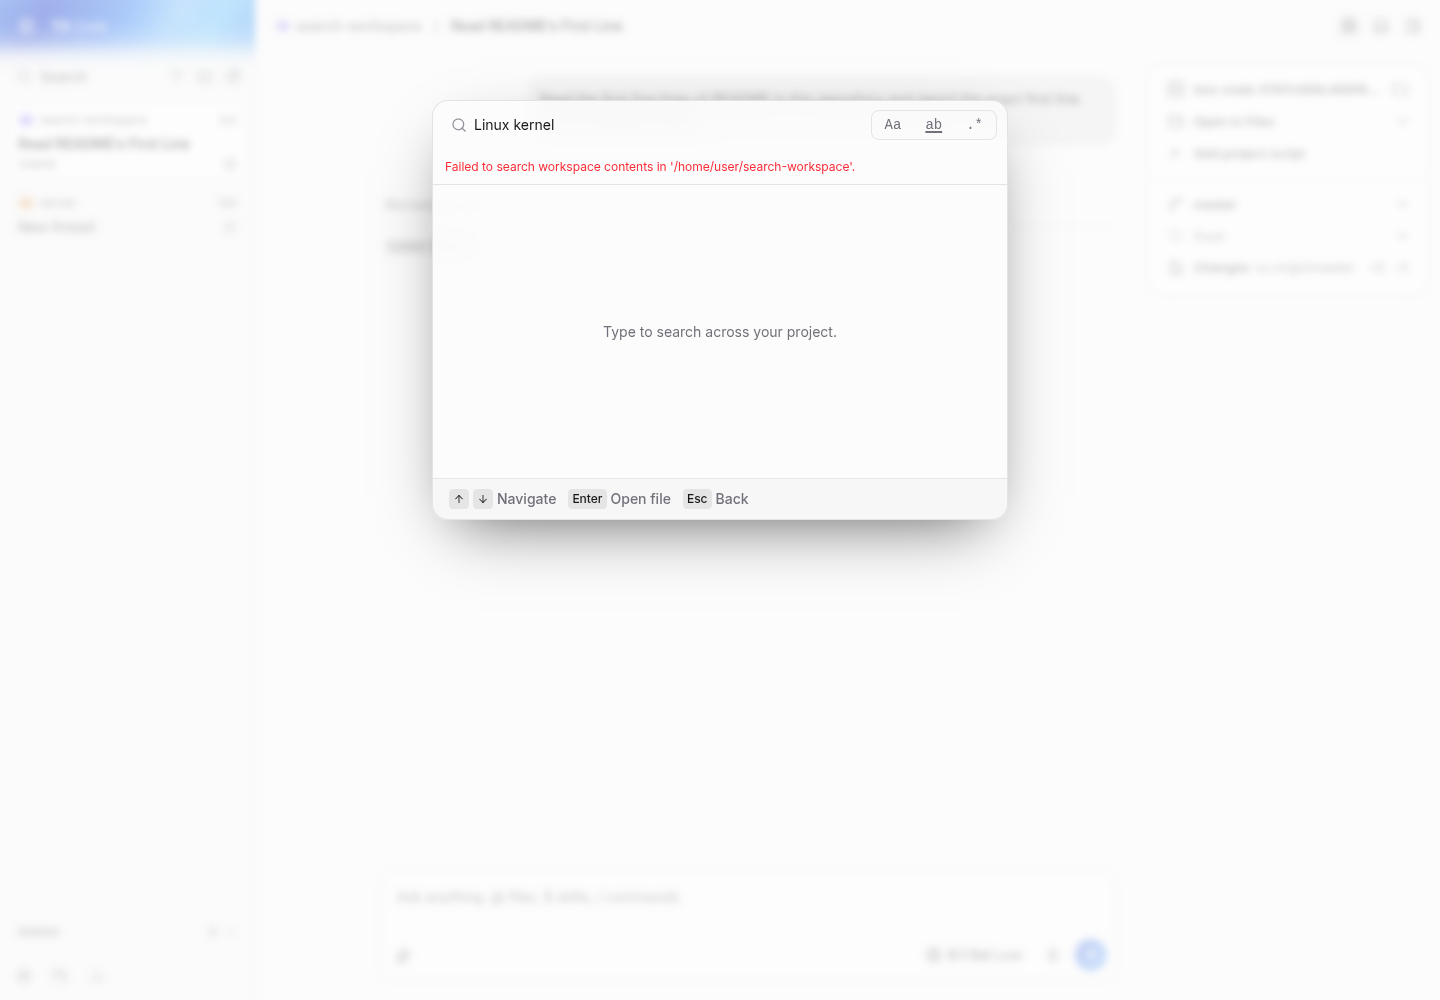
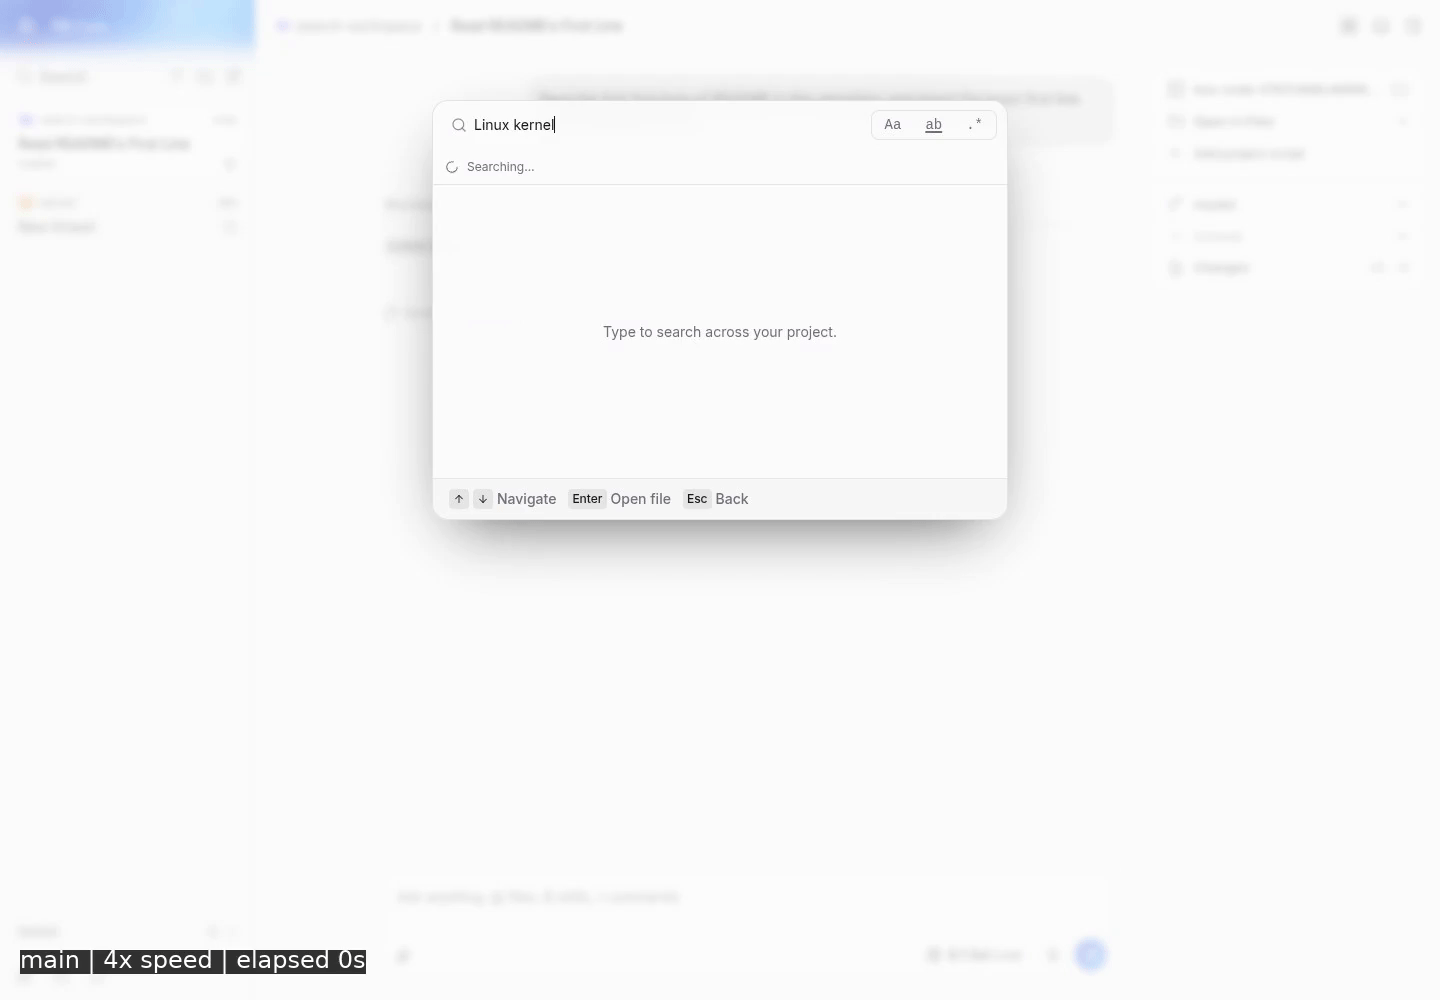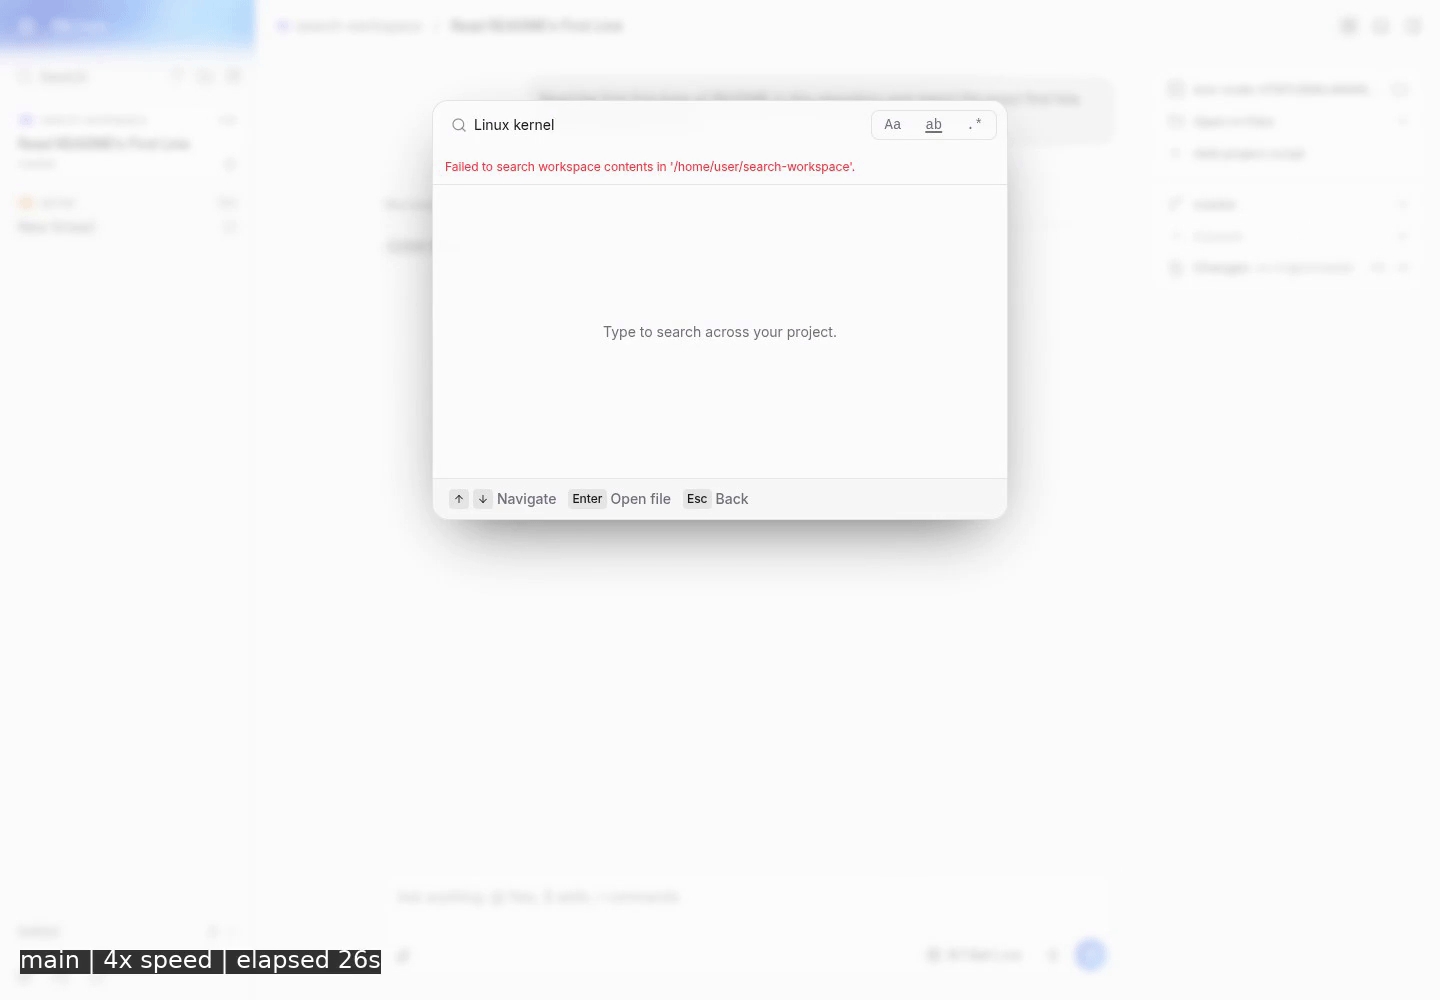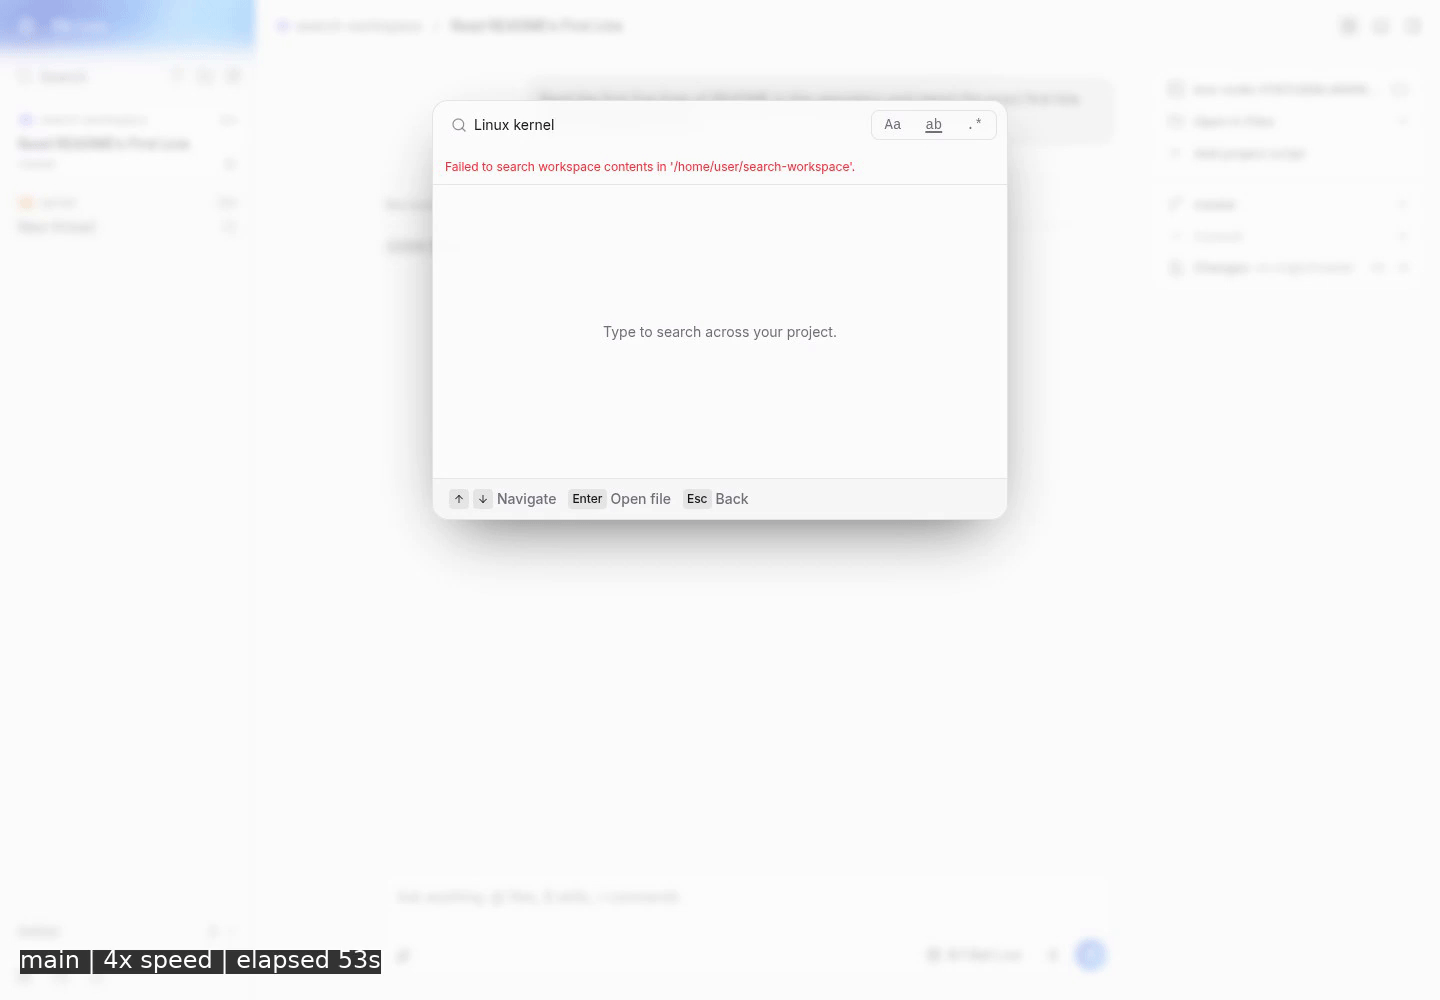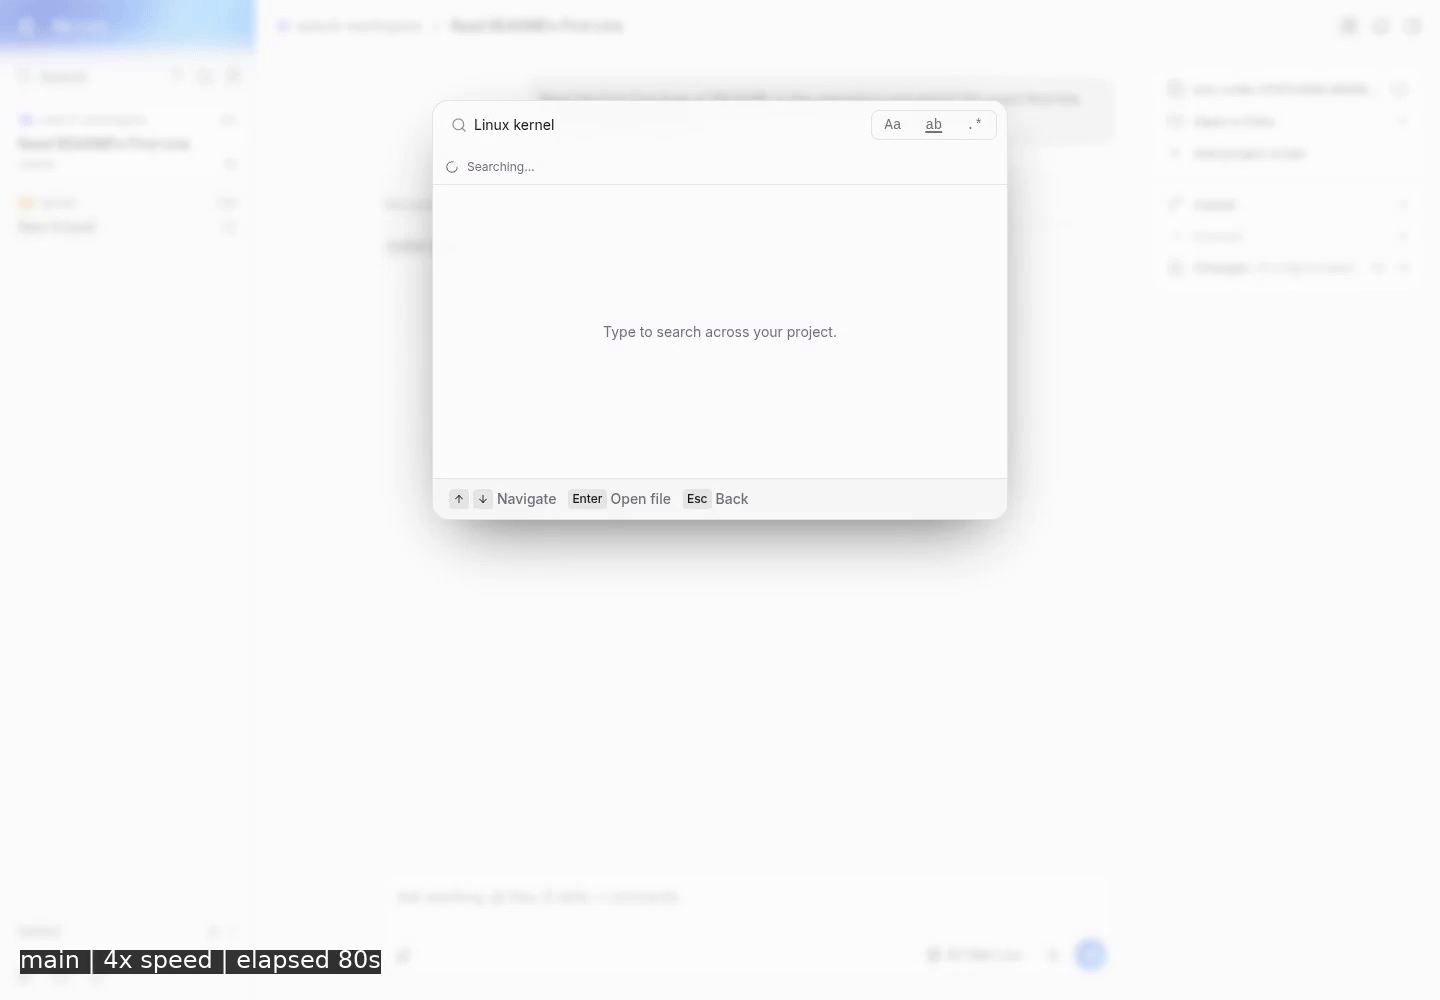
main: the first search failed at 21.9s. the error persisted; a different query at 61.6s received the cached timeout in 5ms.
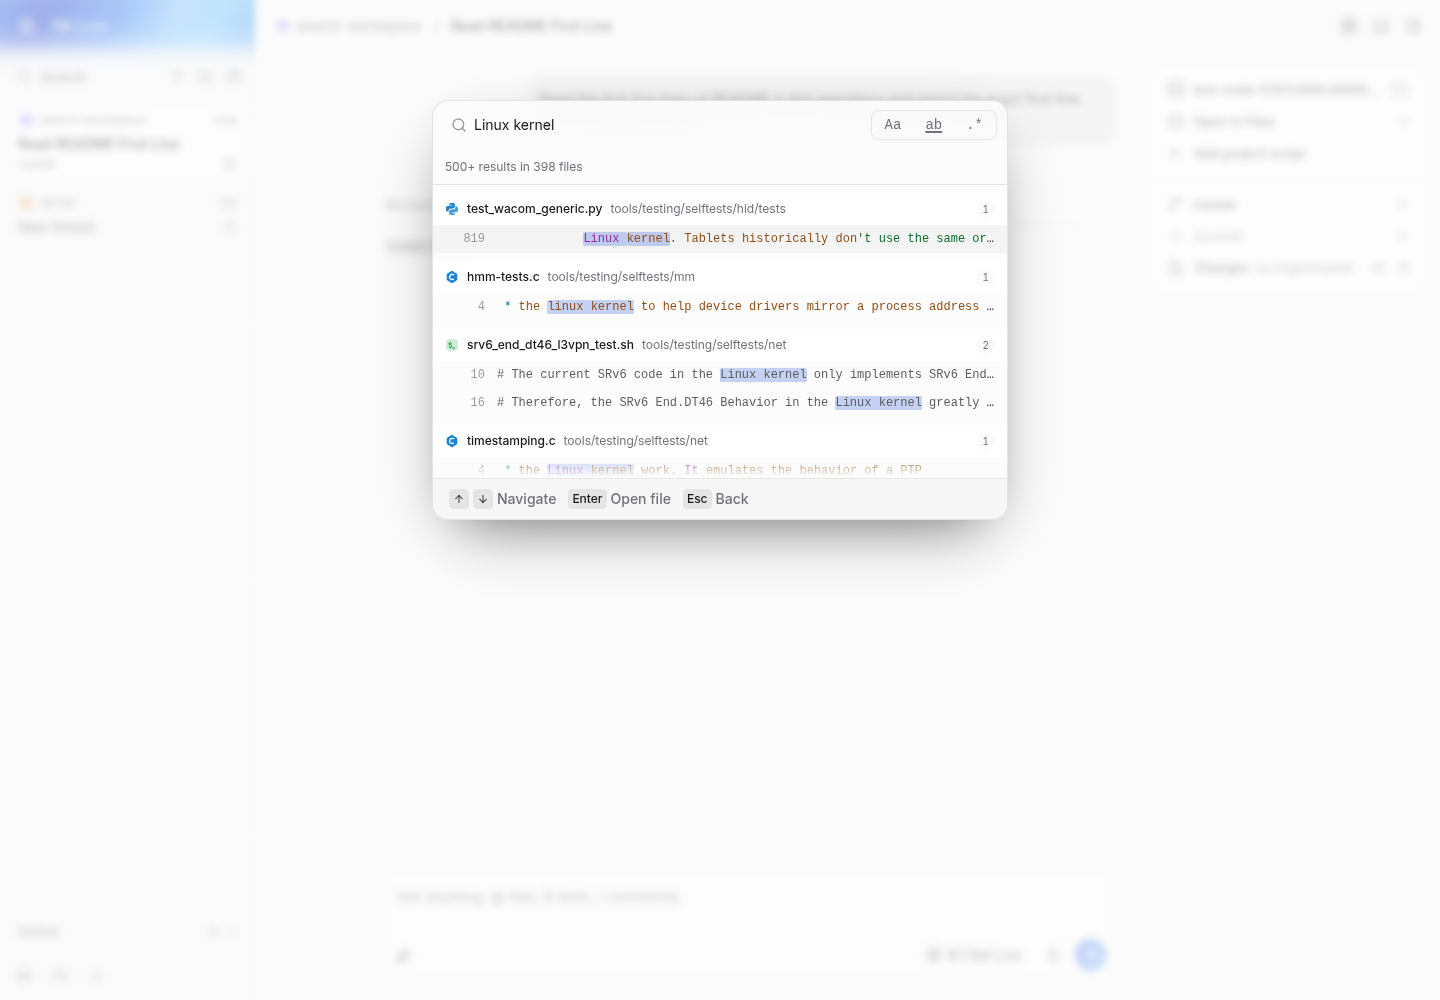
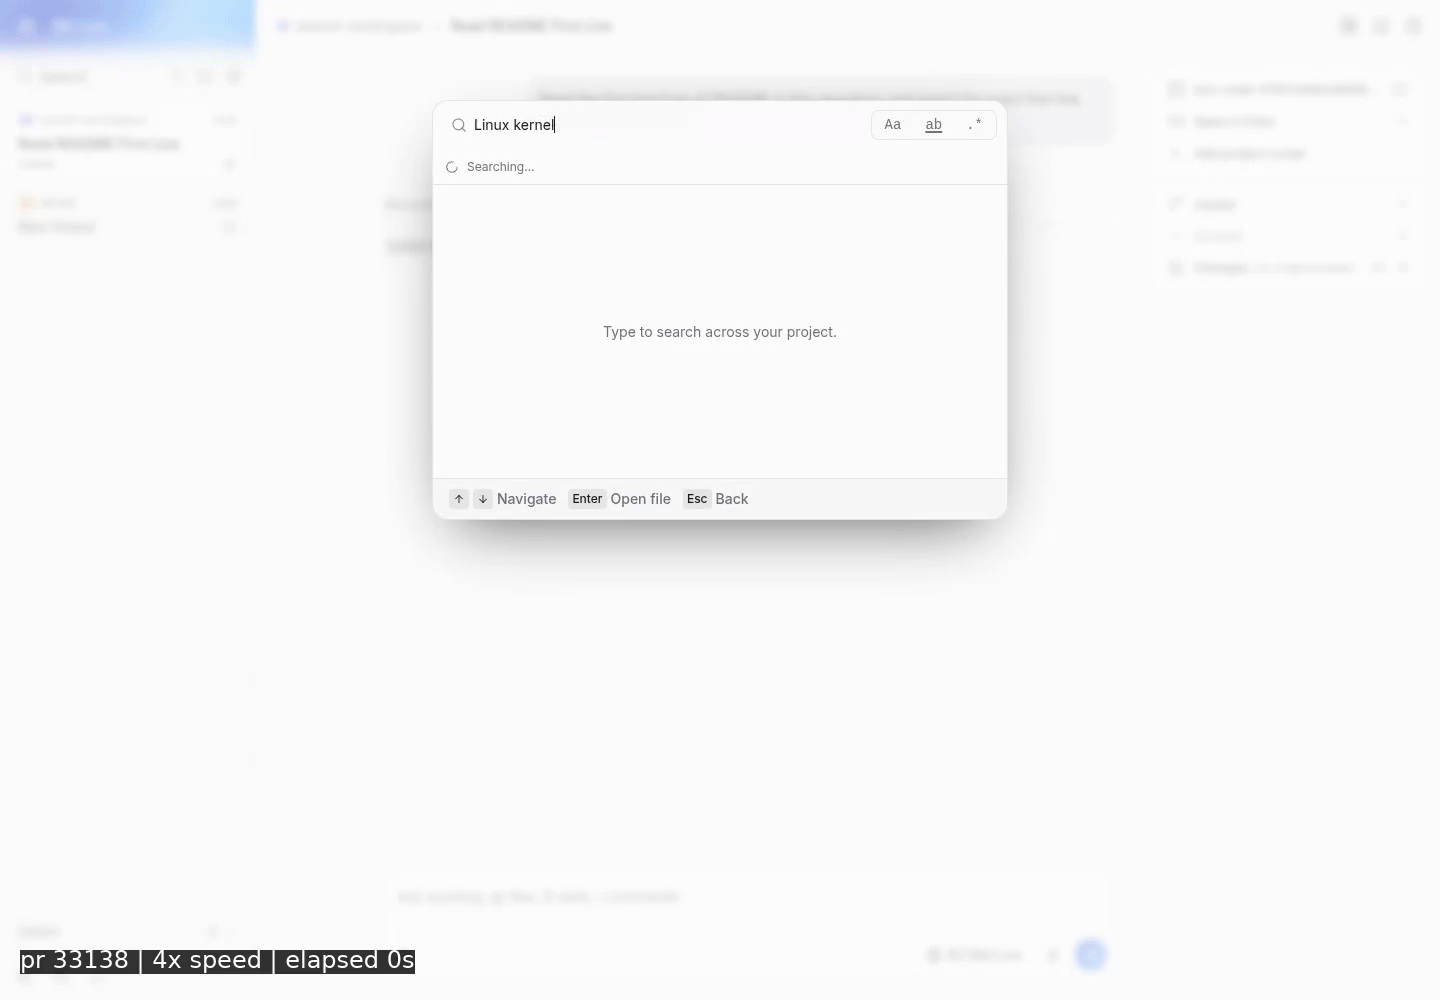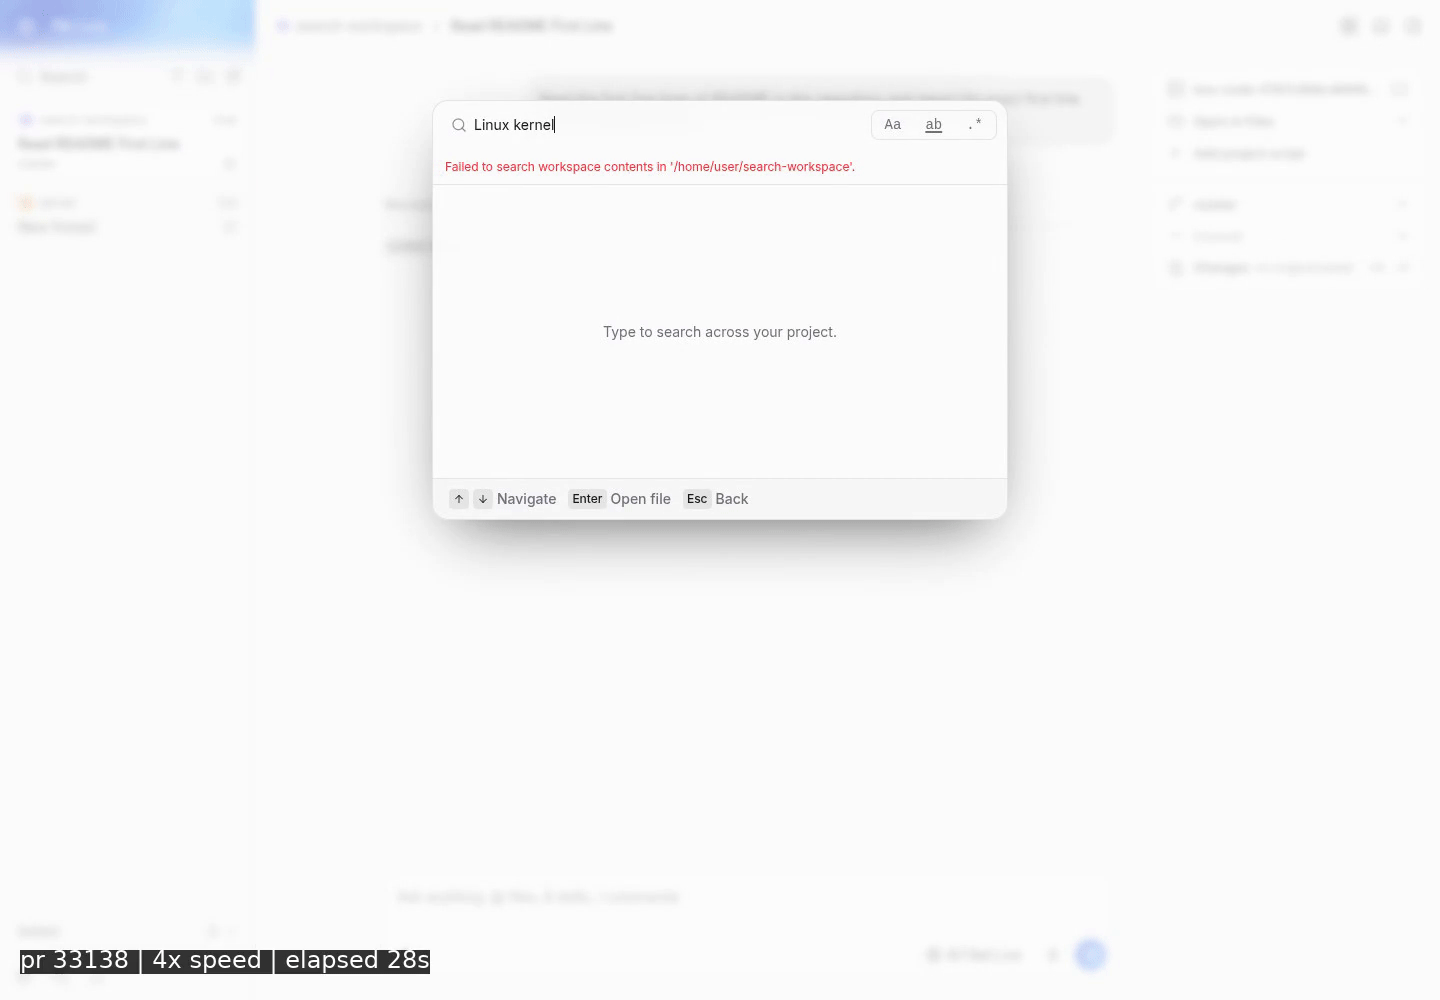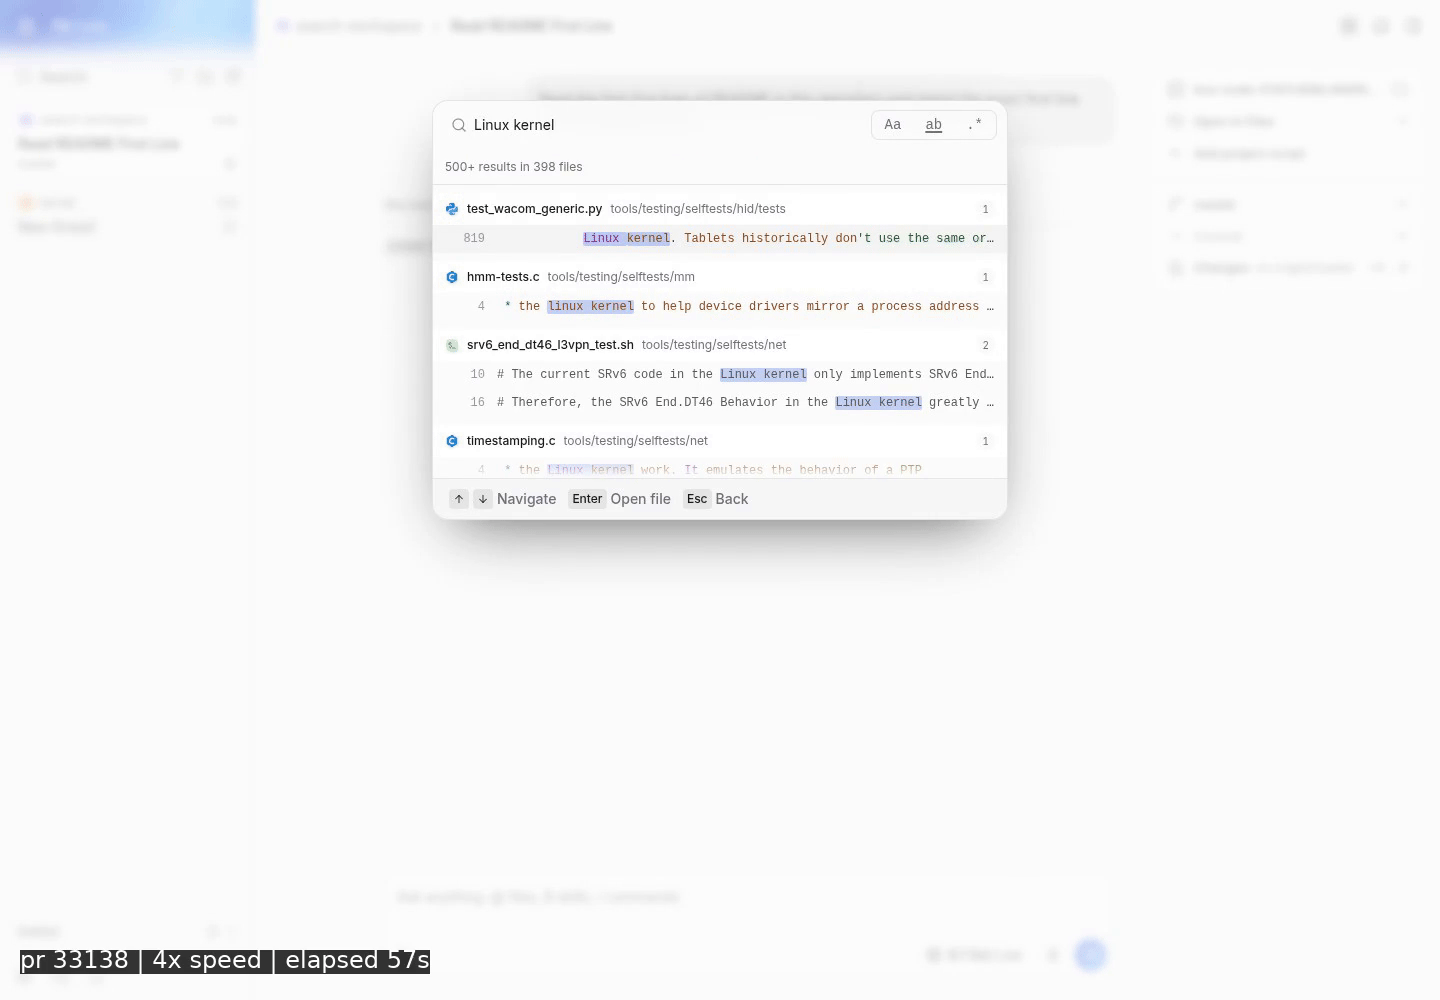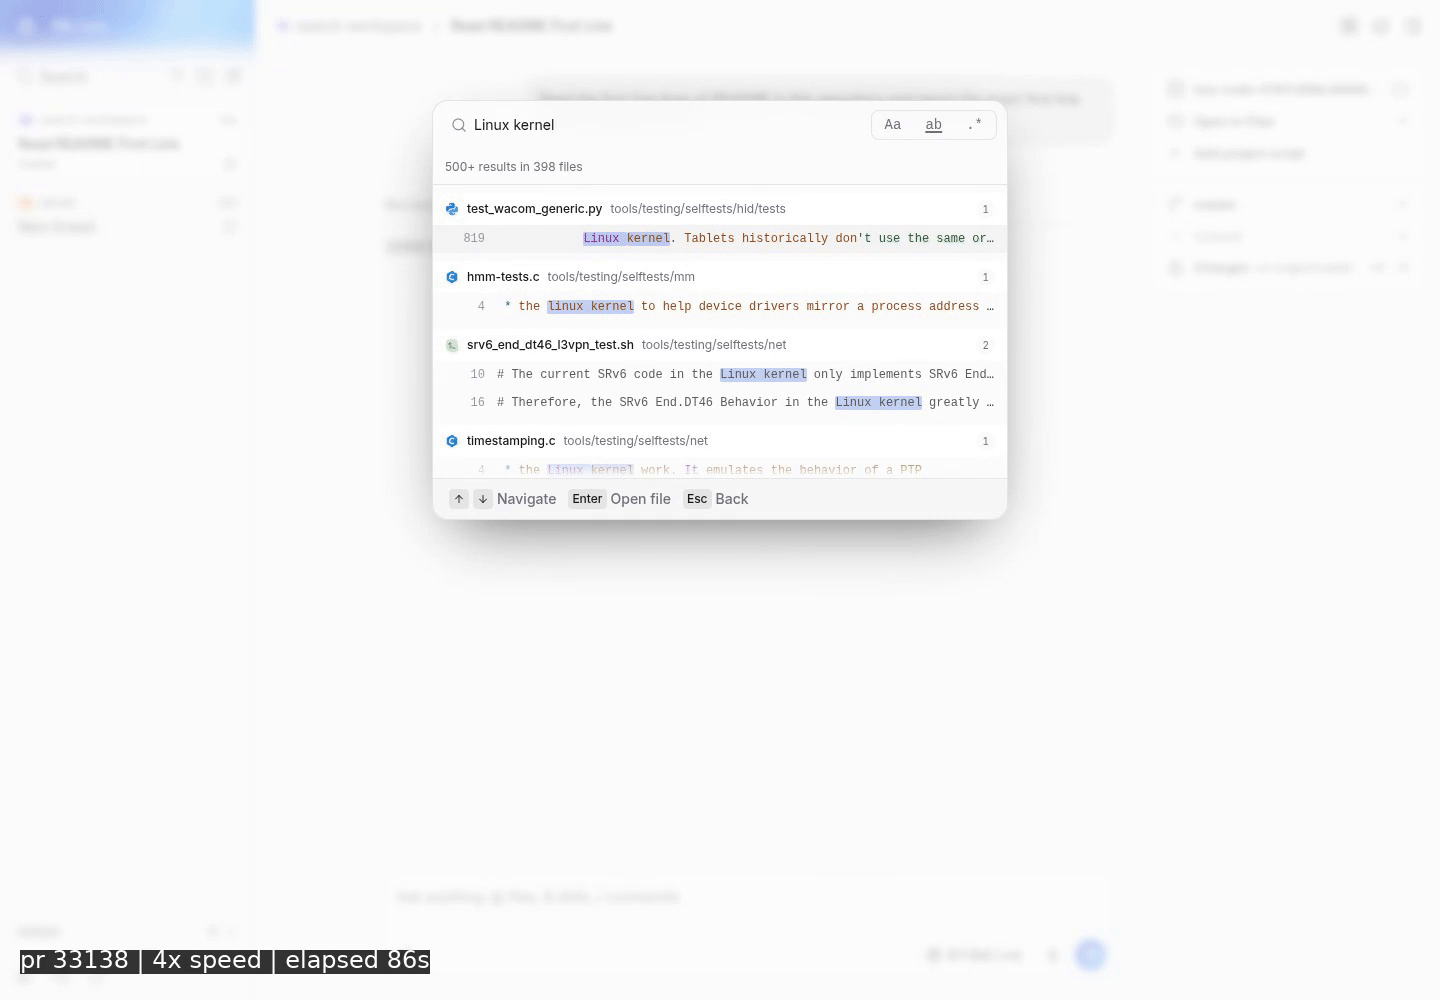
pr: typed Linux kernel once. timeout at 15.7s, automatic retry at 45.7s, results at 46.0s: 500+ matches in 398 files. exactly two requests through 86.9s, with results remaining visible.
nearby behavior: case-sensitive whole-word search returned 100 start_kernel matches without embedded secondary_start_kernel; regex ^Linux kernel$ returned README line 1; selecting the match opened that line. file-name search opened init/main.c. an absent term showed no results. content search still worked after the second codex turn and workspace refresh.
blacksmith: all 36 focused tests passed. vp run check:changed FETCH_HEAD^ passed format, lint, knip, graphql, affected typechecks, 38 tests and react compiler coverage. fetched the pr parent into the worker first because its initial snapshot lacked history. existing ci reported 31 successful checks.
before:
after, matching repository and query:
recordings run at 4x with elapsed time visible, exported as gifs for github:
packaged electron, native ios/android, macos/windows, remote relay/tunnel connections, and other providers were not exercised on this linux web setup. refresh while the first scan is still running and retry cancellation on dialog close were covered by the focused tests, not independently reproduced in the browser. the unrestricted-cpu run did not trigger the timeout, so the recovery comparison uses the disclosed cpu limit.
Windows numbers for this, from a repository of ordinary size rather than 1.7 million files.
On Windows with Defender at its defaults, the first content index of this repository (32,281 files) takes 3.6 minutes, because Defender scans each file on its first read; it is 7 s in WSL on the same machine. So the 15 s limit is passed by any repository over roughly 2,800 files, on first use, in every new clone or worktree, and again after each Defender definition update. Details and the measurements are in #37086.
I applied this PR's server and web changes (not the tests) on a62bc81 and ran the real app on a fresh clone, Windows backend, one search attempt about every 33 s:
Seed a project with 1,200,000 synthetic filler files and needle.txt containing uniqueNeedleWord. Open its thread, press Ctrl+Shift+F, and enter uniqueNeedleWord once. Capture after 20 seconds and after 166 seconds without editing. Change the query to uniqueNeedle and observe for another 52 seconds.
Environment on both sides: Linux web, Chromium 156, 1280×800, light theme, fresh synthetic state. Displayed paths are redacted; recordings preserve elapsed time at 5 fps.
Proven: the scenario fails on base and passes on head.
Base: finder creation failed after 15.7 seconds, no automatic retry occurred, and editing the query returned the cached timeout in 0.95 ms. Head: the initial wait also exceeded 15 seconds, but finder creation succeeded; an automatic retry returned needle.txt without creating another finder. The edited query also returned the match.
Main's #33138 keeps a slow content index alive and fails fast while it
warms; this branch already keeps it alive and answers through git grep
during warmup, so the branch's searchContents and make are kept.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
size:M30-99 changed lines (additions + deletions).vouch:unvouchedAuthor is not yet trusted in the VOUCHED list.
3 participants
Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.


 github-actions
Bot
added
vouch:unvouched







 juliusmarminge
added
the
takeover:in-progress


Problem
On a project whose first content index takes more than 15 seconds, content search fails and never recovers. At the timeout the index build fails, which destroys the finder and stops the scan, and the failed lookup stays cached. A refresh (after an agent run or a new file) drops that entry, and the next search starts a new scan from zero, which times out the same way. File-name search already tolerates this timeout; only content search does not.
To reproduce, open content search on a folder whose indexing outlasts 15 seconds. I used a real folder of 1.7 million files, which takes about 50 seconds.
Expected: an error while the first scan runs, then normal results once it finishes, with the same scan carried through.
Change
WorkspaceSearchIndex.makekeeps the finder on a scan timeout for both variants, as the paths index already did, so the scan runs to completion.searchContentsreturns the existingWorkspaceSearchIndexScanTimedOutinstead of partial results, for the reason given in fix(server): return partial workspace index on timeout #11500: an unscanned file would read as "No results found". The check isgetScanProgress().isWarmupCompleteand notisScanning(), becauseisScanning()goes false before the content index exists, and also when the file walk dies, which would turn a dead scan into an empty result.WorkspaceEntries.refreshloses its handler for that timeout, which can no longer happen.useProjectContentSearchasks again 30 seconds after a scan-timeout failure has come back. Without this, a word that failed during the scan keeps its cached error for as long as it stays in use. The retry runs only after that failure has settled, so it cannot restart a search in flight, and a running grep cannot be cancelled on the server. Any other failure is left alone.The client change is part of the same fix: the failure was cached in two places, and both have to let go of it.
Scope and approval
Submitted under the exception for a very small, focused fix of an obvious bug. Content search on a large project fails permanently, with no way to recover from the UI. The change extends timeout handling the paths index already has. It adds no setting and no workflow.
Verification
Built on 4013183. The six changed files are identical at 3fa57b9, where the real-app and Linux checks ran. Windows 11 and Ubuntu 24.04 (WSL2), Node 26.12.1.
Tests. Six new tests. On unmodified source five fail: content search still returns
WorkspaceSearchIndexScanTimedOutafter the scan ends, a refresh during the scan builds a second finder (finders: 2, expected 1), and the client never asks again after a scan timeout. The sixth guards that a real scan error still fails index creation, and passes both ways. With the fix, all three test files pass (36 of 36). The cases cover recovery with no refresh, concurrent searches, a refresh during the scan, a scan that ends with no content index, unreadable scan progress, and the client retry: none while a search is pending, one after the failure settles, cleared when the query changes or answers, none for other failures.vp run check:changedpasses: format, lint, knip, graphql, typecheck, tests beside the changes, React Compiler coverage.Real search service, real folder.
WorkspaceEntriesunder Node 26 with no mocks, on 1,692,328 files:Real app, web UI and server from source, same folder:
searchContents: two searches on the server, 30.0 seconds apart.searchContentsstarts once on the server and answers at 45.4 seconds, so a slow search is not restarted.apps/serversuite on Windows. 38 files fail with or without this change, with the same 193 failing test names and none new (199 failed, 1016 passed, 30 skipped, in both runs of those files). They look Windows-related, such as symlinks and systemd. None is undersrc/workspace. The full 479-file run was done before a last two-line server edit that removes an unreachable handler; after that edit, the 38 files, the two search test files andcheck:changedwere rerun.CI steps on Ubuntu 24.04 (WSL2), this patch on 3fa57b9. knip, generated GraphQL checks,
vp check, typecheck,build:desktop, the preload and built web boot checks all pass. Server suite: 479 files, 6,901 passed, 5 skipped. Web suite with Chromium: 531 files, 5,660 passed. The other 34 package tasks pass. No test failed.Not checked: macOS and the packaged desktop app. No screenshots, since nothing changes visually.
Behaviour to know about:
refreshon a timed-out content index now waits up to 15 seconds, as the paths index already does.Written by Claude Opus 5.5 in Claude Code. Reviewed by GPT-6.1 Sol.
🤖 Generated with Claude Code