You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
{{ message }}
Repository navigation
feat(voice): add a native streaming transcription toggle - #34380
Native streaming can fall behind while dictating on some machines, as reported in #32050. Web and desktop currently choose native streaming whenever the selected model supports it, with no way to use that same model after recording stops.
Change
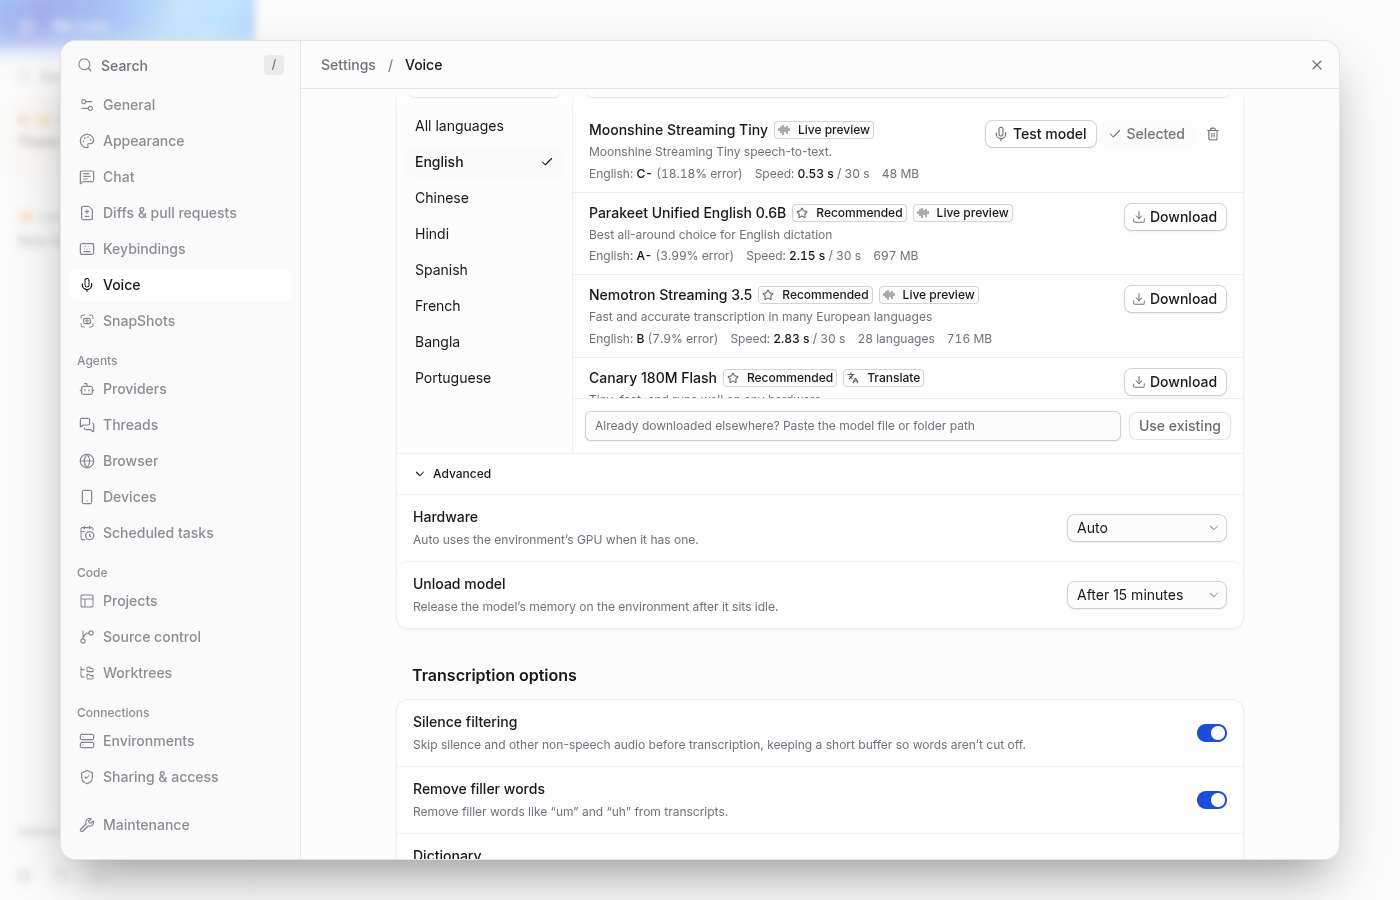
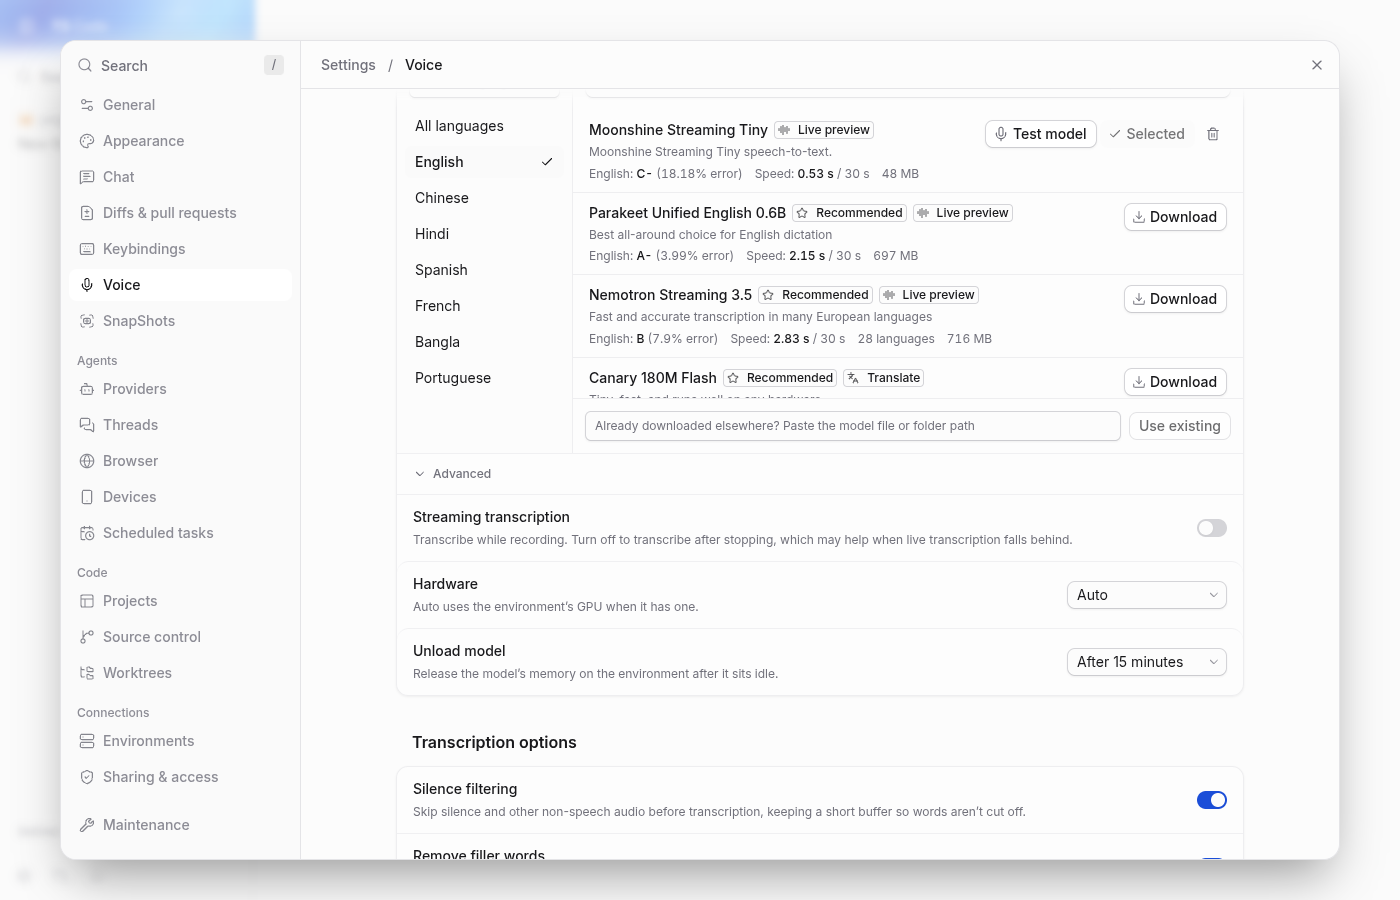
Add Streaming transcription under Settings → Voice → Advanced, enabled by default. Turning it off retains the recording locally until stop and sends it through the existing authorized batch path. The choice is captured for the recording, including retries. Availability follows the selected transcription destination and model; unsupported models disable the control without changing the saved device preference. Non-native chunked previews and cloud transcription keep their existing behavior.
The native worker now plans batch audio from the actual run mode, so a streaming-capable model receives the existing bounded chunks, silence handling, and batch error recovery. The shared web voice controller covers composer dictation, shortcuts, text fields, comments/annotations, and model tests. Desktop uses that same web implementation; no mobile UI is added.
Scope and approval
This is focused configuration of the existing native-streaming and batch transcription capability. It keeps today's default and the selected model. Related to #32050 as an opt-out/workaround, without claiming to resolve the entire performance issue. No engine update, GPU Auto policy, feed-interval tuning, pre-roll change, or benchmark/recommendation system is included.
Verification
vp run check:changed: format, lint, knip, GraphQL validation, typechecks of 37 affected packages including mobile/desktop consumers, and 161 focused tests passed.
A native-worker regression test first failed on the original implementation with Model input limit exceeded, then passed with bounded offline chunks and no streaming session.
Browser behavior tests cover default-on settings, actual batch PCM retention and authenticated destination requests, captured preferences during preparation and retry, cancellation, native versus buffered capabilities, translation locale, and saved preferences across destination capability changes.
Isolated Windows client: Moonshine Streaming Tiny Q8_0 on CPU with the first 8 seconds of the public transcribe.cpp/samples/whole-earth.wav sample injected as microphone input. ON opened one native session and showed evolving text while recording. OFF reached the real POST /api/voice/transcribe batch endpoint and returned HTTP 200. A direct production-worker run of the same sample also returned the expected sentence with silence filtering enabled.
Before
After
Implemented with GPT-6.1 Sol through the Codex harness.
Macroscope's review found this PR approvable — Adds a device-local option to transcribe after recording stops while preserving streaming by default. It reuses the existing consent-checked batch path and selected model, with limited, reversible impact.
You can add or adjust custom eligibility rules. Learn more.
No actionable comments were generated in the recent review.
Walkthrough
A saved client setting now controls native streaming transcription. The browser voice-input flow uses the setting when choosing between native streaming and buffered transcription. Server audio planning and silence-model selection use the effective mode for each operation.
Changes: Streaming transcription preference
Layer / File(s)
Summary
Preference contract and settings control packages/contracts/src/settings.ts, packages/contracts/src/settings.test.ts, apps/web/src/components/settings/VoiceSettingsPanel.tsx, apps/web/src/components/settings/VoiceSettingsPanel.browser.test.tsx, apps/web/src/components/settings/settingsSearch.ts, docs/user/voice-input.md
Client settings add speechStreaming, which defaults to true and accepts patches. Voice settings expose the preference for supported models, add search support, and document how to disable streaming. Browser tests cover persistence and model support.
The browser voice-input platform reads the latest setting and selects native streaming or buffered transcription based on the setting and environment support. Tests cover mode selection, retry, and cancellation.
Server processing by operation mode apps/server/src/speech/native.ts, apps/server/src/speech/SpeechService.ts, apps/server/src/speech/native.test.ts
Native audio creation and VAD eligibility use the operation’s effective streaming mode. Silence-model selection receives the operation mode. A test checks bounded offline transcription chunks when the model supports streaming.
sequenceDiagram
  participant ClientSettings
  participant useEnvironmentSpeechInput
  participant createBrowserVoiceInputPlatform
  participant TranscriptionMode
  ClientSettings->>useEnvironmentSpeechInput: Store speechStreaming preference
  useEnvironmentSpeechInput->>createBrowserVoiceInputPlatform: Provide the current setting
  createBrowserVoiceInputPlatform->>TranscriptionMode: Select native streaming or buffered transcription
Loading
Suggested reviewers:juliusmarminge, t3dotgg
Merge Risk: Minimal · up to bc19f
This adds an opt-out for streaming transcription that defaults to the current behavior. No concrete merge-blocking risk was found in the supplied changes.
Pre-merge checks: 4
Check name
Status
Explanation
Title check
The title "feat(voice): add a native streaming transcription toggle" matches the main change: a Streaming transcription setting under Settings → Voice → Advanced that switches between native streaming…
Description check
The description follows the repository template in substance. It has Problem, Change, Scope and approval, and Verification sections, and it links the related issue #32050. The Verification section is …
Linked Issues check
Check skipped because no linked issues were found for this pull request.
Out of Scope Changes check
Check skipped because no linked issues were found for this pull request.
Full details: Title check
Explanation
The title "feat(voice): add a native streaming transcription toggle" matches the main change: a Streaming transcription setting under Settings → Voice → Advanced that switches between native streaming and buffered batch transcription. The changeset adds the setting in the contracts, web settings UI, search entries, browser voice input, and the native worker batch planning. The title is specific and follows the conventional commit format.
Full details: Description check
Explanation
The description follows the repository template in substance. It has Problem, Change, Scope and approval, and Verification sections, and it links the related issue #32050. The Verification section is detailed: it lists the commands run, a regression test that failed before and passed after the change, browser test coverage, and a manual Windows run with observed results. It also states what was not checked, such as mobile and other streaming models. The template's Scope section asks for a bug-fix link, and the author frames this as an opt-out workaround related to #32050. The Scope section does not clearly meet the template's bug-fix requirement, but the description is mostly complete. Before and after screenshots are included, as the template requires for UI changes.
Finishing Touches
Generate unit tests (beta)
Create a new PR
Autofix · Keep fixing CodeRabbit findings and required CI, and resolving merge conflicts
Included review availability: This review used your included allowance. Your plan provides up to 10 included reviews per hour; 9 remain after this review.
Head ca98bdec7a, compared with main at 0629735d37. I used vp run dev on Linux with a seeded dev database and added a demo-repo git project through Add project → Local folder. I selected this environment under Transcribe with and downloaded Moonshine Streaming Tiny from Voice settings. I drove headless Chrome with Playwright. Its fake microphone played the public whole-earth.wav sample, and I dictated into the new-thread composer with Start voice input and Finish voice input.
Before (main): Advanced settings have no streaming option. Dictating with this model always opens /ws/voice and shows live preview text while recording.
After (PR):Streaming transcription appears under Advanced. It is on by default.
ON (default):/ws/voice opens, live text appears from about 3 s into the recording, and the final text lands in the composer.
OFF: no /ws/voice socket opens and no preview text appears during a 9 s recording. On Finish voice input, one POST /api/voice/transcribe returns 200 about 3 s later. The composer then gets "It was an amazing publication called The Whole Earth Catalog, which was one of the Bibles of my generation. It was created by".
OFF, 45 s recording: one POST /api/voice/transcribe returns 200 with the full ~45 s passage. There was no Model input limit exceeded error, so the batch path chunks the streaming model correctly.
Persistence: OFF stays saved after a fresh browser launch. Turning it back ON restores /ws/voice with live text.
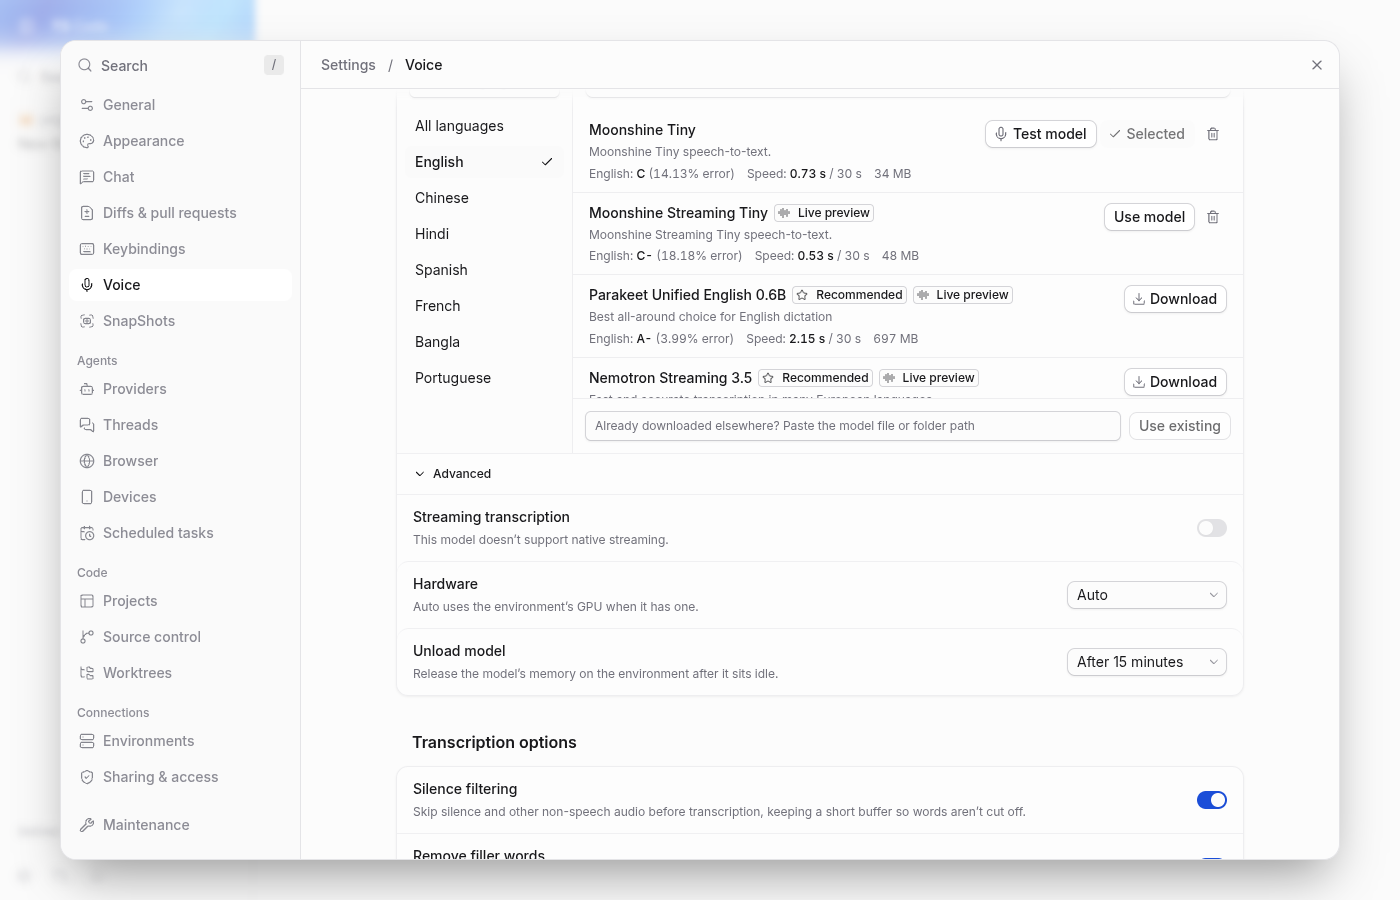
Unsupported model: after selecting Moonshine Tiny, which does not stream, the switch is disabled and says "This model doesn't support native streaming." The saved OFF value is kept. Dictating with that model still uses its existing chunked preview over /ws/voice and transcribes correctly. Switching back to Moonshine Streaming Tiny shows the switch enabled and still OFF.
Settings search: searching "streaming" lists Streaming transcription · Voice and opens Voice settings. Clicking the result opens Voice at the top without scrolling to the row. The existing Transcription hardware and model unloading result does the same, so this is not new in this PR.
Streaming OFF: no live text while recording, and the transcript appears after Finish:
This PR changes the test suite by +3 test cases (browser +2, unit 0, server +1).
New browser test files: apps/web/src/speech/browserVoiceInput.browser.test.ts.
Each browser test file costs CI seconds of module loading before its first test runs; a unit test costs milliseconds.
Keep tests that would fail for a real reason, and test logic below the UI where it can be. See Testing.
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
size:M30-99 changed lines (additions + deletions).vouch:trustedAuthor is trusted by repo permissions or the VOUCHED list.
2 participants
Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.


 github-actions
Bot
added
vouch:trusted







Problem
Native streaming can fall behind while dictating on some machines, as reported in #32050. Web and desktop currently choose native streaming whenever the selected model supports it, with no way to use that same model after recording stops.
Change
Add Streaming transcription under Settings → Voice → Advanced, enabled by default. Turning it off retains the recording locally until stop and sends it through the existing authorized batch path. The choice is captured for the recording, including retries. Availability follows the selected transcription destination and model; unsupported models disable the control without changing the saved device preference. Non-native chunked previews and cloud transcription keep their existing behavior.
The native worker now plans batch audio from the actual run mode, so a streaming-capable model receives the existing bounded chunks, silence handling, and batch error recovery. The shared web voice controller covers composer dictation, shortcuts, text fields, comments/annotations, and model tests. Desktop uses that same web implementation; no mobile UI is added.
Scope and approval
This is focused configuration of the existing native-streaming and batch transcription capability. It keeps today's default and the selected model. Related to #32050 as an opt-out/workaround, without claiming to resolve the entire performance issue. No engine update, GPU Auto policy, feed-interval tuning, pre-roll change, or benchmark/recommendation system is included.
Verification
vp run check:changed: format, lint, knip, GraphQL validation, typechecks of 37 affected packages including mobile/desktop consumers, and 161 focused tests passed.Model input limit exceeded, then passed with bounded offline chunks and no streaming session.transcribe.cpp/samples/whole-earth.wavsample injected as microphone input. ON opened one native session and showed evolving text while recording. OFF reached the realPOST /api/voice/transcribebatch endpoint and returned HTTP 200. A direct production-worker run of the same sample also returned the expected sentence with silence filtering enabled.Before
After
Implemented with GPT-6.1 Sol through the Codex harness.