Repository navigation
Inference Backends
Documentation home · Quickstart · Lifecycle
On this page
GPTQModel separates the quantization method, the checkpoint format, and the inference backend. A method describes how the weights were quantized; a format describes the tensors stored on disk; a backend selects the implementation that consumes those tensors. Choosing a different backend does not, by itself, turn an AWQ checkpoint into GPTQ or change its quantization quality.
This reference describes the source at commit c1976918cfe3703fbcf6d1ce2440a82b26394375. Hardware gates below are implementation requirements, not general claims about what an architecture could theoretically execute. In particular, Machete is Hopper-only, Swordfish checks specific Blackwell targets, and W4A NVFP4 has its own different capability floor.
Use BACKEND.AUTO for normal local loading unless a particular kernel is required. AUTO selects the first compatible kernel in a declaration-derived ordering. It does not benchmark the model or guarantee the fastest backend for every batch size, prompt length, or device.
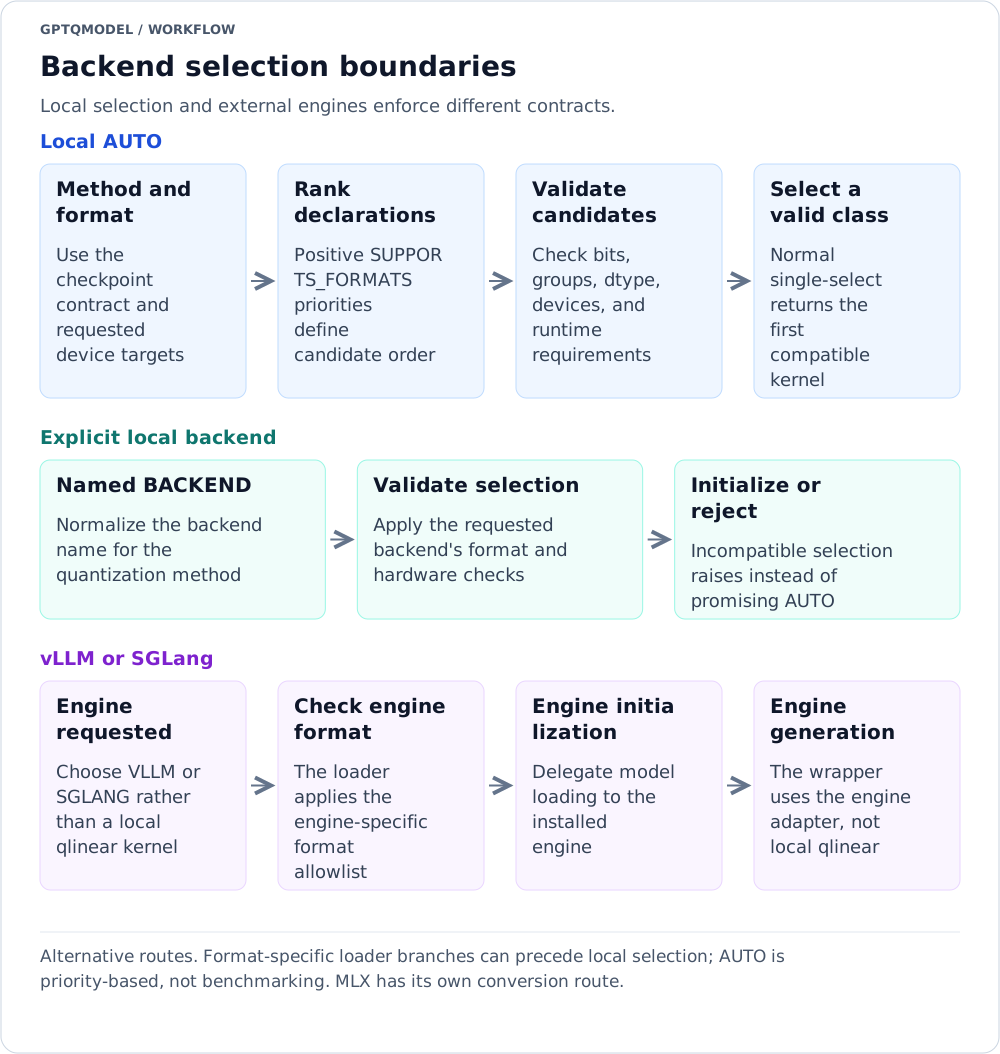
Reading the diagram: Alternative routes. Format-specific loader branches can precede local selection; AUTO is priority-based, not benchmarking. MLX has its own conversion route.
Text version of the workflow
- Local AUTO: Method and format → Rank declarations → Validate candidates → Select a valid class.
- Explicit local backend: Named BACKEND → Validate selection → Initialize or reject.
- vLLM or SGLang: Engine requested → Check engine format → Engine initialization → Engine generation.
| Concept | Source representation | Meaning |
|---|---|---|
| Quantization method | METHOD |
GPTQ, AWQ, QQQ, and other method families used to interpret quantization configuration. |
| Checkpoint format | FORMAT |
The serialization contract: for example GPTQ, GPTQ_V2, GPTQ_P, GEMM, MARLIN, GGUF, or EXL3. |
| Backend |
BACKEND, in gptqmodel/utils/backend.py
|
A local qlinear implementation or a model-level engine/conversion path. |
| Kernel declaration |
SUPPORTS_BACKENDS, SUPPORTS_METHODS, SUPPORTS_FORMATS
|
Connects a class to supported method/format/backend combinations; format values also carry AUTO priorities. |
| Runtime packing | Kernel post_init(), repack_from_gptq(), or repack_from_awq()
|
Converts loaded packed tensors into a kernel's private execution layout where required. |
| Profile |
PROFILE.AUTO = "auto", FAST = "fast", LOW_MEMORY = "low_memory"
|
A separate loading/runtime strategy selector, not a checkpoint format or backend name. |
Portable device declarations are still subject to operator and dtype availability. DEVICE.ALL means the class declares a general implementation; it is not evidence that every PyTorch operation used by that class is implemented on every installed accelerator runtime.
In particular, native AWQ and QQQ declarations that mention ROCm are not proof of CUDA/PTX kernel portability. Check the method-specific AWQ and QQQ runtime caveats before choosing a native backend.
from gptqmodel import BACKEND, GPTQModel

# Replace with a compatible, already-quantized checkpoint.
model = GPTQModel.load("/models/my-gptq-checkpoint", backend=BACKEND.AUTO)

# Force the portable GPTQ implementation when diagnosing a native-kernel issue.
reference_model = GPTQModel.load(
    "/models/my-gptq-checkpoint",
    backend=BACKEND.GPTQ_TORCH,
    device="cuda:0",
)
The model-level loading signature is:
def load(
        cls,
        model_id_or_path: Optional[str],
        quantize_config: Optional[QuantizeConfig | Dict] = None,
        device_map: Optional[Union[str, Dict[str, Union[str, int]]]] = None,
        device: Optional[Union[str, torch.device]] = None,
        backend: Union[str, BACKEND] = BACKEND.AUTO,
        profile: Union[str, int, PROFILE] = PROFILE.AUTO,
        trust_remote_code: bool = False,
        allow_remote_adapter: bool = False,
        adapter_revision: Optional[str] = None,
        adapter_sha256: Optional[str] = None,
        **kwargs,
):
    ...
String names can be normalized by normalize_backend. Prefer method-specific enum members in new code: GPTQ_TORCH or AWQ_TORCH is less ambiguous than the legacy TORCH spelling. In generic local qlinear selection, explicit selection is a requirement, not a hint: a failed hardware, format, dtype, or dependency check raises an error instead of silently choosing a different backend. Model-level loader branches can take a different path before this selector runs; the native Q1_0 GGUF FAST profile described below is one such exception.
For an AWQ GEMM checkpoint, the portable alternative is BACKEND.AWQ_TORCH, not GPTQ_TORCH. For GGUF, EXL3, FP8, VPTQ, QQQ, or bitsandbytes, use the matching family in the tables below. See Loading and Inference for generation and Checkpoint Formats and Compatibility for serialization.
The following two tables together include every enum member. Values are exact strings from backend.py. Format numbers shown beside local classes are their declared AUTO priorities, not bit widths or version numbers. A priority of zero means explicit selection remains possible but that format/backend combination does not participate in generic AUTO selection. Device entries describe declarations; additional runtime gates are documented afterward.
| Member | String value | Dispatch / declared checkpoint support and device families |
|---|---|---|
AUTO |
auto |
Local candidate selection in descending declared format priority; then validation. |
AUTO_TRAINABLE |
auto_trainable |
AUTO plus the trainable validation requirement. |
GPTQ_TORCH_FUSED |
gptq_torch_fused |
TorchFusedLinear: GPTQ: 50, GPTQ_V2: 50; CPU, XPU
|
GPTQ_TORCH_INT8 |
gptq_torch_int8 |
TorchInt8Linear: GPTQ: 0, GPTQ_V2: 0; CPU
|
GPTQ_TORCH |
gptq_torch |
TorchLinear: GPTQ: 20, GPTQ_V2: 20, GPTQ_P: 20; ALL. TorchQuantEmbeddings shares these declarations but is role-specific and excluded from general backend selection. |
GPTQ_TRITON |
gptq_triton |
TritonV2Linear: GPTQ: 40, GPTQ_V2: 40; CUDA
|
BITSANDBYTES |
bitsandbytes |
BitsAndBytesLinear: BITSANDBYTES: 40; CPU, CUDA
|
GPTQ_EXLLAMA_V2 |
gptq_exllama_v2 |
ExllamaV2Linear: GPTQ: 80, GPTQ_V2: 80; CUDA
|
GPTQ_MACHETE |
gptq_machete |
MacheteLinear: GPTQ: 100; CUDA
|
GPTQ_SWORDFISH |
gptq_swordfish |
SwordfishLinear: GPTQ: 101; CUDA
|
GPTQ_MARLIN |
gptq_marlin |
MarlinLinear: GPTQ: 90, GPTQ_V2: 90, MARLIN: 90; CUDA
|
GPTQ_W4AFP8 |
gptq_w4afp8 |
W4AFP8Linear: GPTQ: 0, GPTQ_V2: 0; CUDA
|
GPTQ_W4A_NVFP4 |
gptq_w4a_nvfp4 |
W4ANVFP4Linear: GPTQ: 0, GPTQ_V2: 0; CUDA
|
GPTQ_BITBLAS |
gptq_bitblas |
BitblasLinear: BITBLAS: 30, GPTQ: 30, GPTQ_V2: 30; CUDA
|
GPTQ_TORCH_ATEN |
gptq_torch_aten |
TorchAtenLinear: GPTQ: 110, GPTQ_V2: 110; CPU
|
GPTQ_TORCH_CPU_AVX512 |
gptq_torch_cpu_avx512 |
TorchCpuAvx512Linear: GPTQ: 120, GPTQ_V2: 120; CPU
|
QQQ |
qqq |
QQQLinear: QQQ: 100; CUDA, ROCM
|
QQQ_TORCH |
qqq_torch |
QQQTorchLinear: QQQ: 90; ALL
|
AWQ_GEMM |
awq_gemm |
AwqGEMMLinear: GEMM: 60; CUDA
|
AWQ_GEMM_TRITON |
awq_gemm_triton |
AwqGEMMTritonLinear: GEMM: 50; CUDA, ROCM
|
AWQ_GEMV |
awq_gemv |
AwqGEMVLinear: GEMV: 40; CUDA, ROCM
|
AWQ_GEMV_FAST |
awq_gemv_fast |
AwqGEMVFastLinear: GEMV_FAST: 30; CUDA, ROCM; LLMAwqLinear: LLM_AWQ: 100; CUDA, ROCM
|
AWQ_TORCH_INT8 |
awq_torch_int8 |
TorchInt8AwqLinear: GEMM: 0; CPU
|
AWQ_TORCH_FUSED |
awq_torch_fused |
TorchFusedAwqLinear: GEMM: 20; CPU, XPU
|
AWQ_TORCH_ATEN |
awq_torch_aten |
TorchAtenAwqLinear: GEMM: 110; CPU
|
AWQ_TORCH_CPU_AVX512 |
awq_torch_cpu_avx512 |
TorchCpuAvx512AwqLinear: GEMM: 120; CPU
|
AWQ_TORCH |
awq_torch |
AwqTorchLinear: GEMM: 10; ALL
|
AWQ_BITBLAS |
awq_bitblas |
AWQBitBlasKernel: GEMM: 0, BITBLAS: 30; CUDA
|
AWQ_MACHETE |
awq_machete |
AwqMacheteLinear: GEMM: 100, MARLIN: 100; CUDA
|
AWQ_MARLIN |
awq_marlin |
AwqMarlinLinear: GEMM: 90, MARLIN: 90; CUDA
|
AWQ_SWORDFISH |
awq_swordfish |
AwqSwordfishLinear: GEMM: 101; CUDA
|
AWQ_EXLLAMA_V2 |
awq_exllama_v2 |
AwqExllamaV2Linear: GEMM: 80; CUDA
|
PAROQUANT_CUDA |
paroquant_cuda |
ParoLinear: PAROQUANT: 55; ALL
|
PAROQUANT_TRITON |
paroquant_triton |
ParoQuantTritonLinear: PAROQUANT: 0; CUDA
|
FP8_TORCH |
fp8_torch |
TorchFP8Linear: FP8: 15; CPU, CUDA, ROCM, XPU, MPS
|
VPTQ_TORCH |
vptq_torch |
VPTQLinear: VPTQ: 100; ALL
|
VPTQ_CUDA |
vptq_cuda |
VPTQCudaLinear: VPTQ: 100; CUDA
|
GGUF_TORCH |
gguf_torch |
GGUFTorchLinear: GGUF: 15; ALL
|
GGUF_TRITON |
gguf_triton |
GGUFTritonKernel: GGUF: 45; CUDA
|
GGUF_CPP_CPU |
gguf_cpp_cpu |
GGUFCppKernel: GGUF: 25; CPU
|
GGUF_CPP_CUDA |
gguf_cpp_cuda |
GGUFCudaKernel: GGUF: 35; CUDA
|
EXL3_EXLLAMA_V3 |
exl3_exllama_v3 |
EXL3 loader branch; ExllamaV3Linear; CUDA/HIP. |
EXL3_TORCH |
exl3_torch |
EXL3 loader branch; ExllamaV3TorchLinear; portable Torch implementation. |
VLLM |
vllm |
External vLLM loader, not a local qlinear class. |
SGLANG |
sglang |
External SGLang loader, not a local qlinear class. |
MLX |
mlx |
Explicit MLX conversion path; see the holder table in Kernel Backends Reference. |
These are distinct enum values retained for old call sites and saved arguments, not Python enum aliases with the same string value. _LEGACY_BACKEND_BY_METHOD rewrites them only when the corresponding quantization method is known. A legacy member not mapped for a method is not automatically a valid backend for that method.
| Legacy member | String value | Method-dependent normalization |
|---|---|---|
TORCH_FUSED |
torch_fused |
gptq → GPTQ_TORCH_FUSED; awq → AWQ_TORCH_FUSED
|
TORCH_INT8 |
torch_int8 |
gptq → GPTQ_TORCH_INT8; awq → AWQ_TORCH_INT8
|
TORCH |
torch |
gptq → GPTQ_TORCH; awq → AWQ_TORCH; fp8 → FP8_TORCH; exl3 → EXL3_TORCH; vptq → VPTQ_TORCH
|
TRITON |
triton |
gptq → GPTQ_TRITON
|
EXLLAMA_V2 |
exllama_v2 |
gptq → GPTQ_EXLLAMA_V2; awq → AWQ_EXLLAMA_V2
|
EXLLAMA_V3 |
exllama_v3 |
exl3 → EXL3_EXLLAMA_V3
|
MACHETE |
machete |
gptq → GPTQ_MACHETE; awq → AWQ_MACHETE
|
SWORDFISH |
swordfish |
gptq → GPTQ_SWORDFISH; awq → AWQ_SWORDFISH
|
MARLIN |
marlin |
gptq → GPTQ_MARLIN; awq → AWQ_MARLIN
|
BITBLAS |
bitblas |
gptq → GPTQ_BITBLAS; awq → AWQ_BITBLAS
|
GEMM |
gemm |
awq → AWQ_GEMM
|
GEMM_TRITON |
gemm_triton |
awq → AWQ_GEMM_TRITON
|
GEMV |
gemv |
awq → AWQ_GEMV
|
GEMV_FAST |
gemv_fast |
awq → AWQ_GEMV_FAST
|
TORCH_INT8_AWQ |
torch_int8_awq |
awq → AWQ_TORCH_INT8
|
TORCH_FUSED_AWQ |
torch_fused_awq |
awq → AWQ_TORCH_FUSED
|
TORCH_AWQ |
torch_awq |
awq → AWQ_TORCH
|
BITBLAS_AWQ |
bitblas_awq |
awq → AWQ_BITBLAS
|
PARO |
paroquant |
paroquant → PAROQUANT_CUDA
|
normalize_backend(None) returns None; a blank or whitespace-only string also returns None. The selector resolves the absence of an explicit backend to AUTO. Nonempty strings are stripped and can match enum values case-insensitively or member names. Unknown backend names raise ValueError; non-string, non-enum inputs raise TypeError. Method-aware normalization is why a legacy "torch" can mean GPTQ Torch, AWQ Torch, FP8 Torch, EXL3 Torch, or VPTQ Torch rather than one universal kernel.
| Family | Actual requirement / important restriction |
|---|---|
| GPTQ Marlin | CUDA, not ROCm; compute capability 7.5 or newer; extension availability and per-layer shape validation. SM75 has BF16 handling distinct from native BF16-capable devices. Bits 4 and 8 are declared. |
| AWQ Marlin | CUDA, not ROCm; compute capability 8.0 or newer; Marlin/AWQ shape, type, and packing checks still apply. |
| Machete | CUDA, not ROCm; capability exactly 9.0; at least 204800 bytes of opt-in shared memory per block; generated CUTLASS kernels target sm_90a. A newer Blackwell GPU is not accepted as a Hopper substitute. The helper pins CUTLASS 4.7.1 and verifies its source archive. |
| Swordfish | CUDA, not ROCm; supported capability targets derived from its build flags include 10.0, 10.3, and 11.0, rather than every device with capability at least 10.0. The runtime checks the Torch stable ABI requirement as well as extension availability. GPTQ supports 4/8-bit; AWQ supports 4-bit. Both require input/output widths divisible by 64 and reject sharded loading. |
| ExLlama v2 | The class declares CUDA and 4-bit weights, with FP16/BF16 interface dtypes. The native GEMM executes in FP16; forward casts other input dtypes. Native extension availability, dimension constraints, and scratch initialization are required. AWQ has its own GEMM-to-ExLlama adaptation class. |
| BitBLAS | CUDA with BitBLAS/TVM runtime support; GPTQ declares 2/4/8-bit and AWQ declares 4-bit. Transformed packing and target detection are part of the runtime, not an interchangeable GPTQ tensor layout. |
| Native AWQ GEMM | Native CUDA AWQ extension. validate_once() explicitly rejects ROCm even though several other AWQ implementations have ROCm declarations. |
| W4A FP8 |
W4AFP8Linear.MIN_COMPUTE_CAPABILITY = (8, 9); Triton FP8 support. This is more precise than the broad SM12x comment beside the backend enum. |
| W4A NVFP4 |
W4ANVFP4Linear.MIN_COMPUTE_CAPABILITY = (12, 1); native torch.float4_e2m1fn_x2, torch.nn.functional.scaled_mm, ScalingType, SwizzleType, and the activation-packing Triton module. Do not infer support from Swordfish's SM100 support. |
Extension importability is not proof that the selected device is supported. Marlin, Machete, and Swordfish retain device-sensitive checks; the selector preserves exact GPU ordinals so the currently active CUDA device cannot stand in for another GPU in a device map.
| Target | Selection considerations |
|---|---|
| CPU INT4, AVX512-BF16 |
GPTQ_TORCH_CPU_AVX512 / AWQ_TORCH_CPU_AVX512 use the native int4_qzero_group_scaled_cpu implementation and require AVX512-BF16 support. An AVX512-branded CPU without the required BF16 feature is not enough. |
| CPU ATen INT4 |
GPTQ_TORCH_ATEN / AWQ_TORCH_ATEN require _convert_weight_to_int4pack_for_cpu and _weight_int4pack_mm_for_cpu. GPTQ group sizes are 32, 64, 128, or 256; the backend can validate on hosts that lack the specialized AVX512 path. |
| CPU Torch fused | The fused family declares CPU and XPU. Availability depends on the installed Torch/torchao/operator path; its runtime layout differs from checkpoint GPTQ/AWQ. |
| CPU native 8-bit |
GPTQ_TORCH_INT8 is explicit-only and declares 8-bit, not 4-bit-to-8-bit expansion. It uses _weight_int8pack_mm; raw packing is disabled. |
| Retired AWQ INT8 |
AWQ_TORCH_INT8 remains in the enum only to issue an actionable migration error. Its constructor and validate_once() reject use; select AUTO or AWQ_TORCH. |
| Intel XPU | Torch fused is an explicit declared XPU candidate; generic Torch can provide a portable path. Do not read XPU-aware code in a module as proof that the module's selector declaration accepts XPU. The full declaration table is in Kernel Backends Reference. |
| ROCm | PyTorch uses the cuda device namespace for HIP; selection distinguishes DEVICE.ROCM. CUDA-only native Marlin, Machete, Swordfish, and AWQ GEMM do not become HIP kernels. Generic Torch and other ROCm-declaring families remain candidates where their own checks pass. |
| Apple Silicon / MLX | MLX is a model conversion/execution path with checkpoint-holder classes, not an ordinary Torch MPS qlinear forward. Holders must be converted into method-specific MLX modules before inference. Loader-level AUTO may choose MLX separately from the generic zero-priority holder declarations. |
docs/rocm-quant-blas-backend.md describes quantization-time BLAS selection, not a new inference backend. quant_blas_backend() and GPTQMODEL_ROCM_QUANT_BLAS control the hipBLASLt/rocBLAS quantization context. Changing that setting does not enable a CUDA-only inference extension on ROCm.
The GPTQ Triton v2, AWQ GEMM Triton, ParoQuant Triton, and GGUF Triton validators check Triton availability/version. Their shared minimum is 2.0.0; on free-threaded Python with the GIL disabled, the validators require 3.4.0 or newer. W4A validators additionally check the particular modules/operators needed by their FP8/FP4 paths. The name TritonV2Linear does not pin installation to Triton 2.x.
The package declares Python 3.10 or newer. Optional dependency requirements in pyproject.toml are separate from the minimum checks embedded in individual kernel validators; passing an older validator threshold does not mean it satisfies the current installation extra.
| Optional extra | Requirement declared at this revision |
|---|---|
triton |
triton>=3.8.0 when Python is below 3.15. The extra has no applicable Triton requirement on Python 3.15 or newer; that is not a runtime-support guarantee. |
bitblas |
bitblas==0.1.0.post1; the module's validator minimum is 0.1.0.post1. |
bitsandbytes |
bitsandbytes>=0.50.2. |
gguf |
gguf>=0.19.0 and llama-cpp-python>=0.3.36. |
mlx |
mlx>=0.32.4; mlx_lm>=0.31.3 below Python 3.11, otherwise mlx_lm>=0.32.2. Apple Silicon/Metal validation still applies. |
vllm |
vllm>=0.31.0 below Python 3.11; vllm>=0.32.0 on Python 3.11 through 3.14. There is no applicable requirement in this extra on Python 3.15 or newer. |
sglang |
sglang[srt]>=0.5.21 below Python 3.11; sglang[srt]>=0.5.22 on Python 3.11 or newer. |
The engine extras carry their own Torch/Transformers pins; use a dedicated environment for each engine rather than assuming it shares the local-kernel dependency set. Installing an extra does not waive architecture, operator, checkpoint-format, or native-build requirements.
| Checkpoint / path | Loader behavior |
|---|---|
| Serialized Marlin, local loader | AUTO becomes GPTQ_MARLIN or AWQ_MARLIN according to the method. Explicit local selection must match that backend, or use MLX conversion. A class declaring Marlin-format support does not bypass this loader restriction. |
| Serialized BitBLAS, local loader | AUTO becomes GPTQ_BITBLAS or AWQ_BITBLAS according to the method. Explicit local selection must match that backend, or use MLX conversion. |
| EXL3 | Accepts AUTO, EXL3_EXLLAMA_V3, EXL3_TORCH, or MLX. In this branch, AUTO chooses native ExLlama v3 when torch.cuda.is_available() is true and the selector family is CUDA/ROCm; otherwise it chooses Torch. This branch does not probe native-extension build success before choosing the native backend, so an extension failure is not an automatic retry with Torch. Native EXL3 loading requires CUDA/HIP and a matching selector family. |
| bitsandbytes | Accepts AUTO, BITSANDBYTES, or MLX. AUTO becomes BITSANDBYTES in this branch. The local class declares CPU and CUDA, 4/8-bit. |
| Native GGUF Q1_0 | Loader restricts selection to AUTO, GGUF_TORCH, GGUF_TRITON, or MLX. A generic GGUF class's broad bit list is not sufficient to override this qtype-level rule. |
| Native GGUF Q2_0 | AUTO becomes GGUF_TORCH; explicit selection must be GGUF_TORCH or MLX. |
| AWQ GEMV_FAST / LLM_AWQ | The loader coerces the model dtype to torch.float16; these formats are not interchangeable with AWQ GEMM. |
| vLLM | External-loader format allowlist: GPTQ and GEMM. Runtime support also depends on the installed vLLM version and its own kernels. |
| SGLang | External-loader format allowlist: GPTQ, GPTQ_V2, GEMM, and MARLIN. Engine initialization and generation are delegated to the SGLang integration. |
The external-engine paths return a wrapper with qlinear_kernel=None before the local Marlin/BitBLAS restrictions above. They use their own format allowlists, not generic local qlinear selection; selecting them does not promise that the engine implements every GPTQModel local format. See Serving.
normalize_profile() accepts enum members, case-insensitive names/values, and the integer aliases below. String names may use spaces or hyphens in place of underscores. None and an empty/whitespace string resolve to AUTO; an unknown integer/name or an unsupported type raises an error.
| Profile | Value | Integer alias | Native Q1_0 behavior in from_pretrained() with no quantization configuration |
|---|---|---|---|
PROFILE.AUTO |
"auto" |
0 |
Resolves to FAST. |
PROFILE.FAST |
"fast" |
1 |
Uses the dense Hugging Face GGUF import path. A non-AUTO backend is logged as ignored on this path. |
PROFILE.LOW_MEMORY |
"low_memory" |
2 |
Does not take the dense FAST branch; native GGUF detection redirects to quantized loading. |
This is a loader-path decision, not a universal speed/memory switch on every qlinear class. GPTQModel.load() forwards profile through its from_pretrained() branch; its already-quantized from_quantized() branch does not forward this parameter. In particular, Q1_0 FAST can materialize dense weights even though the source file is quantized. Use LOW_MEMORY when entering the native GGUF detection path to request packed execution, and still obey the qtype-specific backend restrictions above. See GGUF.
gptqmodel/utils/importer.py imports non-private modules under gptqmodel.nn_modules.qlinear. Import failures caused by ImportError or OSError can exclude optional modules. It walks BaseQuantLinear subclasses, retaining selectable classes with format declarations, then builds:
| Mapping | Purpose |
|---|---|
AUTO_BACKEND_KERNEL_MAPPING |
Method → format → backend/class candidates in AUTO order. |
BACKEND_TO_METHOD_FORMAT_MAPPING |
Method/format/backend support lookup, including explicit-only declarations. |
SUPPORTS_FORMATS maps format enums to integer priorities. Positive priorities participate in AUTO; zero or negative priorities do not. Candidates are sorted by descending priority and backend string value; duplicate backend entries are removed in the resulting order. AUTO is therefore format-specific, not one global ranking of backend names.
For example, CPU AVX512 has GPTQ priority 120 and CPU ATen 110, while Swordfish has GPTQ priority 101, Machete 100, Marlin 90, ExLlama v2 80, Torch fused 50, Triton 40, BitBLAS 30, and Torch 20. Device, dtype, shape, and availability checks eliminate incompatible candidates. These numbers do not say that a CPU backend runs on CUDA, or that any candidate is a measured speed winner. The complete declarations, including AWQ, GGUF, and method-specific priorities, are in Kernel Backends Reference.
def select_quant_linear(
        bits,
        group_size: int,
        desc_act: bool,
        sym: bool,
        device: Optional[SelectorDevices],
        backend: BACKEND = BACKEND.AUTO,
        format: FORMAT = FORMAT.GPTQ,
        quant_method: METHOD = METHOD.GPTQ,
        pack: bool = False,
        allow_marlin: bool = True,  # TODO: remove this after marlin padding is fixed
        dynamic=None,
        pack_dtype: torch.dtype = None,
        dtype: Optional[torch.dtype] = None,
        multi_select: bool = False, # return all valid kernels
        adapter: Optional[Adapter] = None,
        is_sharded: bool = False,
) -> Union[Type[BaseQuantLinear], List[Type[BaseQuantLinear]]]:
    ...
The selector performs the following operations:
- Normalize format and method strings to enums, resolve method-dependent backend names, normalize devices without losing ordinals, and normalize the requested bit width.
- Reject unknown method/format combinations and incompatible device-family/capability combinations.
- For AUTO or AUTO_TRAINABLE, iterate the generated candidates. Respect
allow_marlin, declared device families, and sharded-load restrictions. - Validate each candidate against bits, group size, symmetry, activation ordering, pack dtype, activation dtype, dynamic overrides, trainability, and adapter support. Exact targets in a multi-device selector are checked individually.
- When
pack=True, additionally require a supported raw packing API.SUPPORTS_RAW_PACKING=Falseexcludes classes even if they can load an already-packed checkpoint. - Return the first valid class, or all qualifying classes when
multi_select=True. If nothing validates, propagate the last validation error where available, otherwise raise a no-valid-kernel error.
For multi-select with dynamic overrides, the code enumerates effective base/dynamic contracts and retains a class if it can handle an effective contract. This allows different classes to serve different layer contracts later; it does not mean every returned class supports every layer. Single-select retains a model-wide validation contract with the full dynamic map.
Adapter validation has an implementation asymmetry: AUTO forwards adapter into candidate validation, but the explicit-backend branch of select_quant_linear() does not forward it to validate_candidate(). A successful explicit selector call alone therefore does not establish adapter compatibility; check the class's adapter declarations and construction/runtime checks.
AUTO_TRAINABLE sets trainable=True during validation. It selects implementations that declare training support; it is not a promise that packed integer weights become ordinary trainable floating parameters. Adapter handling and the class's actual autograd implementation remain relevant. See EoRA.
hf_select_quant_linear and hf_select_quant_linear_v2 are integration-facing wrappers around this selection machinery. Use the wrapper signature appropriate to the integration; do not maintain a separate hard-coded backend ranking in external code.
validate_quant_linear() uses a bounded, thread-safe cache with a maximum of 1024 entries. Keys incorporate the class's validation implementation, immutable contract values, and device descriptors/capability. Cached failures retain exception type/message metadata rather than mutable exception instances with traceback references; callers receive newly constructed exceptions.
The selector deduplicates device entries in first-seen order. For a concrete multi-device selector, it validates every retained exact ordinal. hf_normalize_device_device_map() ignores Accelerate "disk" entries and, when accelerator entries exist, excludes CPU offload entries from accelerator-kernel selection; an all-CPU map retains CPU as its target. Symbolic Accelerate placement keywords resolve to a selector device rather than an already-expanded list of final ordinals. Thus selection must not be described as validating a GPU kernel for every CPU/disk offload entry. Accelerator-family mixtures and CUDA/ROCm devices with different compute capabilities are rejected by the relevant device-family check; a kernel valid on the first GPU is not assumed valid on the others. This is distinct from quantization-time device pools described in Memory, Offload, and Multi-GPU.
gptqmodel/nn_modules/converter.py currently defines an empty MODULE_CONVERTER_MAP. It includes a text-decoder-config helper and notes architectures handled by Defuser during model loading. It is not the authoritative backend dispatch table, and it is not a general checkpoint-format conversion service.
Backend selection is handled by utils/importer.py; layer packing/repacking is handled by utils/packing.py and kernel methods. Model-architecture conversion and quantized tensor packing are separate operations.
hf_pack_layer() receives an already-instantiated kernel module and the quantizer's original linear layer, scales, zeros, and optional activation-order index. It dispatches the module's pack, pack_original, pack_block, or pack_gpu implementation. QQQ and AWQ follow their own single-pack() branches.
| Packing control | Behavior |
|---|---|
pack_impl=None |
Normalizes to "original" for this API. |
"original", "pack_original"
|
Original packer. |
"auto", "default"
|
Prefer GPU packing when CUDA/HIP is available and the module has pack_gpu; otherwise block packing when present, then original. Embeddings do not take the GPU-packing path. |
"cpu", "block", "pack_block"
|
Block packer where implemented; otherwise log a warning and fall back to original. |
"gpu" |
GPU packing where available; otherwise warn and use original. Packed output buffers are registered on CPU; this option accelerates packing math rather than setting the final inference placement. |
Missing zeros
|
Symmetric modules can synthesize 2 ** (bits - 1); asymmetric packing without zeros raises. |
hf_repack_layer() selects the destination class using the source method/format and either calls a native repack hook or copies a shared checkpoint layout before destination post_init(). It returns the source unchanged when the requested backend/class already matches. A source already transformed into certain private runtime ABIs is rejected; repack from the checkpoint-layout holder instead.
Runtime initialization can allocate workspace, prepack tiles, shuffle scales/zeros, establish native handles, or create hardware operand buffers. This is why directly copying qweight into a different class and immediately calling forward() is not a supported general conversion procedure. ExLlama v2 initialization additionally needs its scratch-space arguments.
gptqmodel/nn_modules/qlinear/_runtime_cache.py supplies tensor_cache_key() for safely identifying tensor-backed cached state. The key accounts for tensor identity, version where available, data pointer, device, dtype, shape, and inference-tensor status. A shape/data-pointer-only key would miss in-place updates or allocator reuse.
The helper is not a global model cache and is not a disk checkpoint cache. Its source documents invalidation on state-dict load, device/dtype movement, and training transitions in the classes that own packed-weight caches. Inference tensors can be mutated inside InferenceMode without a normal version counter; callers that do so must call the module's clear_weight_cache() explicitly. Kernel-specific buffers and initialization rules still apply; the helper does not rebuild a private runtime ABI automatically.
For kernel development, distinguish permitted packed quantized state from a dense or expanded weight cache. The repository's storage policy forbids retaining expanded/dequantized weights between operations; an implementation using temporary dequantization must release it after its consuming operation. Inspect a backend's actual memory behavior rather than assuming that persistent=False means it occupies no memory. W4A's retained full-layer INT4-to-E4M3 expansion is a current storage-policy limitation, not an exemption; checkpoint INT4 size alone is not a runtime memory estimate.
| Symptom / assumption | What to check |
|---|---|
| Explicit backend fails but AUTO loads | The explicit class may require a different architecture, format, dtype, group size, extension, or unsharded checkpoint. Read the validation error before reinstalling the package. |
| A newer GPU cannot run Machete | Current Machete kernels target Hopper sm_90a, not an open-ended SM90+ range. Use a compatible alternative on Blackwell. |
| NVFP4 fails on a Swordfish-compatible GPU | W4A NVFP4 checks capability 12.1+, while Swordfish targets 10.x/11.0 variants. These are different kernels. |
AWQ_TORCH_INT8 raises immediately |
This backend is retired intentionally, not a missing optional dependency. |
| A class appears to support the bit width but loading fails | Check checkpoint format, tensor qtype, shapes, group size, symmetry, desc_act, dtype, pack dtype, and loader-specific restrictions. |
| A class can load but cannot pack | Loading/repacking and raw float-weight packing have different contracts. Inspect SUPPORTS_RAW_PACKING and the pack API. |
| A sharded model fails with Swordfish | Its classes explicitly set SUPPORTS_SHARDED_LOAD=False. |
| Optional backend absent from AUTO | The module may not import, have priority zero, fail runtime validation, or be excluded by the active format/device. |
| A custom mutation produces stale results | Invalidate the owning module's weight cache and re-run any required post-initialization; inference-tensor mutation cannot always be detected automatically. |
| Multi-GPU inference works differently from multi-GPU quantization | Inference device_map and quantization dense/MoE calculation pools are different mechanisms. |
pyproject.tomlgptqmodel/utils/backend.pygptqmodel/utils/importer.pygptqmodel/models/auto.pygptqmodel/models/loader.pygptqmodel/nn_modules/converter.pygptqmodel/nn_modules/qlinear/__init__.pygptqmodel/nn_modules/qlinear/_runtime_cache.pygptqmodel/utils/packing.pygptqmodel/utils/marlin.pygptqmodel/utils/machete.pygptqmodel/utils/swordfish.pygptqmodel/nn_modules/qlinear/torch_int8_awq.pygptqmodel/nn_modules/qlinear/w4a_floatx.pygptqmodel/nn_modules/qlinear/w4a_nvfp4.pydocs/torch_fused_int4_transformations.mddocs/rocm-quant-blas-backend.md